

How to Fix Acrobat OCR Not Converting Scanned PDF Text

Question details
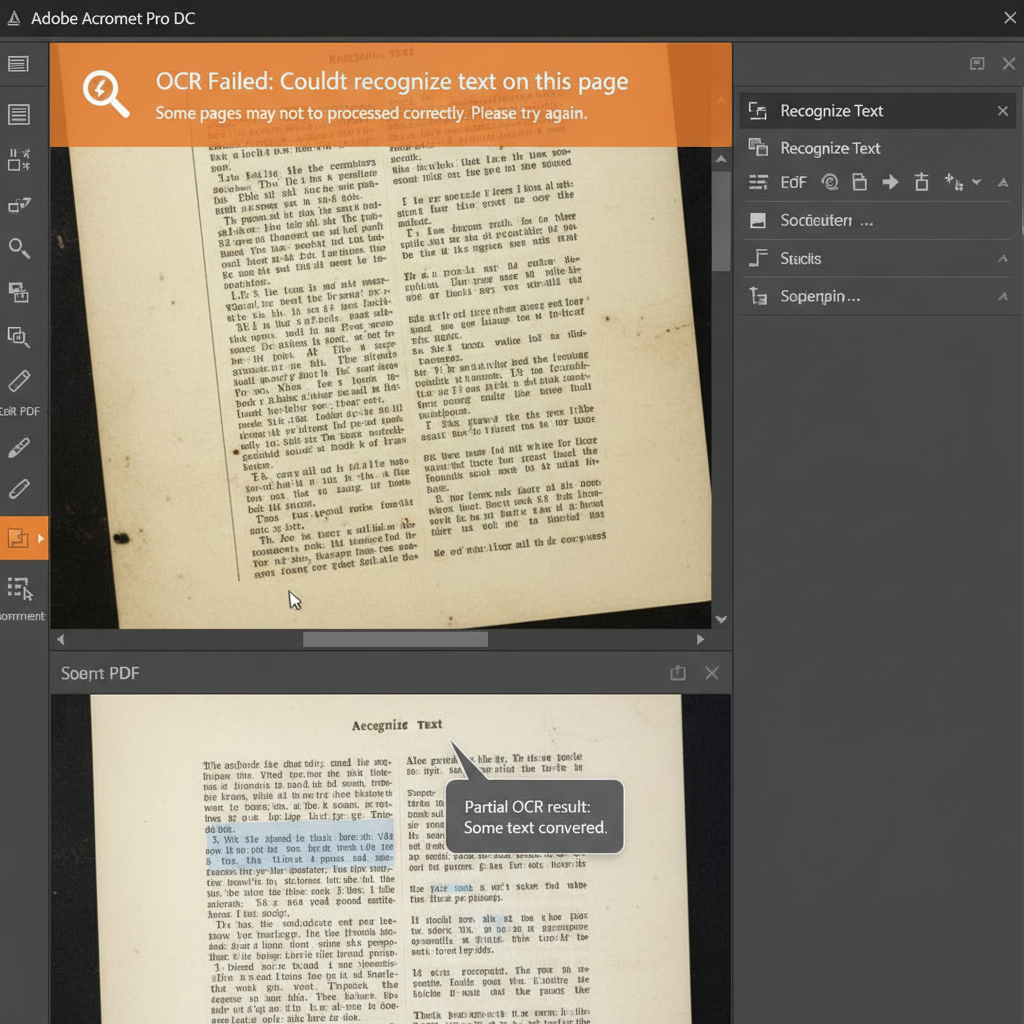
The user needs to convert scanned PDF pages into editable or searchable text, but the OCR tool fails to process the document correctly.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to edit or search text within a scanned PDF document.
- Observed behavior
- Acrobat displays the scanned pages as images instead of editable or searchable text, and the OCR process may fail without clear error messages or only partially convert the text.
Ensure that the scanned PDF does not have security restrictions preventing editing, and verify that the document resolution is high enough (at least 300 DPI) for accurate text recognition.
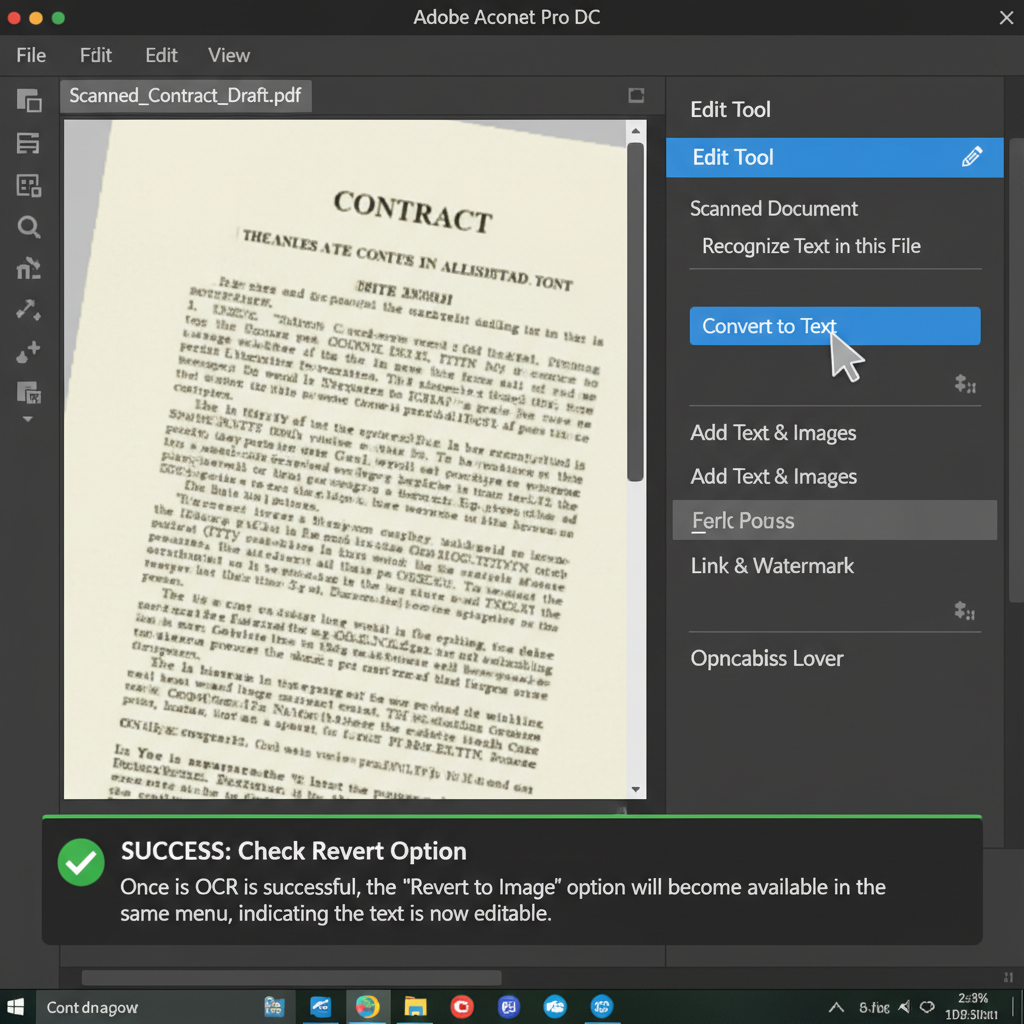
Use the Convert to Text Option in the Edit Tool
Trigger the OCR process directly from the Edit menu to force Acrobat to recognize the text on the scanned image.
This is the most direct way to check if Acrobat recognizes the document as a scanned image and to initiate the built-in OCR process.
Launch Adobe Acrobat and open the scanned PDF document you want to edit.
Click on the 'Edit PDF' tool located in the right-hand pane of the Acrobat interface.
Look under the 'Scanned Document' section in the right pane. If 'Convert to Text' is available, click it to run the OCR and recognize the text.
Run Enhance Scans with Editable Text & Images Settings
Use the Enhance Scans tool with specific settings to ensure Acrobat forces text recognition on the entire file.
Convert Scanned PDFs to Text Instantly with WPS Office
If Acrobat fails to process your scanned documents, WPS Office offers a powerful, built-in OCR feature that accurately extracts text from images and scanned PDFs, making them fully editable in seconds.
- 1. Open PDF in WPS Office: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and click on the 'OCR' button in the toolbar.
- 3. Select Extraction Mode: Choose 'Extract Text' or 'Convert to Word' depending on whether you want to copy the raw text or edit it as a fully formatted document.
- 4. Start Recognition: Select the pages you want to process and click 'Start' to accurately convert your scanned pages into editable text.

Frequently Asked Questions
Why does Acrobat OCR fail on documents downloaded from academic sources?
Academic documents often contain complex layouts, unusual fonts, or restricted permissions. These elements can confuse the OCR engine, causing it to skip sections or fail entirely. Removing PDF restrictions or using a dedicated OCR tool like WPS PDF can often bypass these limitations.
How can I tell if OCR is working in Acrobat?
When OCR is actively running, Acrobat typically shows a progress bar at the bottom right of the screen. If the process completes successfully, you will be able to select, highlight, and modify the text using the 'Edit PDF' tool.
What should I do if Acrobat only converts half of my scanned PDF text?
Partial conversion usually happens due to varying scan quality, shadows, or low resolution on certain pages. Try scanning the physical document again at a higher resolution (300 DPI minimum) or use the 'Enhance Scans' feature to improve document clarity before running the 'Recognize Text' command.


