

Fix Acrobat DC OCR Finds No Text in Scanned PDF Issue

Question details
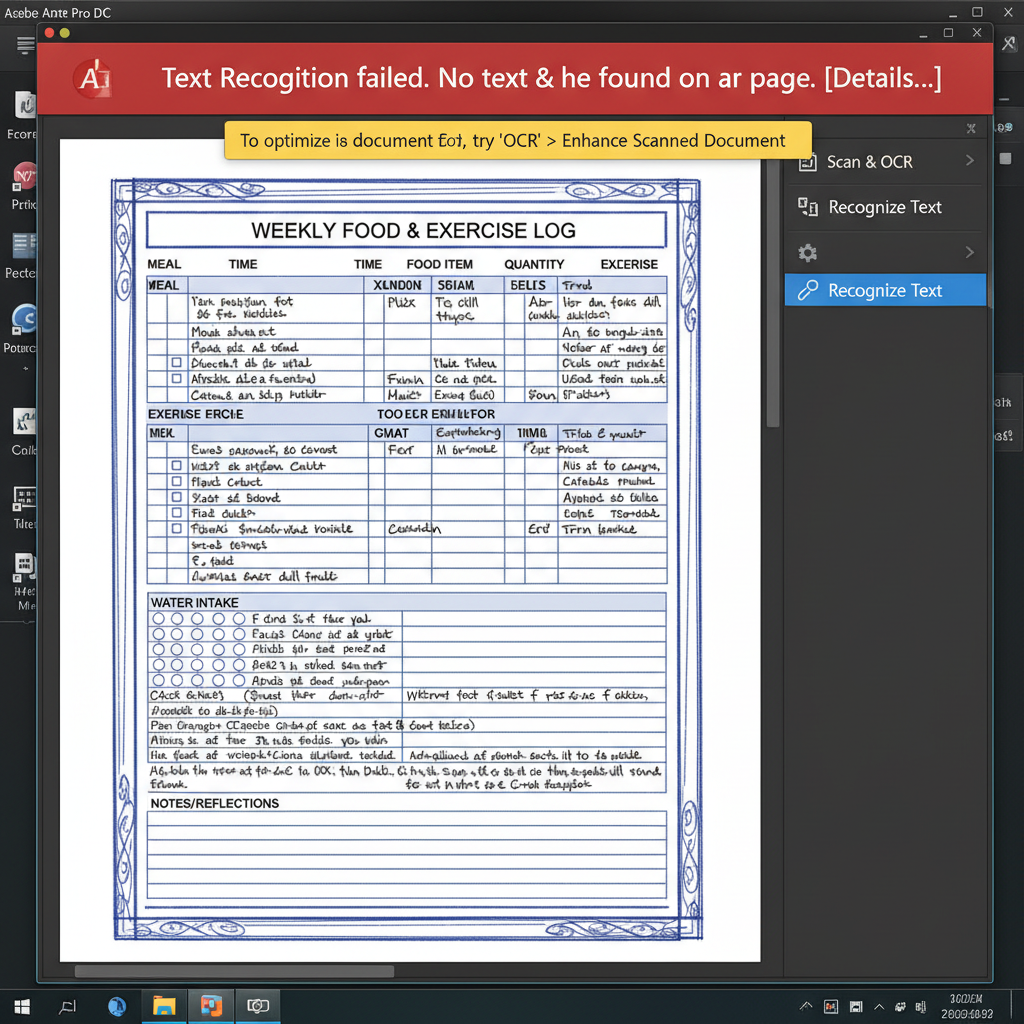
The user needs to make a scanned PDF searchable, but Adobe Acrobat Pro DC's OCR tool reports that no text was found, despite older software versions handling similar files successfully.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Attempting to run text recognition (OCR) on a scanned document with complex layouts, such as a printed food diary containing tables, lines, and borders.
- Observed behavior
- Acrobat Pro DC completes the OCR process but displays an error or simply states "no text was found," resulting in a PDF that is still not searchable.
Before modifying your OCR settings, ensure that your PDF is actually a flat scanned image and check that you have the original, uncompressed scan file available in case re-processing is necessary.
Adjust Recognize Text Settings and OCR Language
Modifying the OCR settings and ensuring the correct language is selected can resolve text recognition failures caused by image processing differences in Acrobat DC.
Acrobat DC uses an updated OCR engine compared to older versions. Default settings like "Editable Text and Images" might struggle with complex table borders, so switching to standard Searchable Image modes often yields better results.
Launch Adobe Acrobat DC, open your problematic PDF document, and select "Scan & OCR" from the right-hand Tools pane.
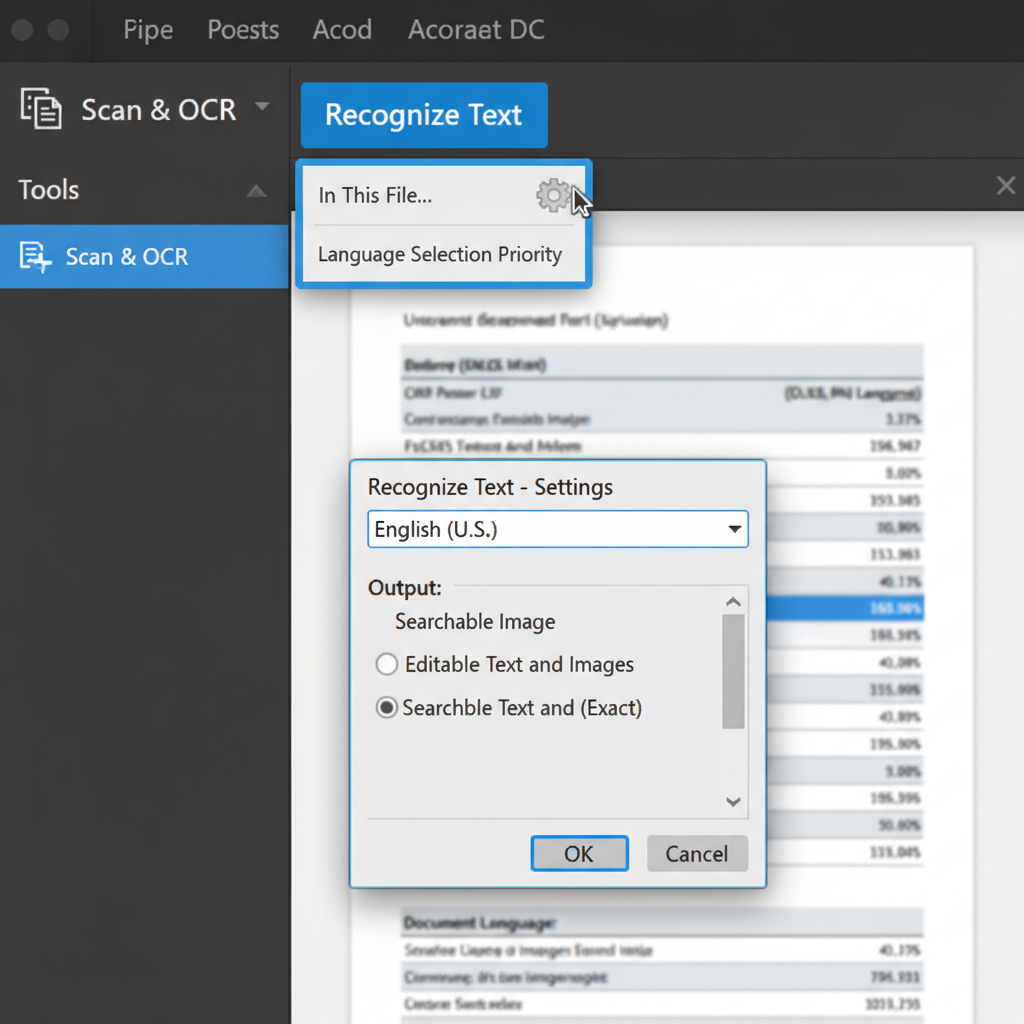
Click on "Recognize Text" in the toolbar and select "In This File". Before clicking the blue Recognize Text button, click the "Settings" gear icon.
Ensure the "Document Language" exactly matches the text in your scan. Change the Output style from "Editable Text and Images" to "Searchable Image" or "Searchable Image (Exact)".
Click "OK" to save your settings, then click "Recognize Text" to scan the document again and verify if the text becomes selectable.
Improve Source Image Quality and Resolution
Low image quality, aggressive compression, or thick table lines can prevent the OCR engine from distinguishing characters from the background.
Use WPS Office to Extract and Recognize Text in PDFs
If Acrobat DC's OCR engine continues to struggle with heavily formatted documents or tables, WPS Office provides a highly accurate, built-in OCR tool. It can effortlessly convert complex scanned images and forms into fully editable Word documents or searchable PDFs.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the "Tools" tab on the top ribbon and click on the "OCR" button.
- 3. Select Output Mode: Choose whether you want to extract the text directly, convert the file to a searchable Word document, or create a searchable PDF.
- 4. Start Recognition: Select the appropriate document language, specify the page range, and click "Confirm" to let WPS Office extract the text accurately.

Frequently Asked Questions
Why does Acrobat say 'renderable text exists' when I try to run OCR?
This error occurs because the PDF already contains a layer of selectable text, vector graphics, or embedded fonts, meaning it isn't a completely flat image. OCR is designed for images only. You must print the PDF as an image or use the 'Flatten' tool before running OCR.
Can table borders and gridlines affect OCR accuracy?
Yes, dense gridlines, dark backgrounds, or thick table borders can confuse the OCR engine, causing it to misinterpret actual text as part of an image artifact or ignore it entirely. Improving the image contrast helps resolve this.
Why did Acrobat X Pro recognize my text but Acrobat DC failed?
Acrobat DC utilizes a completely different, updated OCR engine that processes image artifacts, compressions, and contrast differently than older legacy versions like Acrobat X. Adjusting the newer engine's output style to 'Searchable Image' usually restores the expected functionality.
What is the ideal DPI for OCR text recognition in PDFs?
A scan resolution of 300 DPI is generally considered the optimal standard for OCR. Resolutions significantly lower than 300 DPI may result in unreadable text, while extremely high resolutions (like 1200 DPI) can crash the OCR processor or slow it down without adding accuracy.


