

Fix Acrobat OCR Producing Incorrect Text and Fragmented Images

Question details
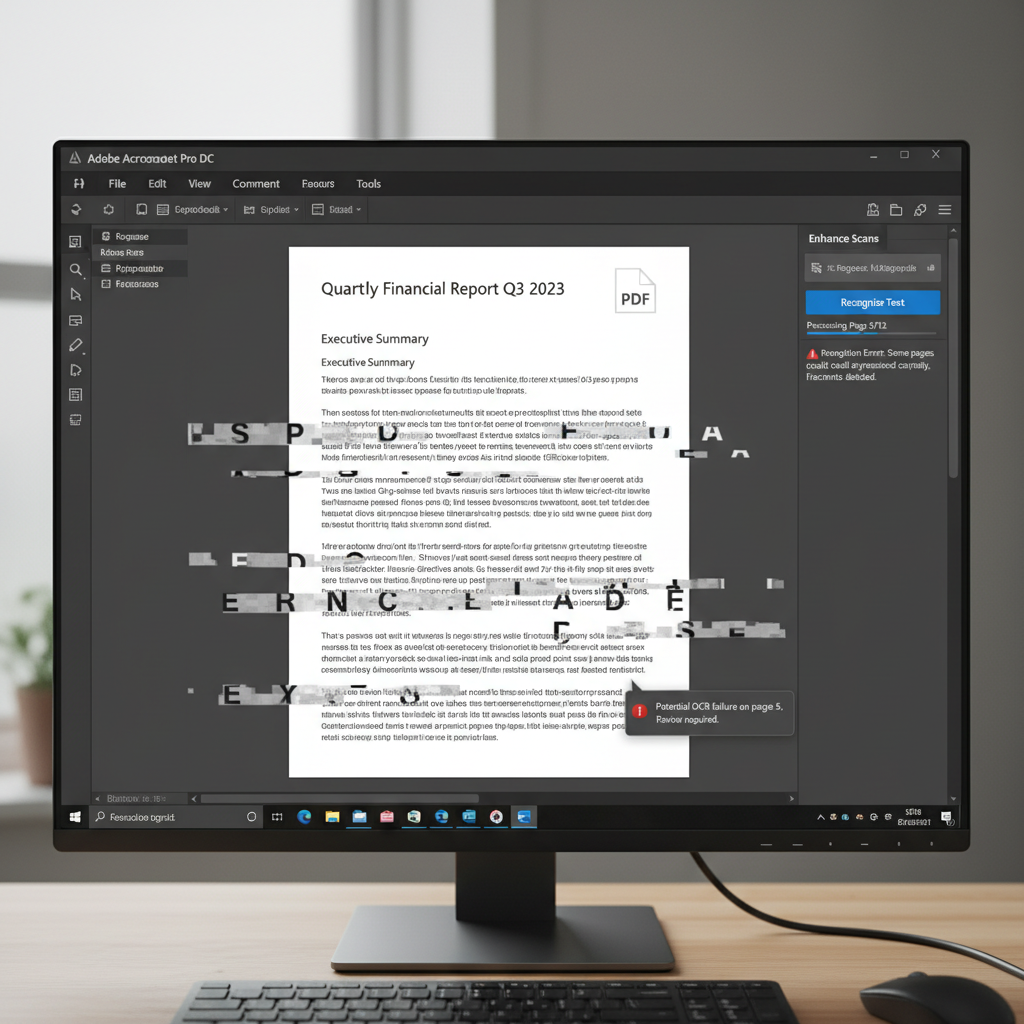
Users report that Acrobat's Enhance Scans and OCR features are incorrectly processing pages, cutting letters in half, and converting document content into fragmented images instead of readable text.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running the Enhance Scans tool or OCR text recognition on scanned PDF documents.
- Observed behavior
- The OCR engine fails on occasional pages, inaccurately recognizing text by slicing letters in half and converting elements into fragmented background images or uneditable objects.
Ensure your original scanned documents are saved at a minimum resolution of 300 DPI and update Adobe Acrobat to the latest version to patch any known OCR-engine bugs.
Optimize Scan Quality and Preprocessing Settings
Adjusting Acrobat's preprocessing options to clean up the document before running OCR can significantly improve text recognition accuracy and prevent fragmentation.
Many OCR issues arise from poor contrast, page skewing, or visual noise in the original scan. Forcing Acrobat to clean up these elements beforehand provides a much better baseline for the OCR engine to define character boundaries.
Re-scan the original physical document, ensuring it is perfectly straight, clean, and has adequate contrast between the black text and white background.
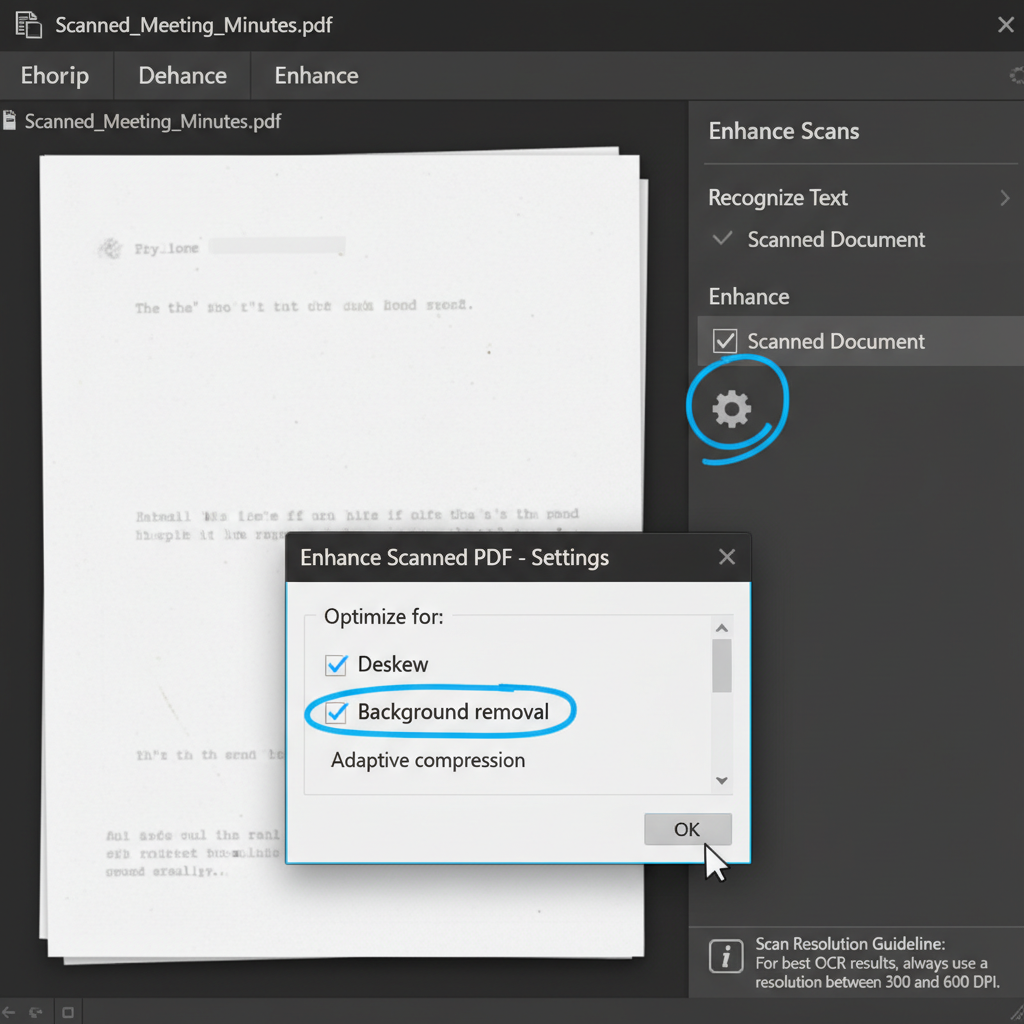
Launch Adobe Acrobat, go to the 'Tools' menu, and select 'Enhance Scans'.
Choose the 'Enhance' option and select 'Scanned Document'. Click on the settings gear icon to enable the 'Deskew' and 'Background removal' filters.
Click 'Recognize Text' and test the output. The preprocessing adjustments will help the engine detect full letters correctly without slicing them.
Report OCR Engine Regression Bug to Adobe
If high-quality, perfectly straight scans consistently fail on specific pages, it may be a software flaw or regression in Acrobat's latest OCR engine update.
Accurately Extract Text with WPS Office PDF OCR
If Acrobat's OCR engine is consistently flawed and frustrating to use, WPS Office provides a highly accurate, built-in OCR feature to seamlessly convert your scanned PDFs into editable text without fragmenting letters.
- 1. Open your PDF: Launch WPS Office and open the scanned PDF document you want to process.
- 2. Access OCR Tools: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select OCR mode: Choose 'Extract Text' or 'Convert to Word' depending on whether you want plain text or a fully editable, perfectly formatted document.
- 4. Confirm Language and Extract: Ensure the correct document language is selected from the dropdown, then click 'Extract' to quickly recognize and accurately convert your text.

Frequently Asked Questions
Why does Adobe Acrobat OCR cut letters in half?
This typically occurs when the original scan resolution is too low, the page is slightly skewed, or there is poor background contrast. These factors cause the OCR engine to misinterpret character boundaries, treating parts of words as fragmented images rather than readable text.
What is the optimal DPI setting for PDF OCR recognition?
For accurate text recognition in Acrobat or WPS Office, scanning your physical documents at exactly 300 DPI is strongly recommended. It provides enough detail for the software to parse characters cleanly without creating excessively large file sizes.
Can I fix fragmented text that has already been incorrectly processed by Acrobat OCR?
Once the OCR engine permanently converts text into background objects or fragmented images and saves over the file, you cannot easily revert the text natively. You must use a backup of the original un-OCR'd scan, apply deskewing and background removal to improve clarity, and run the OCR process again.


