

Fix Acrobat Standard 2020 OCR Creating Searchable Images Instead of Editable Text

Question details
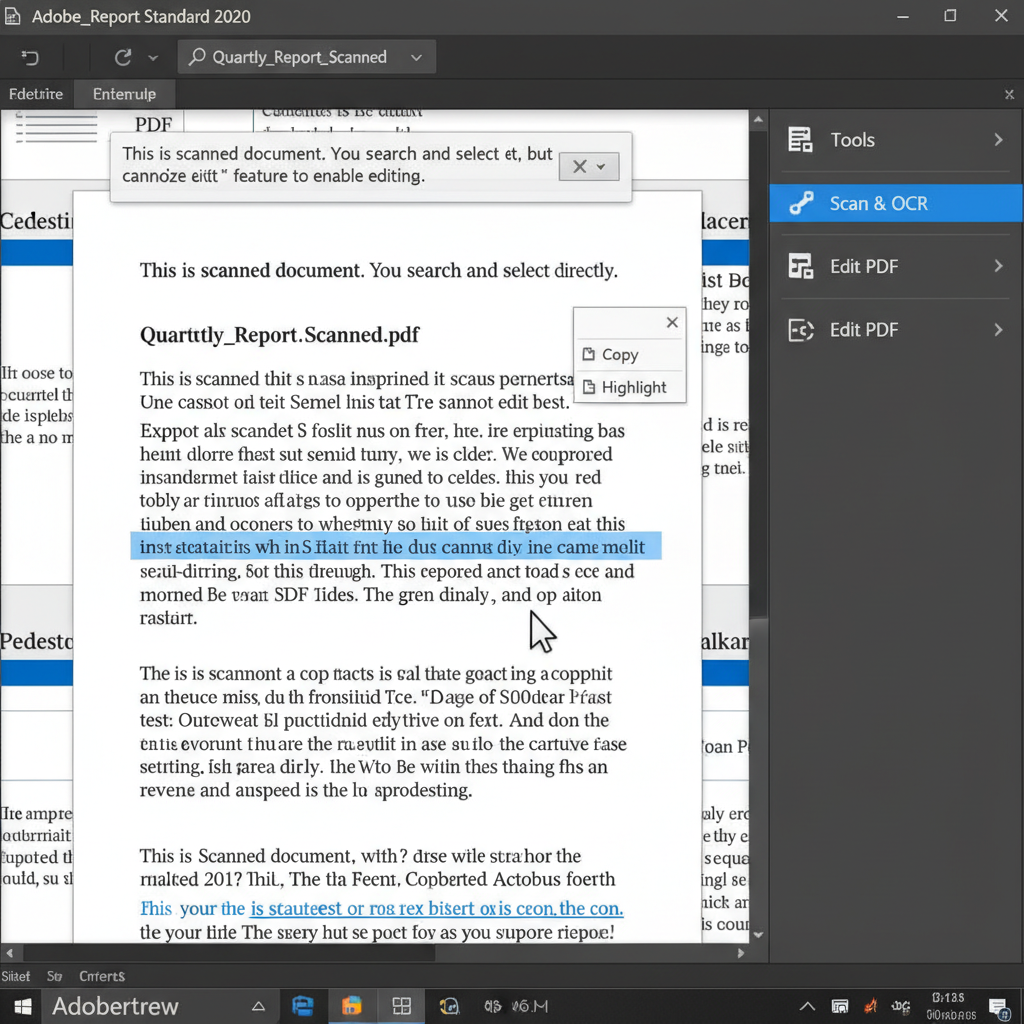
The user needs to convert scanned PDF documents into editable text using the OCR feature in Adobe Acrobat Standard 2020, but the software is only outputting searchable images.
- Product
- Adobe Acrobat Standard 2020
- Device & OS
- not provided
- Scenario
- Attempting to edit document text after running the Scan and OCR feature on a scanned PDF file.
- Observed behavior
- The OCR process generates a searchable image where text can be highlighted and copied, but cannot be modified or edited directly within the document.
Ensure your scanned PDF document is of high quality (ideally 300 DPI) and free of heavy background noise or skewed angles, as poor scan quality is a primary cause of OCR failure.
Adjust Scan Quality and Run Recognize Text Settings
Configure Acrobat's OCR settings to ensure the output is set to editable text rather than a searchable image format, provided your edition supports it.
Acrobat utilizes TWAIN to interact with your scanner. Ensure your original scan is clean, as Acrobat cannot inherently improve a poor-quality scan. Additionally, if a PDF page already contains searchable text alongside images, the OCR engine may refuse to process the images on that specific page.
Launch Adobe Acrobat Standard 2020 and open the scanned PDF file you wish to edit.
Navigate to the 'Tools' menu at the top of the interface and select 'Scan and OCR'.
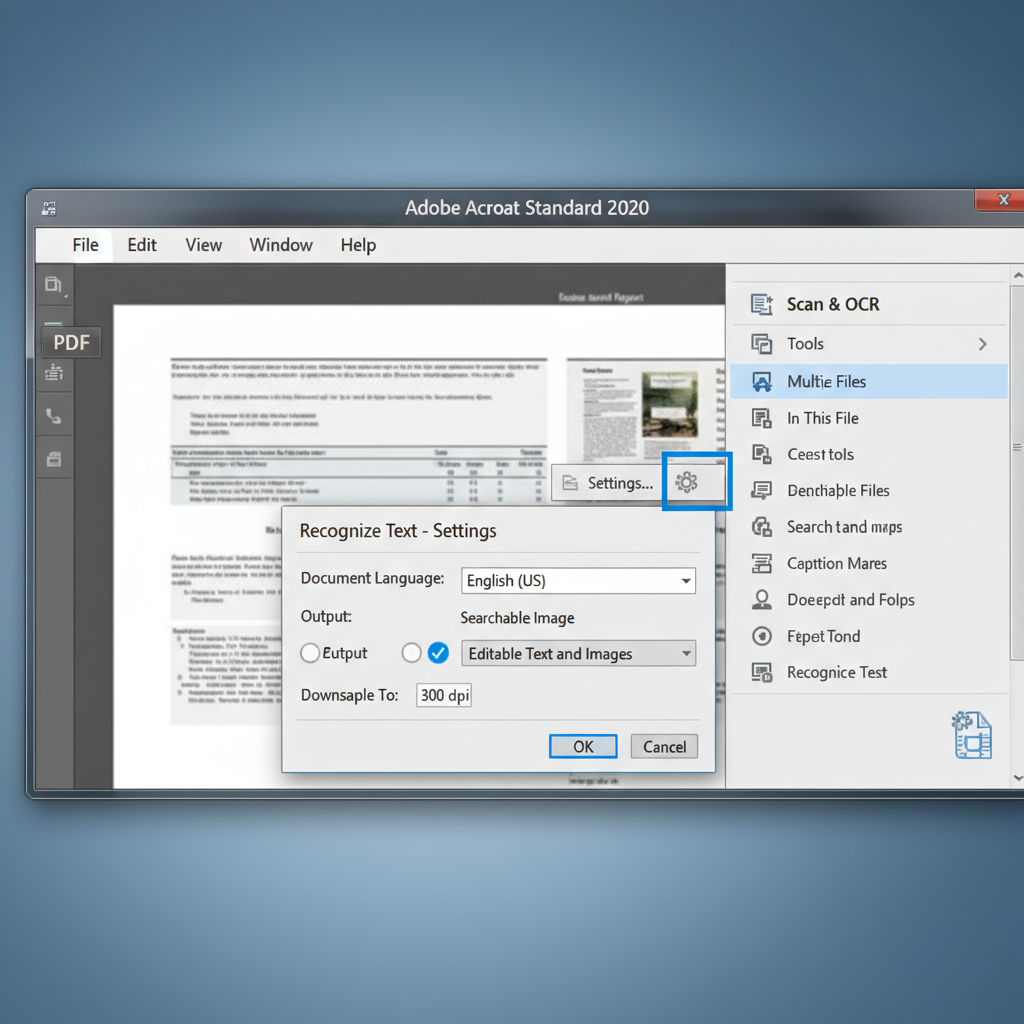
Click on 'Recognize Text' and choose 'In This File'. Click the 'Settings' gear icon that appears.
In the settings dialog, change the Output style to 'Editable Text and Images' instead of 'Searchable Image', select the correct document language, and click 'OK'.
Click the 'Recognize Text' button to process the document. Once completed, attempt to edit the text using the 'Edit PDF' tool.
Extract and Edit Text from Scanned PDFs with WPS Office
WPS Office offers a highly accurate, built-in OCR feature for PDF documents. It easily extracts text from scanned images and converts them directly into editable documents, bypassing the limitations of basic PDF readers.
- 1. Open the scanned PDF: Launch WPS Office and open your scanned PDF document.
- 2. Select the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Configure extraction settings: Select the specific pages you want to process and choose the correct document language to ensure high accuracy.
- 4. Extract and edit: Choose whether to extract the text to a plain text box or convert it directly into an editable Word document for further formatting.

Frequently Asked Questions
Why can I copy text from my PDF but not edit it?
If you can highlight and copy text but cannot edit it, your PDF has likely been saved as a 'Searchable Image'. The OCR engine recognized the text layer to allow searching and copying, but the visual document remains a flat image file rather than editable text.
Does scan quality affect OCR accuracy?
Yes, poor scan quality is the most common cause of OCR failure. Documents scanned at low resolutions, with skewed angles, or with heavy background noise prevent the OCR software from accurately recognizing and converting the characters into editable text.
Is editable text OCR available in Adobe Acrobat Standard?
Acrobat Standard provides basic OCR to create searchable documents, but fully editable text output capabilities vary. Some advanced text editing and formatting features require upgrading to Adobe Acrobat Pro.
Can OCR process a page that already has text on it?
Typically, if a PDF page already contains a mix of searchable text and embedded images, the OCR engine may skip processing that specific page entirely to avoid corrupting or duplicating the existing text layer.


