

How to Fix Acrobat Find Cannot Locate OCR Text in Large PDFs

Question details
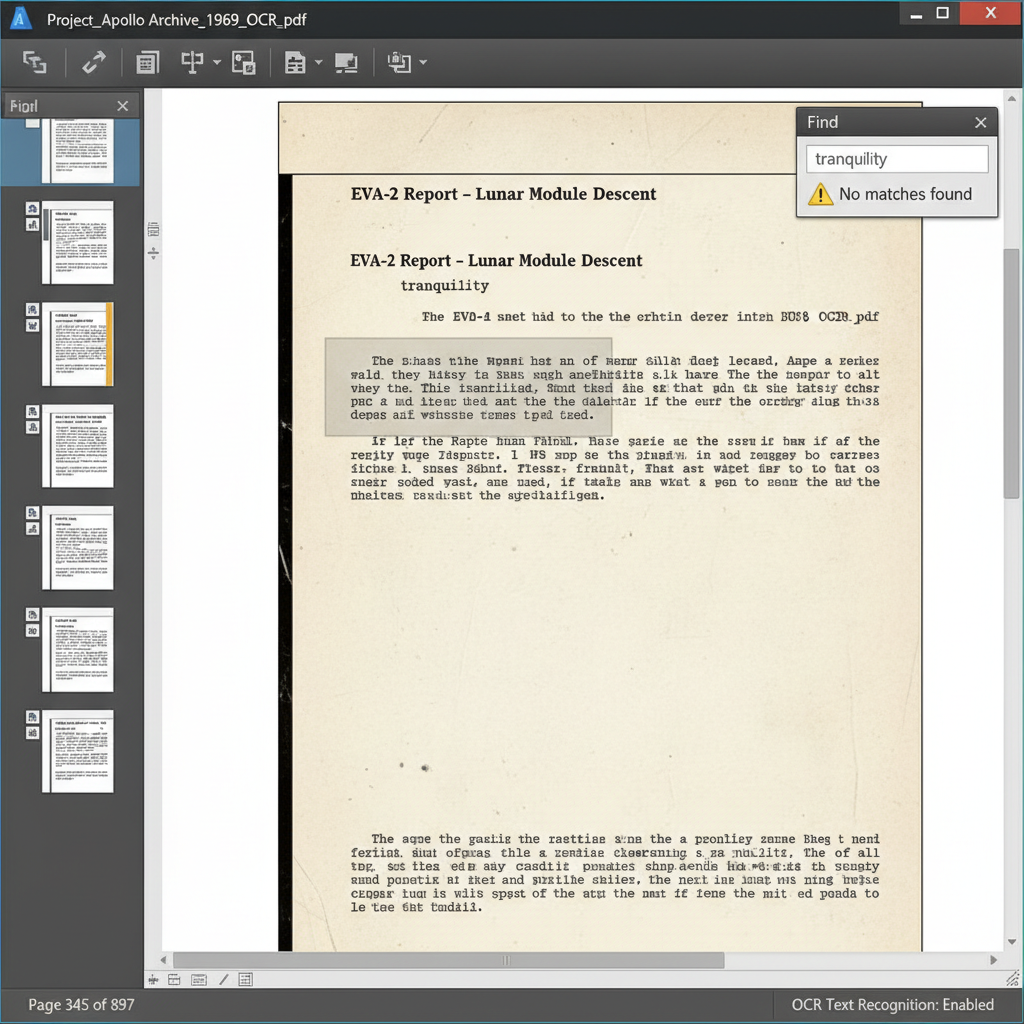
Acrobat's Find feature cannot locate specific text in large OCR-processed PDFs, despite the text being visually present on the page.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Searching for specific words or phrases within a large scanned or OCR-processed PDF document using the Find tool.
- Observed behavior
- The search tool returns no matches for text on certain pages because of potential OCR recognition errors, low scan quality, unusual fonts, or Acrobat search indexing limits.
Verify that your PDF document is not restricted from copying or searching by checking the document properties security tab, and ensure the file is not corrupted.
Verify OCR Recognition and Rerun OCR
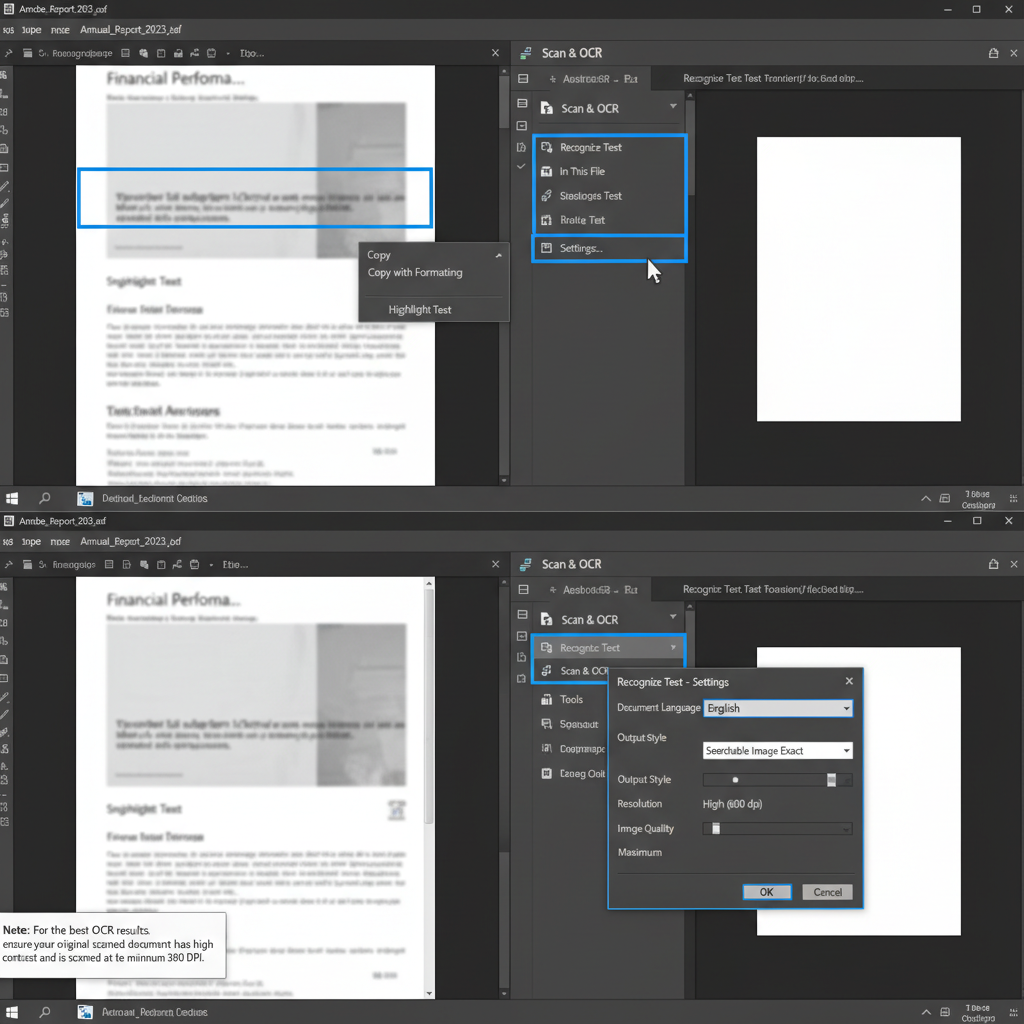
Check if the OCR text was correctly recognized by copying it to a text editor. If flawed, re-apply OCR with optimized settings.
Often, the text you see is just an image, and the hidden text layer generated by OCR contains garbled characters due to low scan quality or unusual fonts. Verifying the hidden text helps confirm if OCR is the root cause.
Highlight the visually appearing text on the affected PDF page that Acrobat failed to find, and press Ctrl+C (Windows) or Cmd+C (Mac) to copy it.
Open a plain text editor like Notepad or WordPad and paste the copied text. Compare the pasted text to the visual words on the PDF.
If the pasted text is incorrect or missing, the initial OCR failed. Go to the 'Scan & OCR' tool from Acrobat's right pane.
Select 'Recognize Text', choose 'In This File', click 'Settings' to select the correct document language and a higher resolution/quality, then click 'Recognize Text'.
Purge Cache and Rebuild PDF Search Index
If the OCR text is correct but the Find tool still fails, the document index might be corrupted or you may be hitting Acrobat search limitations in large files.
Use WPS Office for Highly Accurate PDF OCR and Text Search
WPS Office includes a powerful built-in PDF editor with advanced OCR (Optical Character Recognition) technology. It accurately extracts and indexes text from scanned documents, ensuring you can easily search, copy, and edit large PDFs without encountering missing text errors.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned or large PDF document.
- 2. Access OCR features: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Extract or convert text: Select 'Extract Text' or 'Convert to Word', ensuring you choose the correct document language for the highest recognition accuracy.
- 4. Search the document: Once processed, press Ctrl+F to open the search bar and instantly find your recognized text without indexing errors.

Frequently Asked Questions
Why does PDF search fail when I can clearly see the text on the page?
The text you visually see might just be an image. Unless Optical Character Recognition (OCR) is applied accurately to create a hidden, readable text layer, the PDF viewer cannot recognize the image pixels as searchable text characters.
How can I improve OCR accuracy on my scanned PDFs?
To improve OCR accuracy, ensure your source document is scanned at a high resolution (at least 300 DPI). Avoid scanning pages at a slant, maintain good black-and-white contrast, and always verify that the correct language is selected in your OCR settings.
Can I search across multiple large PDFs at the same time?
Yes, advanced PDF editors feature an Advanced Search function (usually accessed by pressing Shift+Ctrl+F) that allows you to search for text strings across all PDF files located within a specific folder or drive.
Does WPS Office support OCR for scanned PDFs?
Yes, WPS Office includes an integrated OCR tool that can recognize text in scanned PDFs, allowing you to extract searchable text or convert the documents directly into editable formats like Word or Excel.


