

Fix Acrobat Saving OCR PDF as Empty Text File

Question details
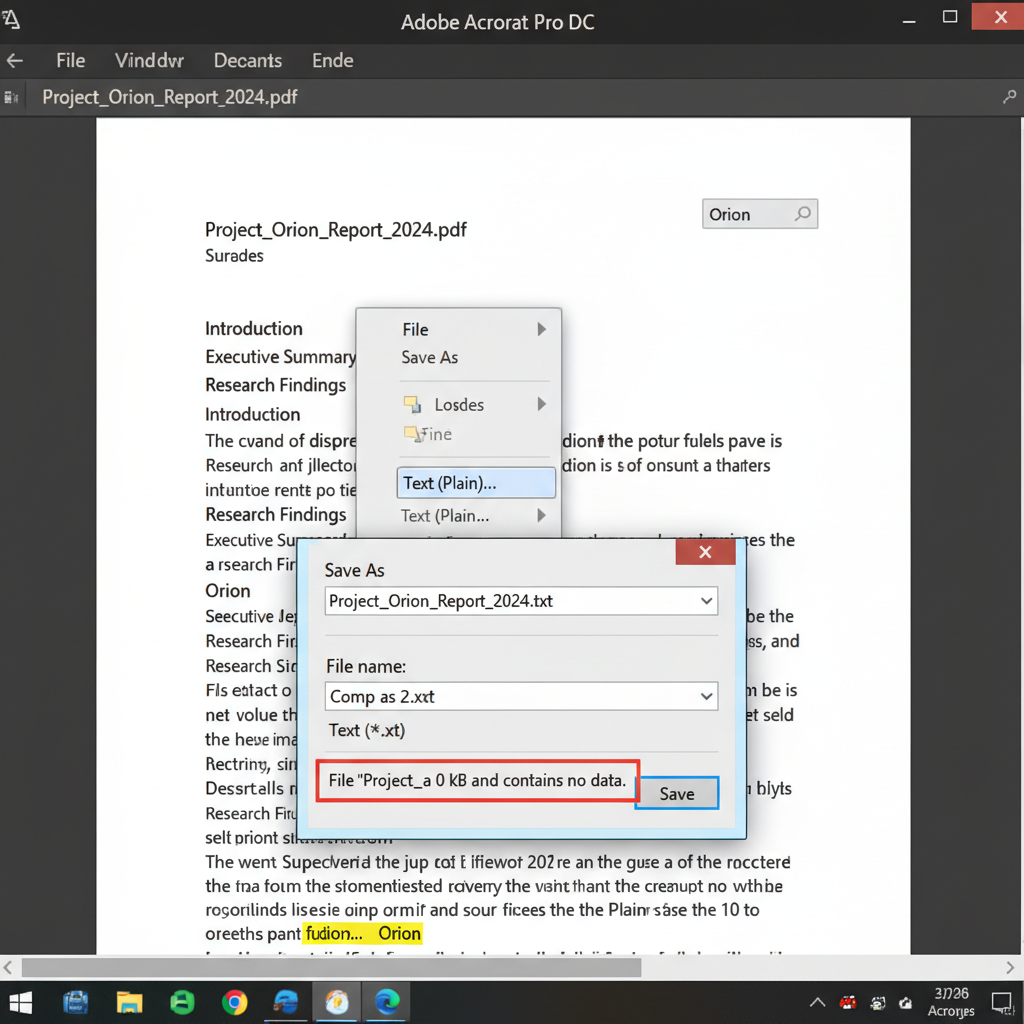
The user needs to successfully extract and save text from an OCR-processed PDF, but the output file contains no data.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Exporting a searchable, OCR-processed PDF document into a plain text format.
- Observed behavior
- The Find feature works correctly within the PDF, but using the 'Save as Text' option creates an empty 0 KB text file.
Ensure your PDF software is updated to the latest version, as this can resolve known export bugs. Additionally, verify that the PDF document does not have security restrictions preventing text extraction.
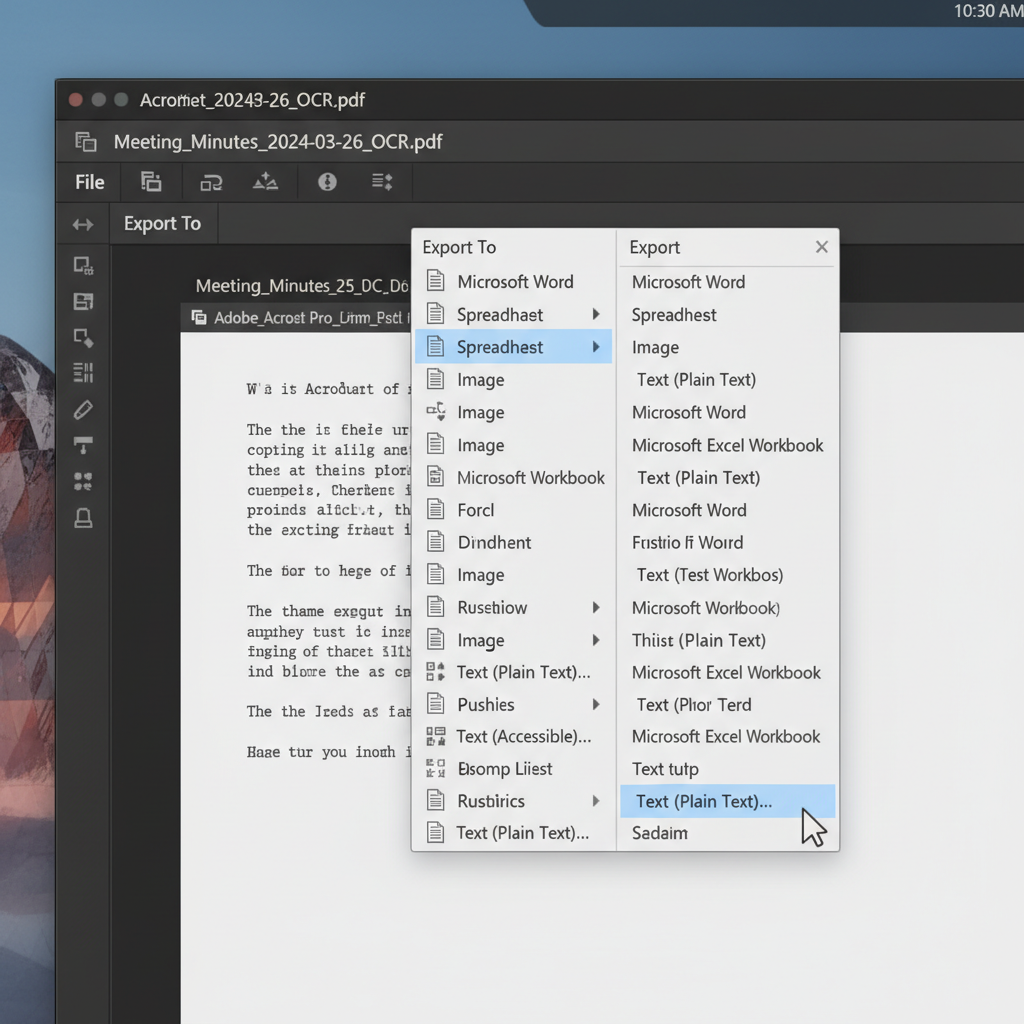
Use the 'Export To' Feature and Update Software
Bypass the 'Save As' bug by using the dedicated Export tool and ensure Acrobat has the latest patches installed.
Sometimes the standard 'Save As' dialog encounters parsing errors with specific OCR structures. Using the alternative 'Export To' path can bypass these limitations and correctly generate the text file.
Open Adobe Acrobat and navigate to Help > Check for Updates. Install any available updates and restart the application.
Launch your updated Acrobat application and open the searchable PDF that is causing the issue.
Instead of selecting 'Save As', go to the top menu and click File > Export To > Text (Plain Text).
Select your destination folder, save the file, and open the new text document to confirm the text has been successfully extracted.
Re-run OCR on the PDF Document
Rebuild the hidden text layer to fix unusual encoding or corrupted OCR structures that prevent extraction.
Use WPS Office to Extract Text from OCR PDFs
Avoid empty text file bugs by using WPS Office's built-in PDF tools. It accurately extracts text from OCR-processed PDFs without encoding errors, ensuring your data is fully preserved.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your OCR-processed PDF document.
- 2. Select PDF to Word/Text: Navigate to the 'Tools' tab and select the 'PDF to Word' or text extraction feature.
- 3. Adjust OCR settings: If prompted, ensure the OCR language is set correctly to match the document's content.
- 4. Convert and save: Click 'Start' to convert the document. The resulting file will contain the fully extracted text.

Frequently Asked Questions
Why does my searchable PDF export as a 0 KB text file?
This usually happens due to unusual font encoding, corrupted hidden OCR text layers, or a specific software bug in the version of the PDF reader you are using. The reader can search the embedded text but fails to parse it for an external file format.
How can I check if my PDF restricts text extraction?
Open the PDF, go to File > Properties, and click on the Security tab. Check the document restrictions summary to see if 'Content Copying' or 'Page Extraction' is set to 'Not Allowed'.
Can I re-apply OCR to fix the hidden text layer?
Yes. You can use the 'Scan & OCR' or 'Enhance Scans' tool in your PDF editor to re-run text recognition. This will often overwrite the corrupted layer and rebuild the text structure properly for export.


