

Fix Adobe Acrobat Find and Replace Not Working on Mac

Question details
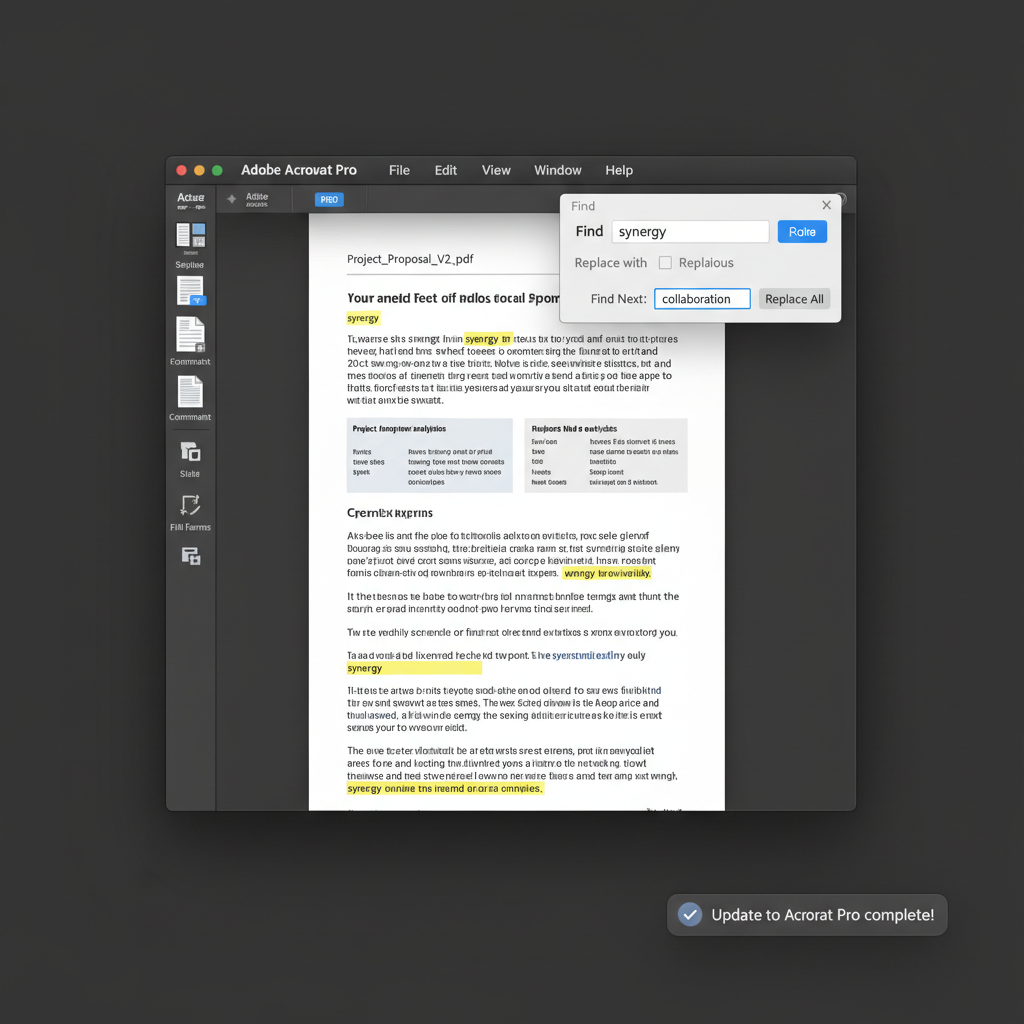
The user needs to fix the Find and Replace feature in Adobe Acrobat Pro, which fails to locate specific words or returns inaccurate results after upgrading from Acrobat Reader on Mac.
- Product
- Adobe Acrobat Pro
- Device & OS
- Mac
- Scenario
- Attempting to locate and replace specific text strings within a PDF document using the Find and Replace feature.
- Observed behavior
- The Find and Replace tool returns inaccurate search results, completely fails to locate expected words, or seems missing due to version confusion.
Ensure your PDF document is not a scanned image or a flattened file, as the Find and Replace feature strictly requires a recognizable, searchable text layer to function.
Run Optical Character Recognition (OCR)
If your PDF contains scanned pages or images of text, you must use the OCR tool to convert them into a searchable text layer before using Find and Replace.
Acrobat cannot search for or replace text that is embedded within an image. Running the built-in OCR process analyzes the document and creates a hidden layer of readable text that the Find and Replace tool can interact with.
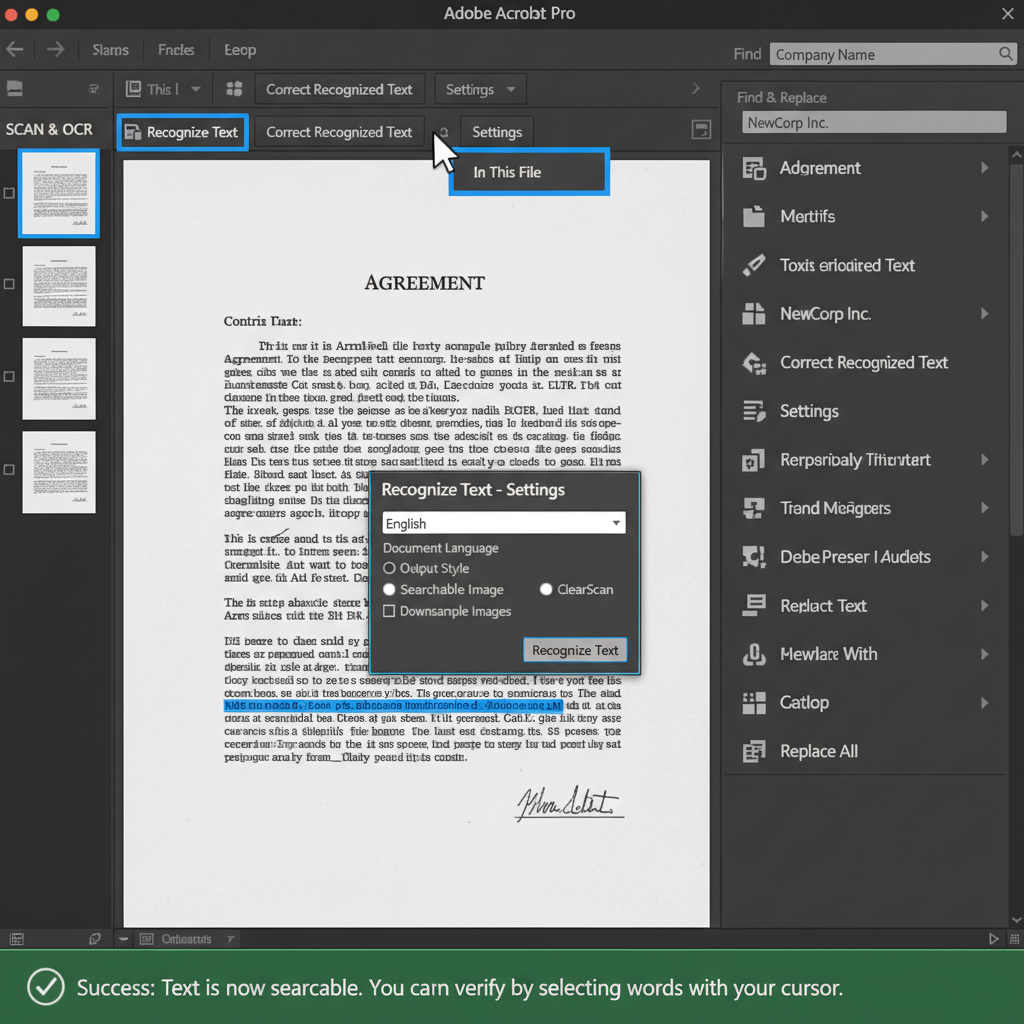
Launch Adobe Acrobat Pro, open your PDF document, and navigate to the 'Tools' pane on the right side. Select 'Scan & OCR'.
Click on 'Recognize Text' in the top toolbar and select 'In This File' from the dropdown menu.
Ensure the correct document language is selected in the Settings, then click the 'Recognize Text' button to process the document.
Once the OCR process is complete, press Cmd+F to open the search bar, expand it to Find and Replace, and attempt your text modification again.
Access the Advanced Search Command Correctly
Verify you are using Acrobat Pro, as the free Acrobat Reader version does not include a Find and Replace command.
Install the Latest Acrobat Update
Software bugs in older versions of Acrobat on Mac can cause the search index to fail, leading to inaccurate results.
Easily Find and Replace PDF Text with WPS Office
If you are struggling with Adobe Acrobat search indexing issues or version limitations, try WPS Office. It includes a powerful, built-in PDF editor with an intuitive Find and Replace tool that accurately locates and modifies text in your documents natively.
- 1. Open your PDF file: Launch WPS Office and open the PDF document you need to edit.
- 2. Access the Find and Replace tool: Navigate to the 'Home' tab and click on the 'Find and Replace' icon, or simply press Cmd+F (Mac) / Ctrl+F (Windows).
- 3. Enter your search criteria: Type the text you want to locate in the 'Find what' field, and enter the new text in the 'Replace with' field.
- 4. Execute the replacement: Click 'Replace' to change the highlighted instance, or 'Replace All' to automatically update every occurrence throughout the PDF document.

Frequently Asked Questions
Why doesn't Adobe Acrobat Reader have a Find and Replace feature?
Adobe Acrobat Reader is a free viewer designed strictly for reading documents, filling forms, and adding basic annotations. Advanced document editing features, including modifying existing text via Find and Replace, are reserved for the paid Adobe Acrobat Pro version.
How do I know if my PDF document has searchable text?
Try selecting the text with your cursor. If you can highlight individual letters and words smoothly, the document contains a searchable text layer. If clicking highlights the entire page as a single block or image, the file lacks a text layer and requires OCR processing.
What does running OCR do to my PDF file?
OCR (Optical Character Recognition) scans an image-based PDF, analyzes the shapes of the printed characters, and converts them into digital, readable text. This process embeds an invisible text layer over the image, allowing search tools to accurately read, locate, and replace the content.


