

Fix Scanned PDF Exporting to Word as Mixed Text and Images

Question details
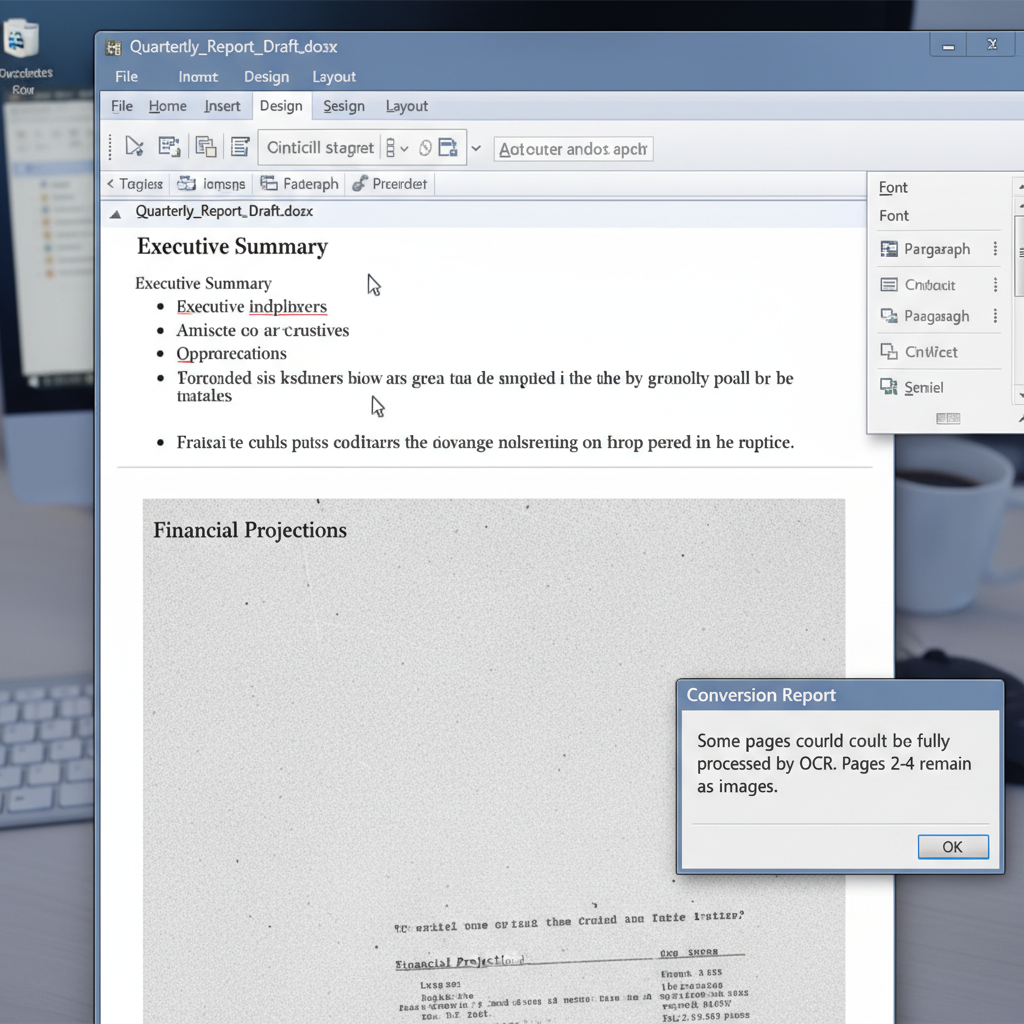
Users experience inconsistent formatting when converting scanned PDFs into Word documents, resulting in a file containing both editable text and uneditable images.
- Product
- PDF Editor / PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Converting a scanned PDF file into an editable Microsoft Word document for text modification.
- Observed behavior
- Some pages in the resulting Word document successfully become editable text, while other pages remain stuck as full-page static images due to OCR processing failures.
Ensure your original scanned PDF document is legible, well-lit, and correctly oriented, as poor image quality or tilted pages can severely impact the accuracy of OCR (Optical Character Recognition).
Run Full OCR Processing Before Exporting to Word
Manually process the entire PDF document through an OCR tool to ensure all pages are recognized as text prior to the final conversion.
When PDF to Word converters encounter a scanned document, they rely on Optical Character Recognition (OCR) to extract text. If the software processes the document automatically during conversion, it might skip pages that are hard to read. Running OCR manually gives you control over the text extraction settings and allows you to verify the results before exporting.
Launch your PDF editor, open the problematic scanned PDF, and navigate to the 'Tools' or 'Home' tab to select the 'OCR' function.
In the OCR dialog box, set the page range to 'All Pages' and carefully select the exact language used in the document to ensure the engine uses the correct character dictionary.
Click 'Extract Text' or 'Start OCR' and wait for the software to process every page of the document.
Once the OCR process finishes and you can highlight text on previously uneditable pages, click the 'PDF to Word' option to export the fully editable file.
Enhance Scan Quality and Rescan Problematic Pages
Address pages that failed to convert by improving their clarity, resolution, and alignment to help the OCR engine read them.
Convert Scanned PDFs to Word Flawlessly with WPS Office
WPS Office features an advanced, highly accurate OCR engine built directly into its PDF editor. It easily recognizes text in scanned images and complex layouts, ensuring your exports to Word are fully editable without mixed image pages.
- 1. Open the PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access PDF to Word: Navigate to the 'Tools' tab and click on the 'PDF to Word' button.
- 3. Enable OCR: Check the box or prompt to enable OCR (Optical Character Recognition) and select the document's primary language.
- 4. Start Conversion: Click 'Start' to convert your scanned PDF into a highly accurate, fully editable Word document.

Frequently Asked Questions
Why does my entire PDF to Word conversion output only images?
This happens when the source file is a flat image (like a JPEG saved as a PDF) or a scanned document, and OCR was not triggered during the conversion process. Enabling the OCR feature in your PDF editor is required to extract the text.
What is the best resolution for scanning documents to ensure good OCR results?
For optimal OCR accuracy, it is highly recommended to scan documents at 300 DPI (Dots Per Inch). Scanning below this resolution creates blurry text that software cannot read, while scanning above 600 DPI creates massive file sizes without significantly improving text recognition.
Does selecting the wrong document language affect PDF OCR extraction?
Yes. OCR engines use language-specific character dictionaries to identify text. If the wrong language is selected, the software may misinterpret characters, resulting in gibberish text or completely failing to convert the page, leaving it as an image.


