

Fix Windows 10 Not Indexing Text in OCR PDF Files

Question details
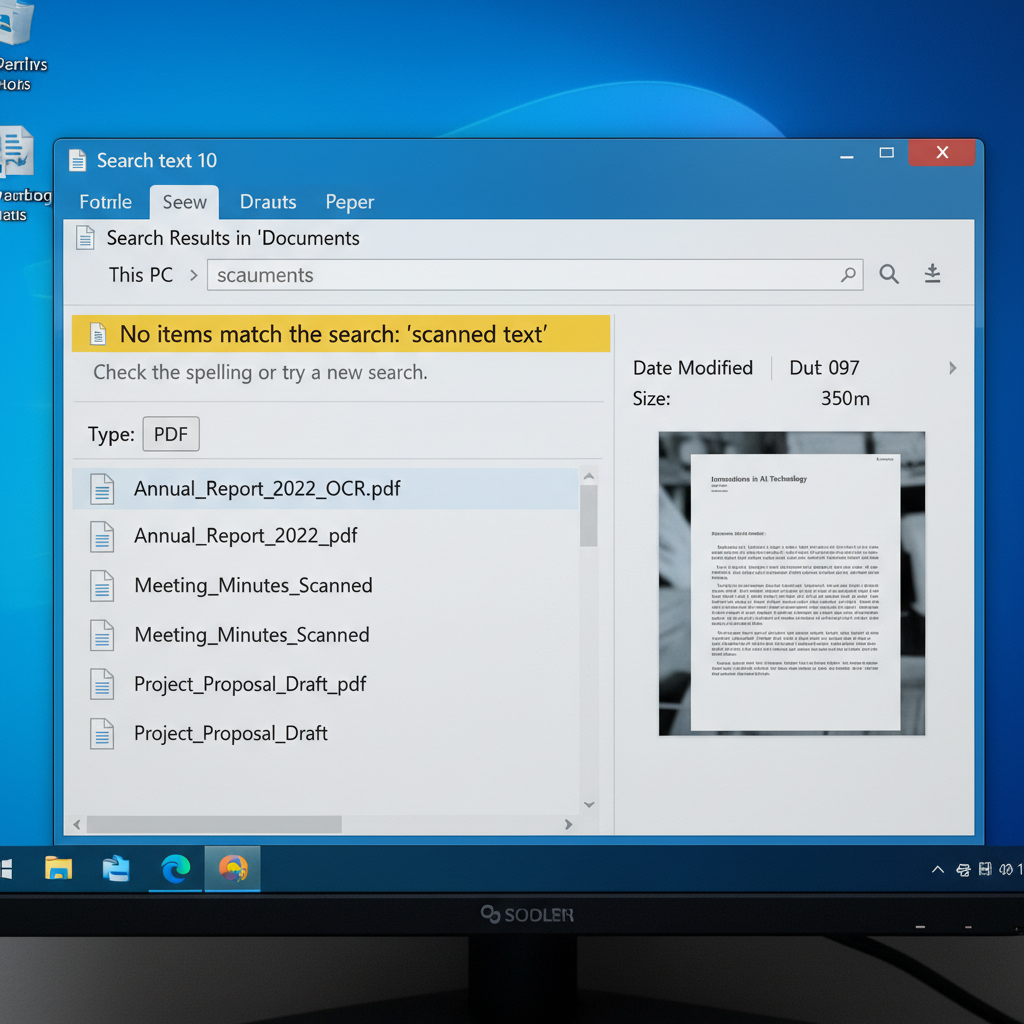
Windows 10 search does not return results for text contained within scanned PDF files, even after applying OCR.
- Product
- PDF / Windows Search
- Device & OS
- Windows 10
- Scenario
- Searching for specific text inside scanned PDF documents using the Windows 10 native file explorer search function.
- Observed behavior
- PDF contents do not appear in Windows 10 search results despite having OCR text, rebuilding the search index, and selecting the correct folder and PDF file type.
Open one of the affected PDF files in a PDF reader and try selecting the text with your cursor. If you cannot highlight the text, the file does not have a true text layer and must be OCR'd again before Windows can index it.
Configure PDF IFilter and Index Properties
Ensure Windows is using the correct IFilter to read the internal text of PDF files and that indexing options are set to read file contents.
Windows requires a specific component called a PDF IFilter to extract and index text from PDF documents. If this filter is missing or misconfigured, Windows will only index the file name and properties, ignoring the OCR text.
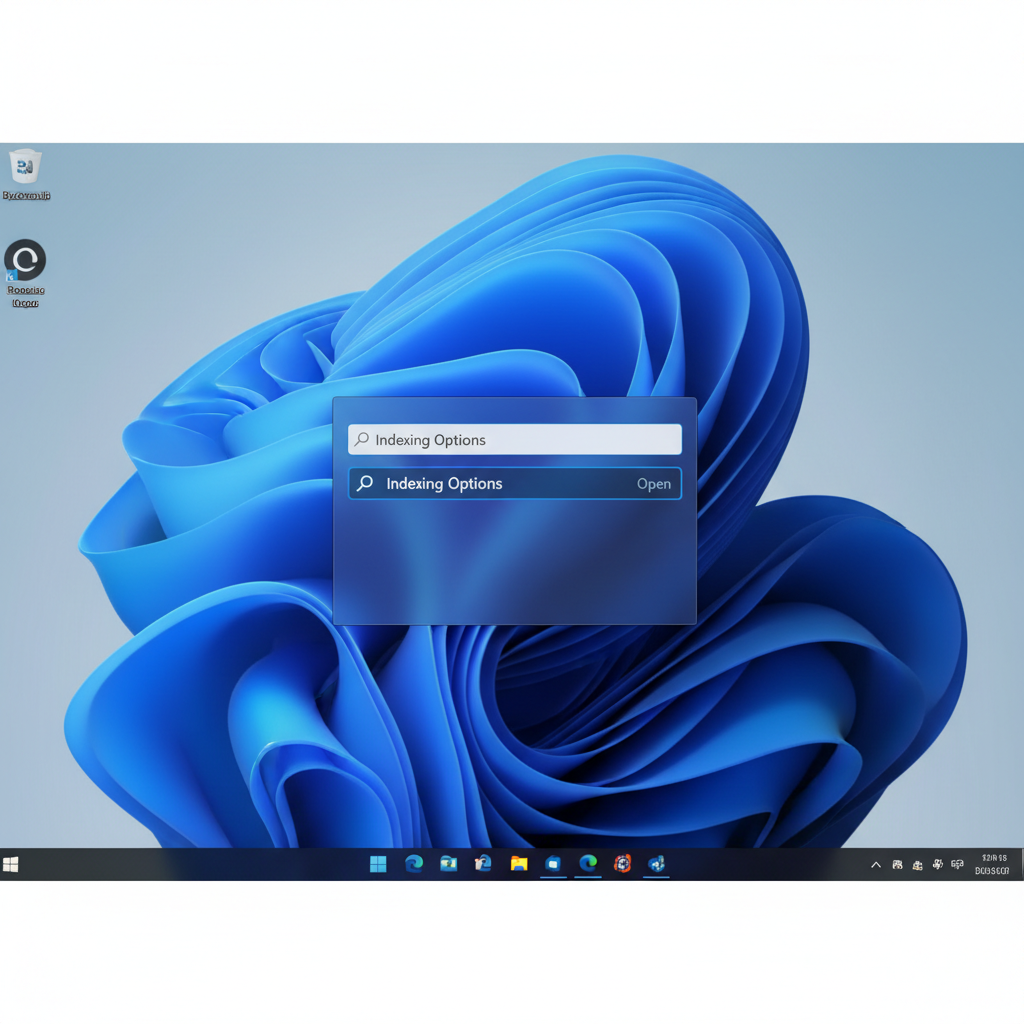
Click the Start menu, type 'Indexing Options' in the Windows search bar, and press Enter.
In the Indexing Options window, click the 'Advanced' button, then switch to the 'File Types' tab.
Scroll down the list and select the 'pdf' extension. Look at the bottom of the window; ensure the radio button for 'Index Properties and File Contents' is selected.
If the filter description says 'Registered IFilter is not found', you must download and install a PDF IFilter (such as Adobe PDF iFilter). After installing, repeat these steps to ensure it is active.
Switch back to the 'Index Settings' tab and click 'Rebuild' to force Windows to scan the PDF file contents with the new settings.
Re-run OCR to Generate Searchable Text
If the PDF was saved as an image-only file, re-running the OCR process will embed the hidden text layer required for indexing.
Remove PDF Security Restrictions
Encrypted or secured PDFs often block content extraction, preventing the Windows indexer from reading the text.
Use WPS Office to OCR and Manage PDF Files Effectively
WPS Office features a powerful built-in PDF toolkit that can accurately perform OCR on scanned documents, instantly converting them into fully searchable and editable text files that Windows can easily index.
- 1. Open PDF in WPS: Download and install WPS Office, then open your scanned or unindexed PDF file using WPS PDF.
- 2. Run the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select Searchable Output: In the OCR prompt, set your document language and select 'Searchable PDF' as the output method to ensure a text layer is embedded.
- 4. Save for Indexing: Save the newly processed document to your desired folder. Windows 10 will automatically index the embedded text layer.

Frequently Asked Questions
Why can I search for text inside the PDF reader but not from Windows Search?
Windows Search relies on a system component called an IFilter to extract text from files in the background without opening them. If the PDF IFilter is missing or set to index only file properties, Windows won't read the internal text, even if a dedicated PDF application can.
Can image-only PDFs be indexed by Windows 10 without OCR?
No. Windows Search cannot natively read text from flat images. You must perform Optical Character Recognition (OCR) on image-only PDFs to create a machine-readable text layer that the Windows indexer can process.
How long does it take for Windows 10 to index my newly OCR'd PDF files?
Indexing time depends on your computer's performance and the number of files on your hard drive. New files in actively indexed locations usually take a few minutes, but a complete index rebuild can take several hours.
Does Windows 10 have a built-in PDF IFilter out of the box?
Windows 10 sometimes uses Microsoft Edge or Windows Reader as the default PDF handler, which may not consistently provide a robust IFilter for deep text indexing. Installing a dedicated PDF IFilter from a trusted PDF software provider often resolves extraction issues.


