

How to Automate Tagged PDF Cleanup Using Acrobat SDK

Question details
The user wants to automate the cleanup and restructuring of tagged PDFs using Acrobat SDK plug-ins.
- Product
- Adobe Acrobat SDK
- Device & OS
- not provided
- Scenario
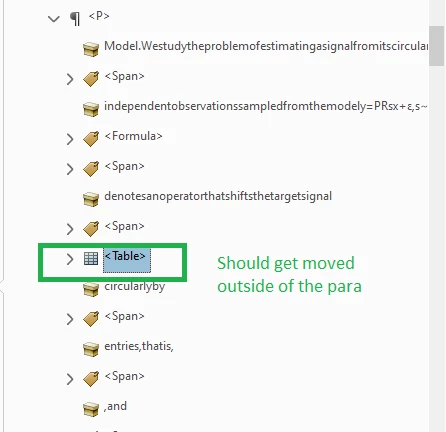
- Restructuring tagged PDFs, correcting missing spaces, or fixing improperly nested structural elements generated from PostScript files.
- Observed behavior
- Structural elements such as tables or figures are improperly nested (e.g., inside paragraph tags) and need to be moved and restructured programmatically.
Ensure you have the Adobe Acrobat SDK installed and configured in your development environment. Familiarize yourself with the basic concepts of the PDF structure tree and tagged PDF specifications before manipulating elements.
Modify the Structure Tree using PDSEdit and PDFEdit APIs
Utilize the specific methods within the Acrobat SDK to programmatically traverse and edit PDF tag structures.
The PDSEdit (PDF Document Structure Edit) and PDFEdit APIs are the primary toolsets provided by the Acrobat SDK to interact with and modify the logical structure of a PDF document.
By combining these APIs, you can locate improperly nested tags, extract them, and insert them at the correct level within the document structure tree to ensure accessibility and correct reading order.
Initialize the Acrobat SDK environment and load the target tagged PDF document.
Access the logical structure tree root using the PDDocGetStructTreeRoot() method.
Iterate through the structure tree using PDSElement methods to identify improperly nested elements (like tables or figures inside paragraphs).
Use PDSElementRemoveChild() to detach the incorrectly nested element from its current parent node.
Use PDSElementInsertChild() to attach the element to the correct parent node in the structure tree.
Save the document modifications and properly release the SDK resources to prevent memory leaks.
Edit and Restructure PDFs Easily with WPS Office
While developing custom Acrobat SDK plugins requires extensive C++ coding for PDF cleanup, WPS Office provides a lightweight, built-in PDF Editor that allows you to easily edit text, adjust layouts, and convert documents to editable formats without programming.
- 1. Open your PDF: Launch WPS Office and open your PDF file directly in the built-in PDF Editor.
- 2. Edit Content Directly: Navigate to the 'Edit' tab to easily modify text blocks, move images, and adjust layout elements.
- 3. Convert for Heavy Edits: Use the 'PDF to Word' feature if you need to perform heavy structural cleanup in a familiar word processing environment.

Frequently Asked Questions
What are PDSEdit and PDFEdit in the Acrobat SDK?
PDSEdit and PDFEdit are API sets within the Acrobat SDK used to manipulate the logical structure (tags) and the physical content of a PDF file, respectively.
Can I automate the removal of empty tags in a PDF?
Yes, by using the Acrobat SDK, you can write a script or plug-in to traverse the PDF structure tree, check for empty PDSElement nodes, and programmatically remove them using the appropriate methods.
Why are my PDF tags improperly nested when generating from PostScript?
PostScript does not natively support document structure tags. When converted to PDF, the distiller attempts to infer the structure, which often results in complex elements like tables or figures being mistakenly nested inside standard paragraph tags.
Is there a way to manually fix PDF tags without using the SDK?
Yes, you can manually fix tags using the accessibility and reading order tools found in premium PDF editors, though this process can be time-consuming for large or numerous documents.


