

How to Automatically Rename and Move a PDF Using OCR Text

Question details
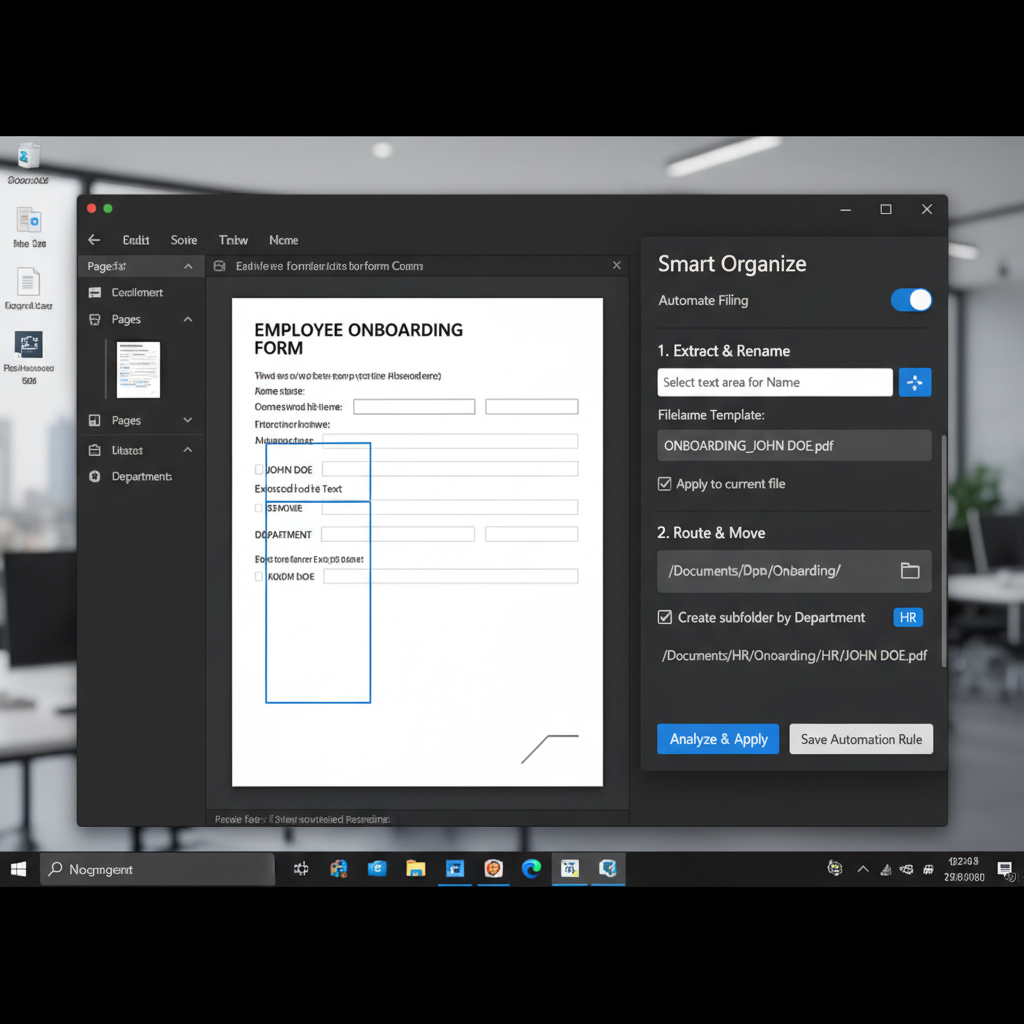
The user wants to extract specific text (like a name or department) from OCR-processed scanned documents and use that text to automatically rename the active PDF and move it to a designated folder.
- Product
- Device & OS
- not provided
- Scenario
- Organizing scanned documents that are initially saved with incremental filenames by automatically routing them based on their content.
- Observed behavior
- Standard PDF editors restrict file-system operations for security reasons, meaning native JavaScript cannot automatically rename and move files without elevated permissions.
Before attempting to automate file organization, ensure your scanned PDFs have already undergone Optical Character Recognition (OCR) so the text is machine-readable.
Use an External Document Management Tool or Script
Since standard PDF software restricts direct file renaming and moving for security, using an external automation tool is the safest and most effective method.
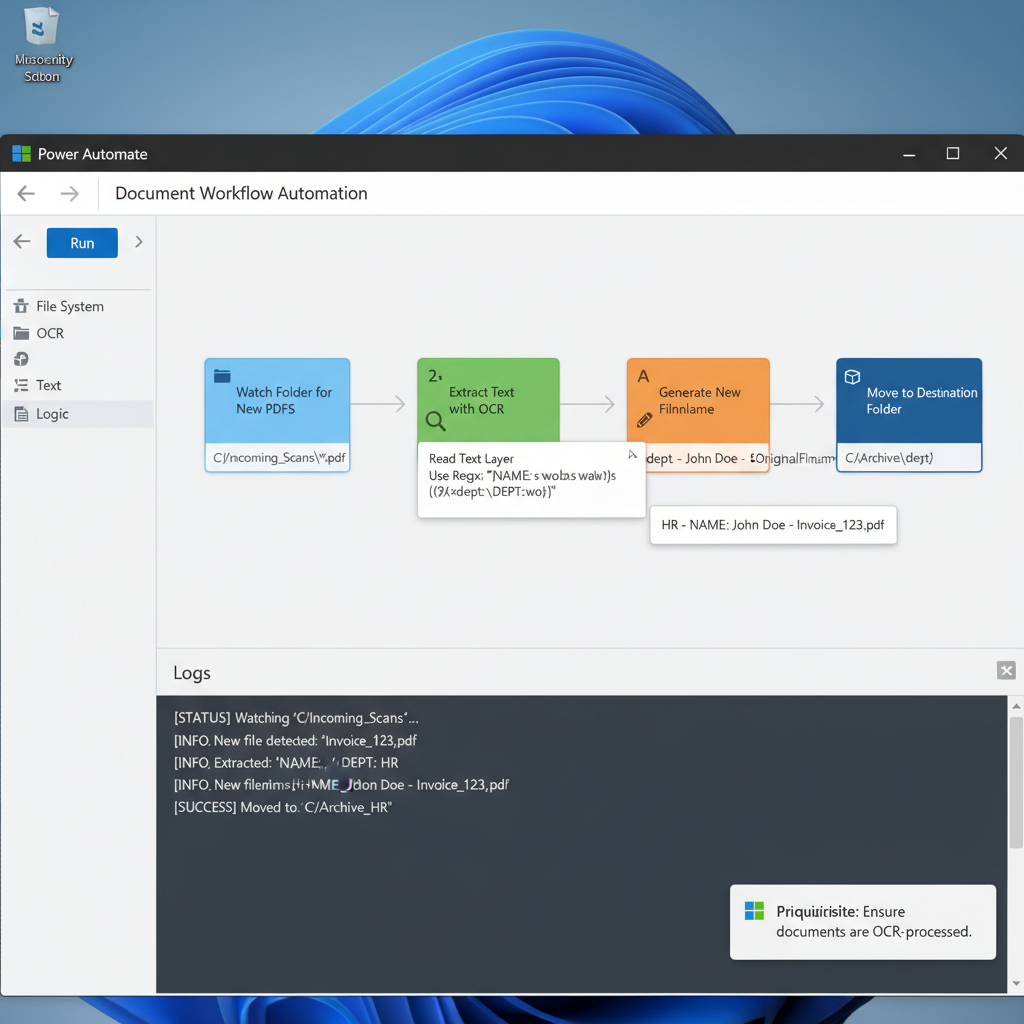
PDF applications typically run embedded scripts in a secure sandbox, preventing them from altering your file system. To bypass this limitation safely, you need a dedicated document-management system or a custom script (such as Python or Power Automate) that interacts directly with your operating system to handle file manipulation.
Choose a dedicated automation tool like Microsoft Power Automate, Hazel (for macOS), DropIt, or prepare a custom Python script.
Configure the automation tool to monitor the specific directory where your incrementally named, OCR-processed PDFs are initially saved.
Set up rules or regular expressions within the tool to read the document's OCR text layer and extract specific keywords, such as names or departments.
Command the tool to use the extracted text as variables for generating the new filename, and set the logic to route the file to the corresponding destination folder.
Set Up Folder-Level JavaScript with Elevated Permissions
Advanced users can bypass some security restrictions in standard PDF editors by installing trusted folder-level scripts.
Extract Text from Scanned PDFs Easily with WPS Office
While fully automated system-level file renaming requires external scripts, WPS Office provides an excellent, lightweight alternative to premium PDF editors for managing your documents. With advanced OCR capabilities, you can quickly extract text from scanned documents, convert them to editable formats, and seamlessly organize your files within a highly compatible suite.
- 1. Download and install WPS Office: Visit the official WPS website, download the free suite, and install it on your device.
- 2. Open your scanned document: Launch WPS PDF and open the scanned document you wish to process.
- 3. Use the OCR tool: Click on the OCR feature in the toolbar to extract the text, which you can then copy to manually rename your files or save as a new editable document.

Frequently Asked Questions
Why can't I automatically rename files directly within my PDF editor?
Most modern PDF applications enforce strict security sandboxing. This prevents potentially malicious documents from executing scripts that can modify, delete, or rename files on your computer's hard drive without your explicit permission.
Does the PDF need to have selectable text before automating?
Yes. Scanned documents are essentially flat images. You must apply Optical Character Recognition (OCR) to convert the images into searchable text. External automation tools rely entirely on this text layer to extract the names and keywords required for renaming.
Can I use Python to automate renaming and moving PDFs?
Absolutely. Python has several libraries, such as PyPDF2 or pdfplumber, that can read the text layer of an OCR-processed PDF. Combined with Python's built-in OS and shutil modules, you can easily script a powerful solution to rename and move files based on their content.


