

How to Automatically Rename PDFs Using Text Extracted From a Specific Document Area

Question details
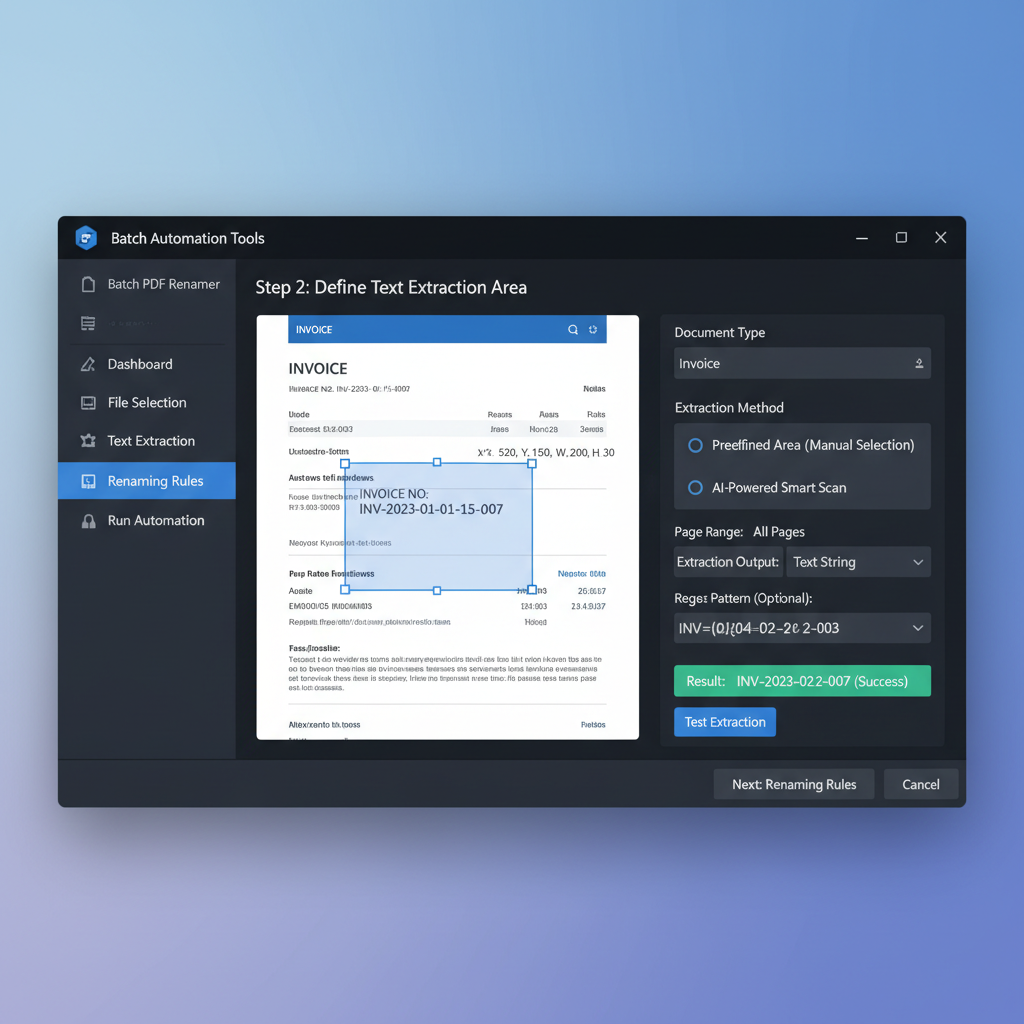
The user needs a method to automatically rename PDF files based on text (such as invoice numbers or dates) located in a consistent specific area on the pages.
- Product
- PDF Automation Tools
- Device & OS
- not provided
- Scenario
- Batch processing invoices or standardized documents where each file needs to be automatically named after a specific ID or string of text within the file.
- Observed behavior
- The goal is to automatically inspect text coordinates within a predetermined area and rename the file accordingly.
Ensure all your PDF documents follow a perfectly consistent layout (like standard invoices) and gather them in a single folder before running any automated extraction scripts.
Use Python and PDF Libraries for Coordinate-Based Extraction
Create a custom Python script to read text from specific coordinates and rename files automatically.
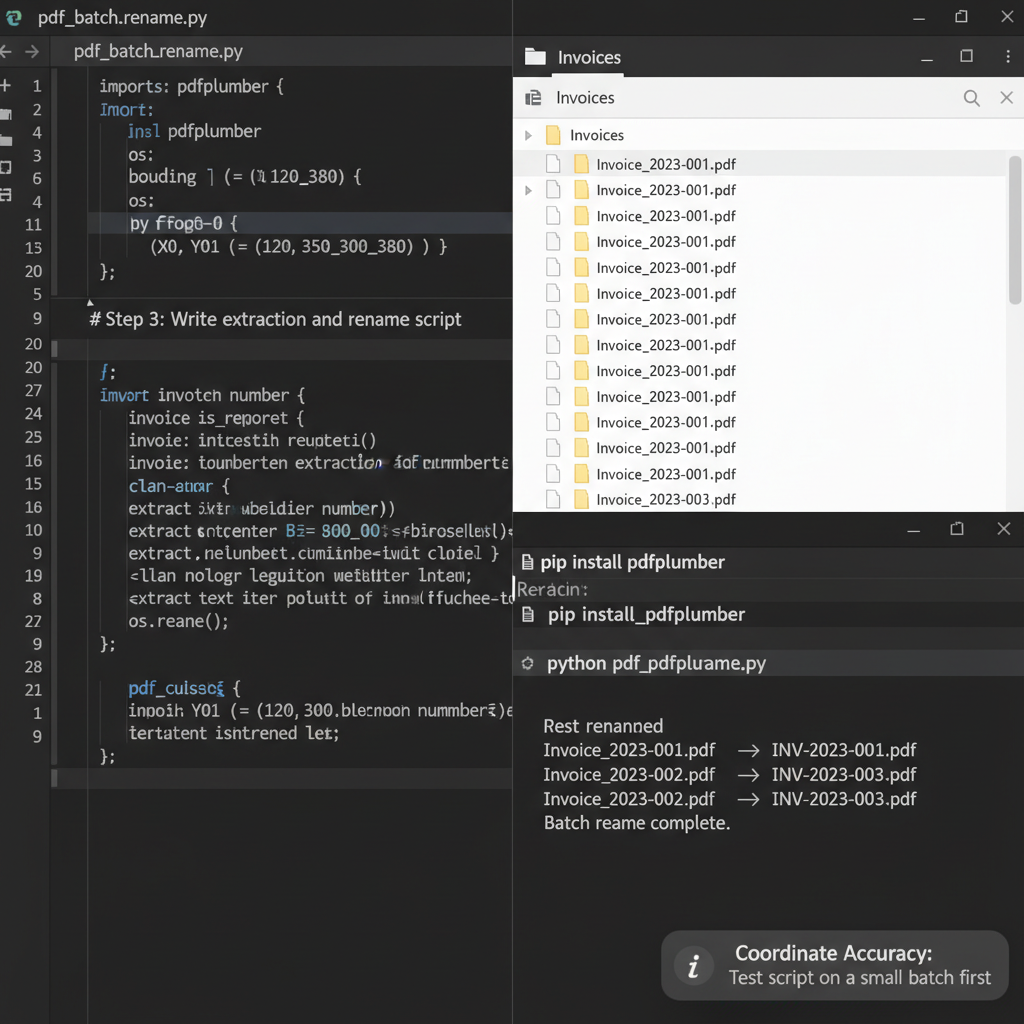
By utilizing Python libraries such as pdfplumber or PyMuPDF, you can programmatically define a bounding box (coordinates) on a PDF page. The script will extract whatever text falls inside those coordinates and use it to rename the file.
This method is highly effective for large batches but requires basic programming knowledge and documents with identical formatting.
Open your terminal or command prompt and install a PDF parsing library by running a command like 'pip install pdfplumber'.
Determine the exact X and Y coordinates (X0, Y0, X1, Y1) where your target text (e.g., invoice number) appears on the standard PDF template.
Write a Python loop that opens each PDF in your target directory, extracts the text using the defined bounding box, and cleans the text string to remove invalid filename characters.
Use the built-in 'os.rename()' Python function within your loop to apply the extracted text string as the new file name for each document.
Utilize Dedicated Batch Renaming Software (Zonal OCR)
Use specialized third-party tools that offer a visual interface to select a text area and batch rename documents without coding.
Manage, Extract Text, and Edit PDFs with WPS Office
While automated coordinate-based batch renaming requires advanced custom scripts, WPS Office provides powerful native PDF tools to manually extract text, perform OCR on scanned documents, and easily manage your PDF files without coding.
- 1. Open the PDF document: Launch WPS Office and open the PDF file you need to extract text from.
- 2. Select the target text: Navigate to the 'Home' or 'Edit' tab, use the Select tool, and highlight the required text (e.g., the invoice number).
- 3. Copy the text: Right-click the highlighted text and select 'Copy', or use the Ctrl+C keyboard shortcut.
- 4. Rename the file: Go to Menu > Save As, paste the extracted text into the file name field using Ctrl+V, and click Save.

Frequently Asked Questions
Do I need to know programming to auto-rename PDFs by text?
Yes, extracting text based on exact page coordinates usually requires writing custom scripts in languages like JavaScript (via Adobe Acrobat) or Python. However, some specialized paid software offers visual drag-and-drop interfaces for this task.
Can OCR be used to extract text from scanned documents for renaming?
Yes. If your PDF is essentially an image (like a scanned invoice), standard text extraction won't work. You must first apply OCR (Optical Character Recognition) so the script can detect the text coordinates.
Why is the script extracting the wrong text or missing it entirely?
This usually happens if the documents have slight layout variations. If a logo is resized or a margin is shifted, the target text may fall outside your programmed X/Y coordinate bounding box. Ensure all pages have exact formatting.
Are there free tools to batch rename PDFs based on content?
Open-source Python libraries like pdfplumber or PyPDF2 can achieve this entirely for free, but they require you to have the technical skills to write and execute the code.


