

How to Automatically Split Scanned PDFs into Individual Invoices

Question details
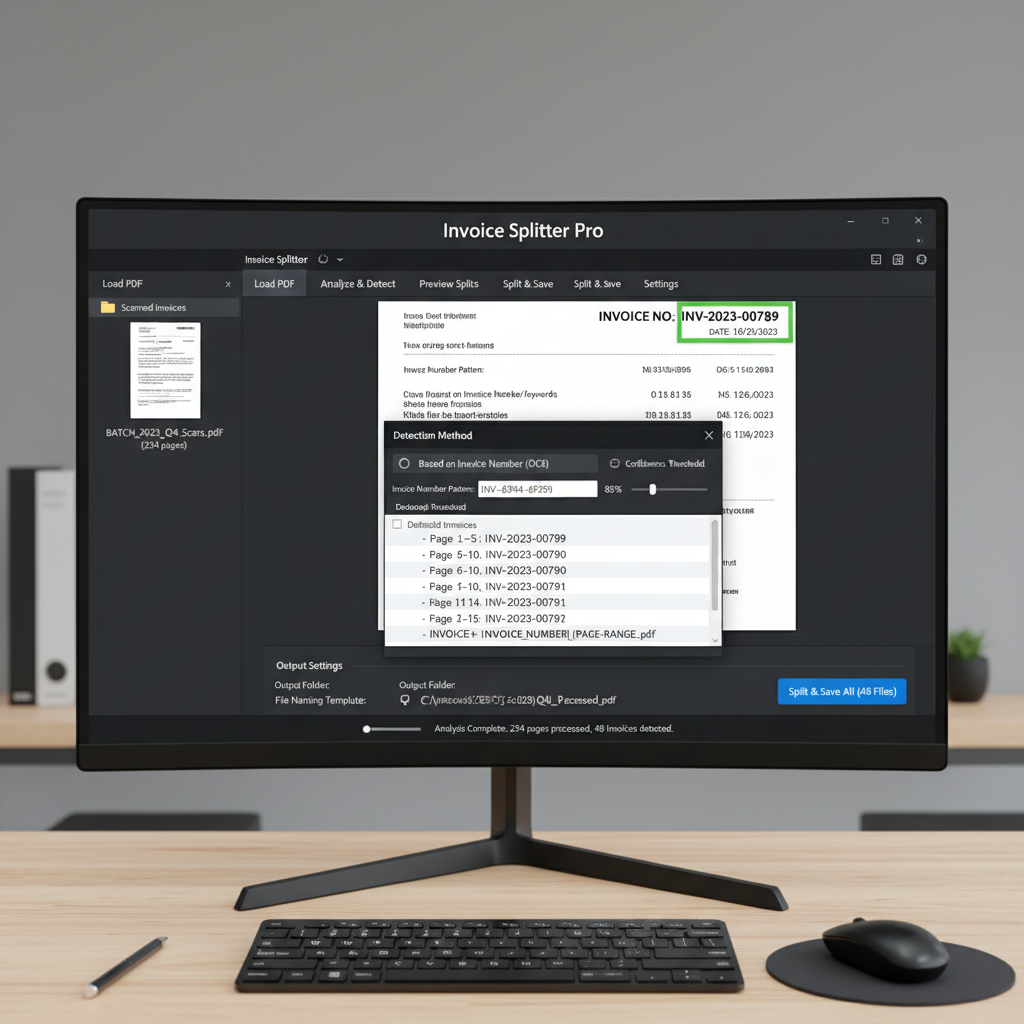
The user needs to divide a large scanned PDF containing multiple invoices into separate files based on invoice numbers or page markers automatically.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Managing large batches of scanned invoices that need to be separated for individual processing, renaming, or archiving.
- Observed behavior
- Currently, the invoices are bundled into a single large scanned document. The goal is to detect invoice boundaries using OCR and split them into appropriately named individual files.
Ensure your scanned PDF document is of high visual quality and clear enough for Optical Character Recognition (OCR) to accurately identify text strings like invoice numbers and headers.
Use OCR and Custom Scripting to Split Invoices
Run OCR to make the document searchable, then use a document processing workflow or JavaScript to automatically detect boundaries and split the file.
To automate the splitting process, you must first convert the flat scanned images into searchable text. Once the text is recognizable, automated scripts can look for specific keywords or invoice numbers to determine where one invoice ends and another begins.
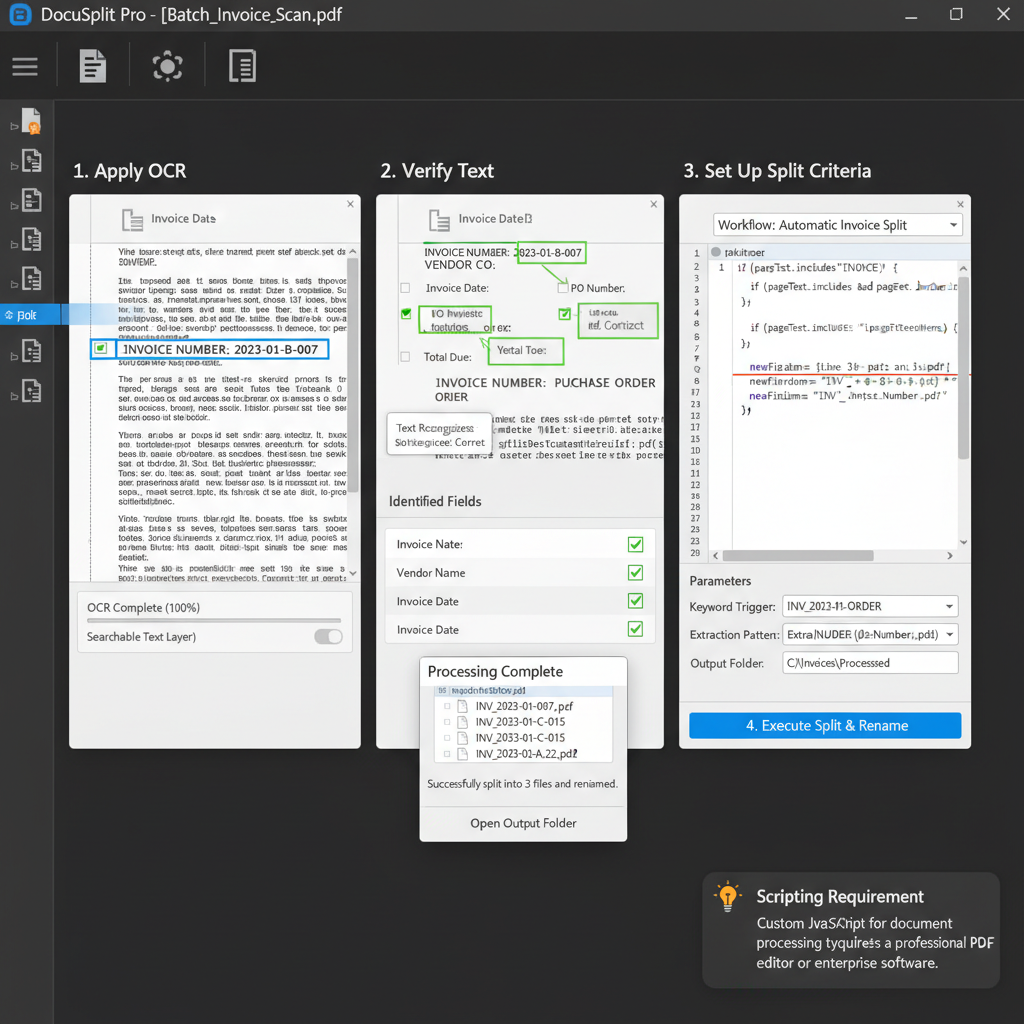
Open the scanned PDF in an advanced PDF editor and run the OCR (Optical Character Recognition) tool to convert the document's images into selectable and searchable text.
Review the document to confirm that crucial text identifiers like invoice numbers, purchase order numbers, and page indicators have been recognized correctly without spelling errors.
Use a custom JavaScript or a dedicated batch processing tool to define the splitting boundaries. For example, configure the script to split the document whenever the word 'Invoice' or a specific vendor layout appears at the top of a page.
Run the workflow or script to automatically divide the document into individual PDFs. The script can also extract the recognized invoice numbers to automatically name each newly created file.
Manually Split PDFs Using Page Ranges
If custom scripting is unavailable or OCR accuracy is too low due to poor scan quality, you can manually extract pages to create individual invoices.
Split and OCR PDFs Seamlessly with WPS Office
WPS Office provides powerful PDF editing features, including highly accurate OCR technology and robust page management tools to extract and split document pages easily.
- 1. Open the PDF in WPS: Launch WPS Office and open your scanned invoice PDF document.
- 2. Run OCR: Go to the 'Tools' tab and select 'OCR' to convert the scanned images into editable and searchable text.
- 3. Split the Document: Navigate to the 'Page' tab and select the 'Split PDF' tool from the ribbon.
- 4. Choose Split Settings: Set your split criteria, such as splitting by a fixed page count (if each invoice is the same length) or specifying custom page ranges.
- 5. Export and Save: Click 'Split' to generate the individual invoice files and save them to your preferred local folder.

Frequently Asked Questions
Why is the OCR not recognizing my invoice numbers accurately?
OCR accuracy heavily depends on the original scan quality. Ensure the document is scanned at a minimum of 300 DPI, has strong contrast, and is free of smudges, low lighting, or handwriting overlapping the typed text.
Can I automatically rename the split PDFs based on their content?
Yes, advanced PDF scripts or third-party batch processing tools can extract text variables, such as invoice numbers or dates, from the OCR data and use them to automatically generate the output file names.
Is there a way to split scanned PDFs automatically without writing custom scripts?
If you want to avoid writing scripts, some dedicated invoice processing and data capture software can handle this out-of-the-box. Alternatively, if every invoice is exactly the same number of pages, you can use the built-in 'Split PDF' feature in a standard PDF editor to divide the document evenly.
Will splitting a scanned PDF reduce the quality of the invoices?
No, extracting or splitting pages from a PDF generally retains the original quality and resolution of the scanned images on those pages.


