

How to Darken Scanned PDF Pages Without Losing OCR

Question details
The user needs to improve the readability of faint or lightly scanned PDF pages by darkening the text while preserving the existing OCR (Optical Character Recognition) text layer.
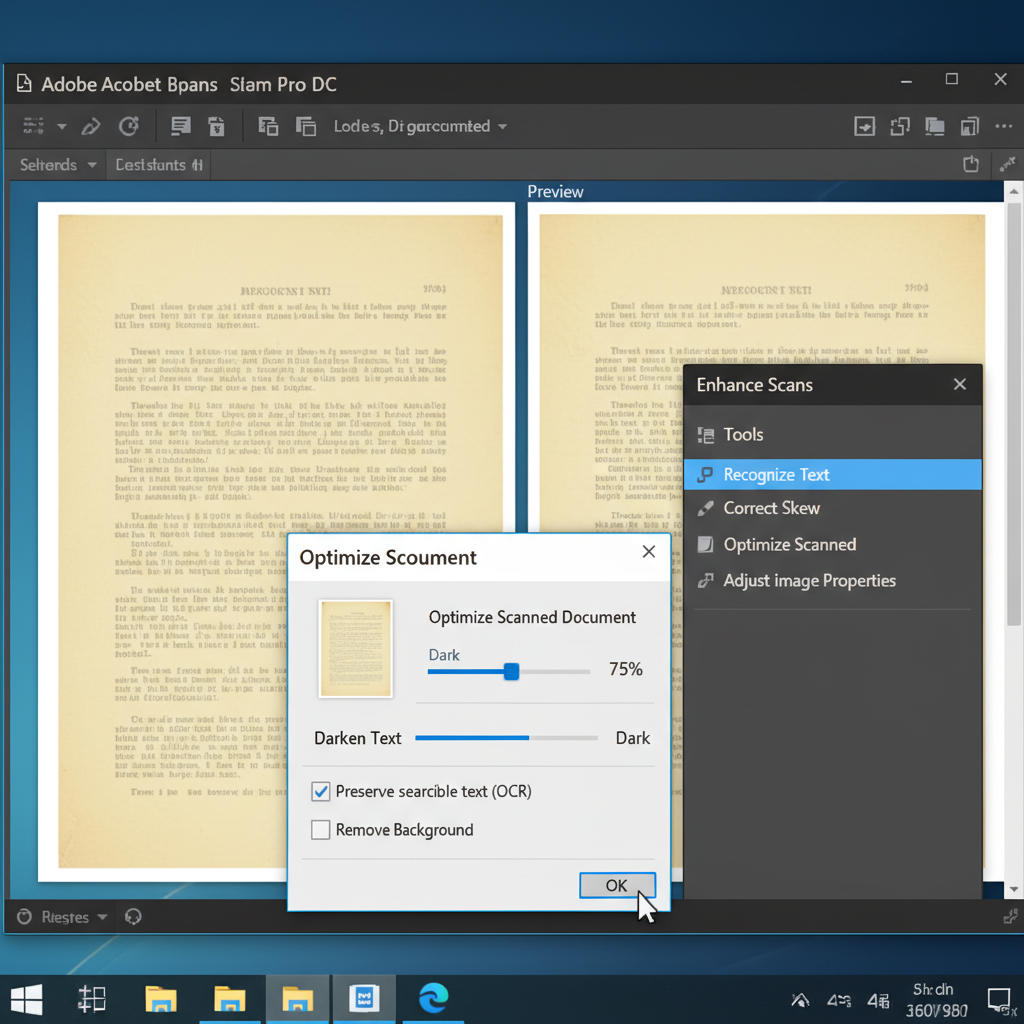
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to read or process lightly scanned documents where the text is too faint, requiring visual enhancement.
- Observed behavior
- The scanned PDF pages are too light for comfortable reading, and modifying the image properties directly risks destroying the hidden, searchable OCR text layer.
Always create a backup copy of your original scanned PDF document before proceeding, as image optimization and contrast adjustments may permanently alter or remove the existing OCR text layer.
Apply the Background Removal Filter in Optimize Scanned PDF
Use built-in optimization tools to increase the contrast between the text and the page background for grayscale or color scans.
Acrobat includes dedicated filters for scanned documents. The Background Removal filter increases the contrast between letters and the background, clarifying gray and color inputs while turning nearly white areas completely white.
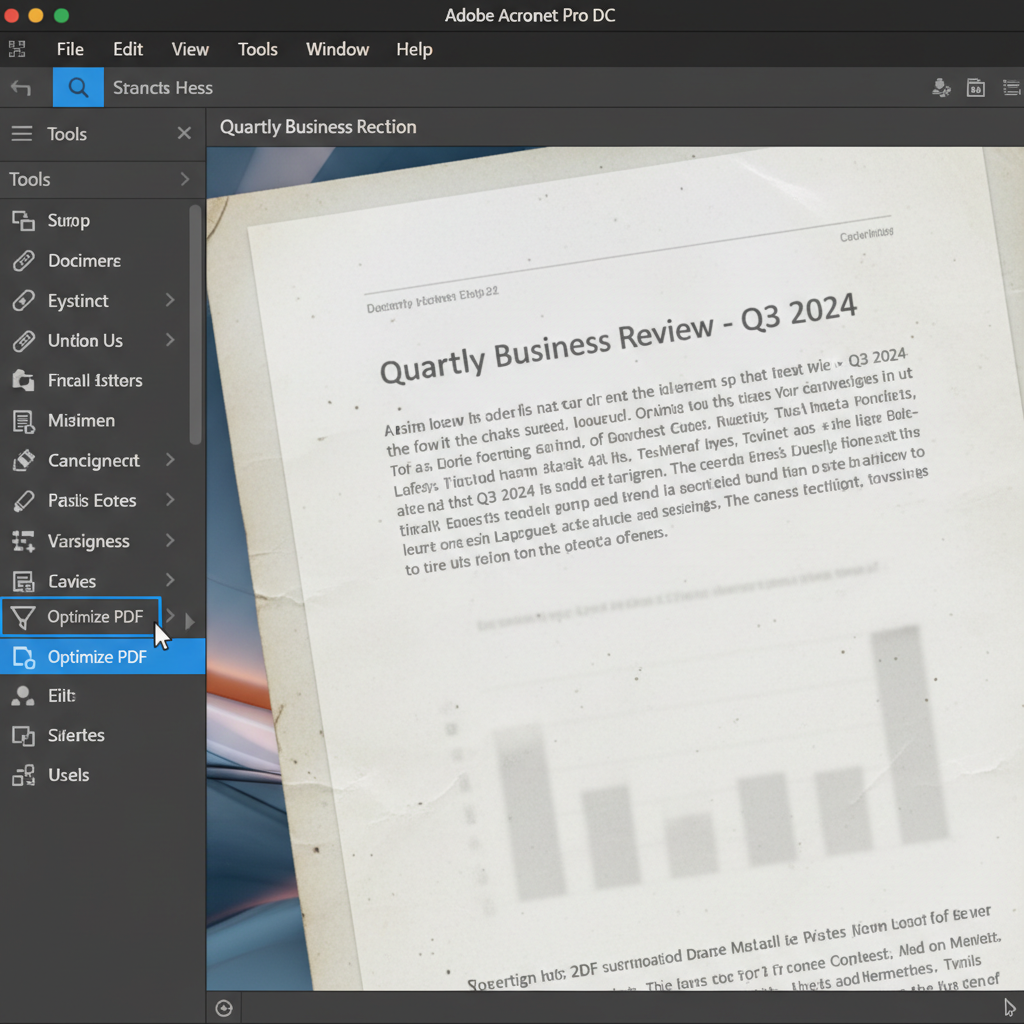
Open your PDF document in Adobe Acrobat. Navigate to the 'Tools' menu and select 'Optimize PDF' (or find it under the 'Document Processing' panel in older versions).
Click on 'Enhance' in the top toolbar and choose 'Scanned Document' from the dropdown menu.
Open the filter or edit settings and ensure the 'Background removal' filter is applied. Adjust the slider if available to darken the text against the background.
Save the optimized document as a new file. Use your cursor to highlight the text to ensure the OCR layer remains intact and searchable.
Adjust Settings During the Initial Scan
The most effective way to ensure dark, readable text without risking OCR data is to adjust the hardware scanning settings before generating the PDF.
Easily Manage Scanned PDFs and Extract Text with WPS Office
WPS PDF offers robust built-in OCR and comprehensive PDF editing tools, allowing you to easily handle scanned documents, extract text, and enhance document workflows in one lightweight application.
- 1. Open Scanned Document: Download and install WPS Office, then open your scanned PDF document in WPS PDF.
- 2. Run OCR Tool: Navigate to the 'Tools' tab and click on the 'OCR' button to recognize and extract text from the scanned images.
- 3. Convert to Editable Format: Choose to convert the scanned PDF into a Word document, giving you complete freedom to change font colors, bold text, and adjust contrast natively.
- 4. Export to PDF: Once your text is darkened and formatted exactly as needed, export the file back to PDF format with the text perfectly preserved.

Frequently Asked Questions
Will optimizing a scanned PDF always delete my OCR text?
Not always, but applying heavy image filters, flattening the document, or using aggressive optimization settings can sometimes overwrite or remove the hidden OCR text layer. It is highly recommended to keep a backup before applying optimizations.
Why does the background removal filter not work on my black-and-white scan?
The background removal filter relies on detecting varying shades of gray or color to differentiate the text from the background. Pure black-and-white (1-bit) scans lack this gradient data, making the filter ineffective.
Can I just darken the text directly in a PDF editor?
If the PDF is a scanned image, the text is actually part of a picture, not individual font characters. Because of this, you cannot simply select the text and change its font color; you must use image enhancement tools to adjust the overall contrast.
How do I know if my PDF already has an OCR layer?
Try highlighting a word in the document with your mouse cursor. If you can smoothly select individual words and copy them to your clipboard as editable text, the document has an active OCR layer.


