

How to Edit a Scanned Tamil Document using OCR

Question details
The user needs to extract and edit text from a scanned document written in Tamil, which is currently saved in an unclear format.
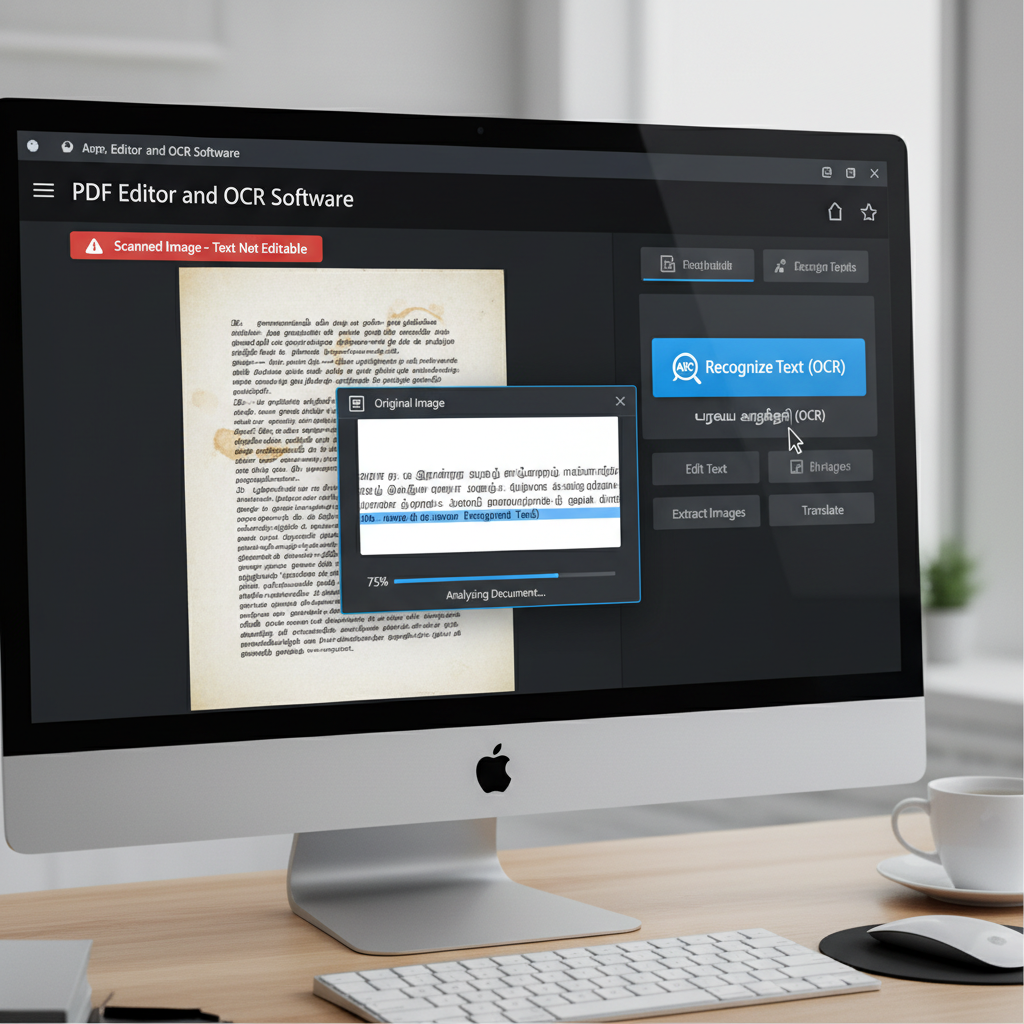
- Product
- PDF Editor and OCR Software
- Device & OS
- not provided
- Scenario
- Converting a scanned, non-editable image or PDF file into a format where the text can be modified.
- Observed behavior
- The document acts as a flat image, preventing direct text selection and modification without specialized text-recognition tools.
Verify the actual file format of your scanned document (such as PDF, JPEG, or TIFF) and ensure the scan is clear and well-lit to maximize text recognition accuracy.
Use Dedicated OCR Software to Extract Tamil Text
Utilize a PDF editor or OCR tool that specifically supports the Tamil language to convert the scan into editable text.
Optical Character Recognition (OCR) analyzes the shapes of letters in an image and translates them into machine-readable text. Because Tamil uses a distinct and complex script, it is crucial to select an OCR engine that explicitly supports Tamil to avoid garbled output.
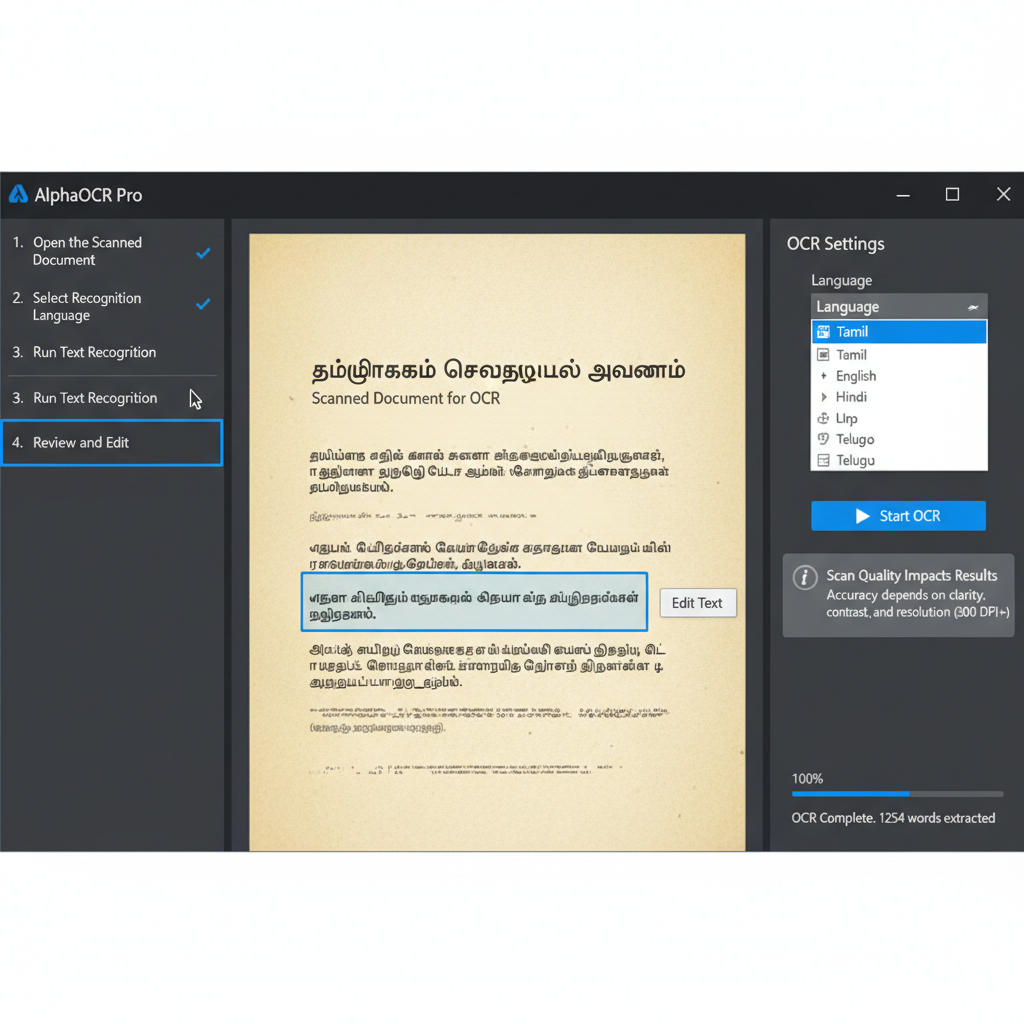
Launch your preferred PDF editor or OCR application (such as Adobe Acrobat or an online OCR tool) and open the scanned file.
Navigate to the OCR or Text Recognition settings menu and explicitly set the document language to 'Tamil'.
Click the 'Recognize Text' or 'Start OCR' button to begin processing the document.
Once the OCR process is complete, review the extracted text for any inaccuracies caused by low scan quality, and proceed to make your edits.
Convert Unknown File Formats to PDF Before OCR
If your document is saved in an obscure format, convert it to a standard PDF before attempting text extraction.
Extract Text from Scanned PDFs with WPS Office
WPS Office includes a powerful built-in OCR feature for PDF files. You can easily extract text from scanned documents, convert them to editable Word files, and seamlessly modify the content without losing formatting.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned document in the WPS PDF editor.
- 2. Access the OCR Tool: Go to the 'Tools' tab on the top ribbon and select the 'OCR' or 'Picture to Text' option.
- 3. Extract and Save: Follow the on-screen prompts to extract the text from your document and save it as an editable format.
Frequently Asked Questions
Why is the OCR output for my Tamil document showing random symbols?
This usually happens if the OCR language is set to English by default. Because Tamil characters are entirely different, the software attempts to match them to English letters. You must explicitly select 'Tamil' in the OCR software settings before running the text recognition.
Can I edit a scanned PDF directly without converting it to a Word document?
Yes, advanced PDF editors allow you to perform OCR and edit the text directly within the PDF file. The software creates an invisible editable text layer over the original scanned image, letting you modify words directly.
What should I do if my scanned document is too blurry for OCR to work properly?
If the document is blurry, try enhancing the image contrast and brightness using a photo editor before running it through OCR. If the original physical paper is still available, rescanning it at a higher resolution (at least 300 DPI) is highly recommended for accurate results.


