

How to Find the Original JPEG File Name Used in a PDF

Question details
The user wants to identify and retrieve the original file name of a JPEG image that has been embedded into a PDF document.
- Product
- Device & OS
- not provided
- Scenario
- Attempting to locate the source file name of an image inserted into an existing PDF file for reference or extraction purposes.
- Observed behavior
- The original JPEG file name is usually stripped or not visibly retained after the document is converted or saved as a PDF.
Keep in mind that most PDF creation processes strip the original file name of embedded images to optimize file size, meaning the exact name may not always be recoverable.
Check Image Properties and Tooltips
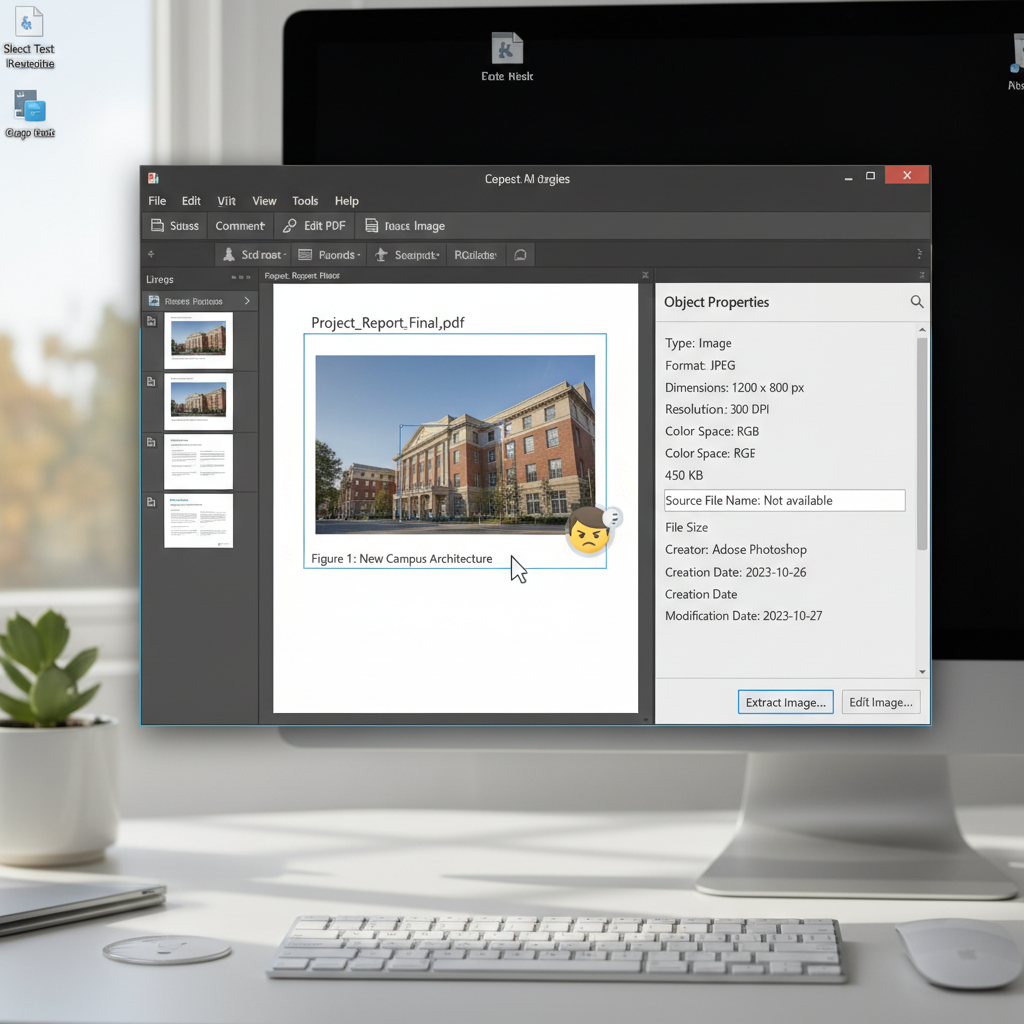
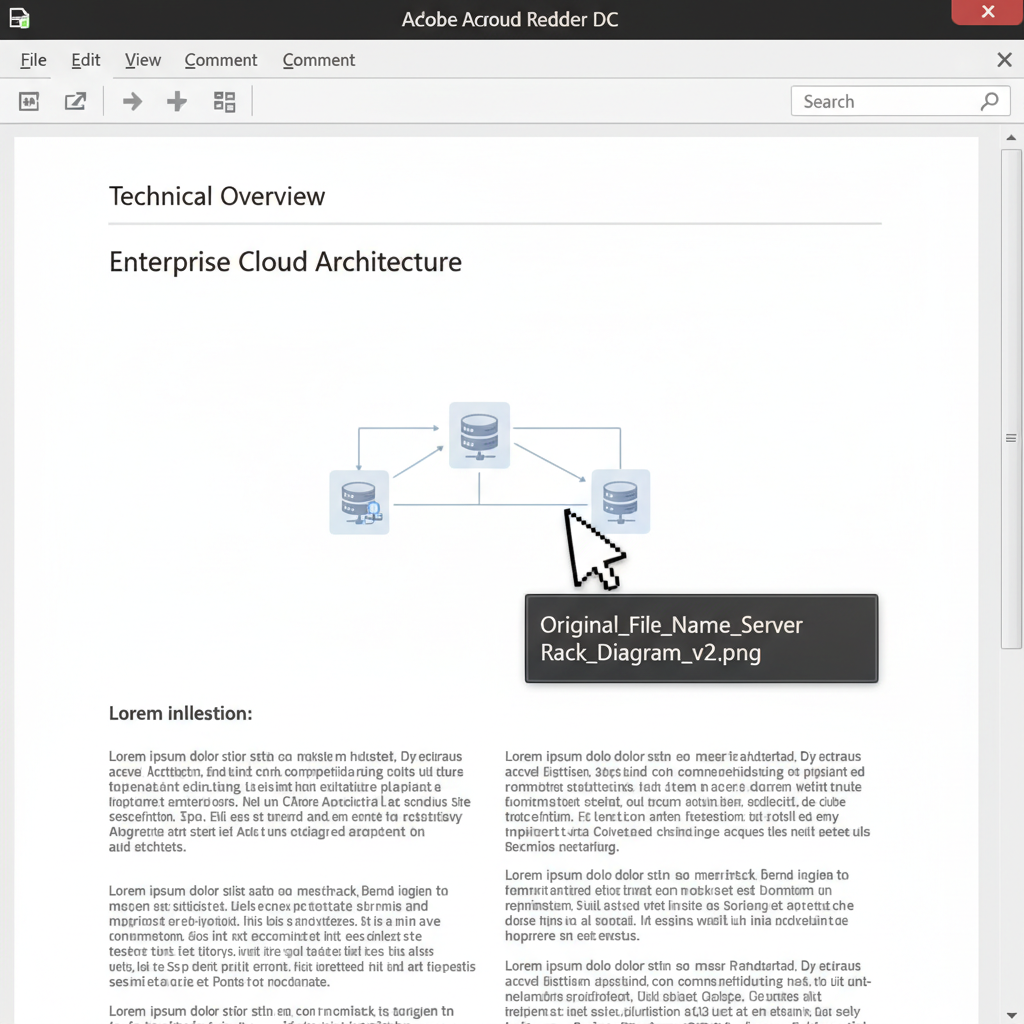
Sometimes the original file name or related metadata is preserved as an image tooltip or within the object properties.
While standard PDF conversion often removes image metadata, some workflows or specific software settings preserve the source file name as hover text or basic object properties.
Open the PDF in your viewer, place your mouse cursor over the target image, and pause. Look for a tooltip or alternate text popup that might display the original file name.
Right-click the image and select 'Properties', 'Object Properties', or 'Image Info' if your PDF reader supports editing. Review the Description or Metadata tabs.
Inspect PDF Accessibility Data
If the PDF was created with accessibility tags, the source image name might be stored as alternate text.
Manage and Extract PDF Images with WPS Office
Use WPS Office's built-in PDF tools to seamlessly interact with embedded objects, view image properties, or extract pictures from your PDF documents.
- 1. Open your PDF: Launch WPS Office and open the PDF document containing the target image.
- 2. Enter Edit Mode: Navigate to the 'Edit' tab on the top ribbon and select 'Edit Content' to make the embedded objects selectable.
- 3. Interact with the image: Right-click the image to view its properties, or select 'Save Image As' to extract the JPEG to your local drive.

Frequently Asked Questions
Why does a PDF remove the original image file names?
When a document is exported or printed to PDF, the images are usually decoded and re-embedded as raw pixel data streams. This process optimizes the file size and removes unnecessary external metadata, including original file directories and names.
Can I extract the JPEG from the PDF to see its original name?
You can extract the image using a PDF editor, but the extracted file will typically be assigned a generic sequence name (like 'image001.jpg') rather than its original source name.
Does the PDF creation method affect whether image metadata is kept?
Yes. Exporting from professional design software with strict metadata and accessibility settings checked is far more likely to retain source image information compared to simply using a 'Print to PDF' virtual printer.


