

How to Fix Acrobat OCR Not Recognizing a Specific Text String

Question details
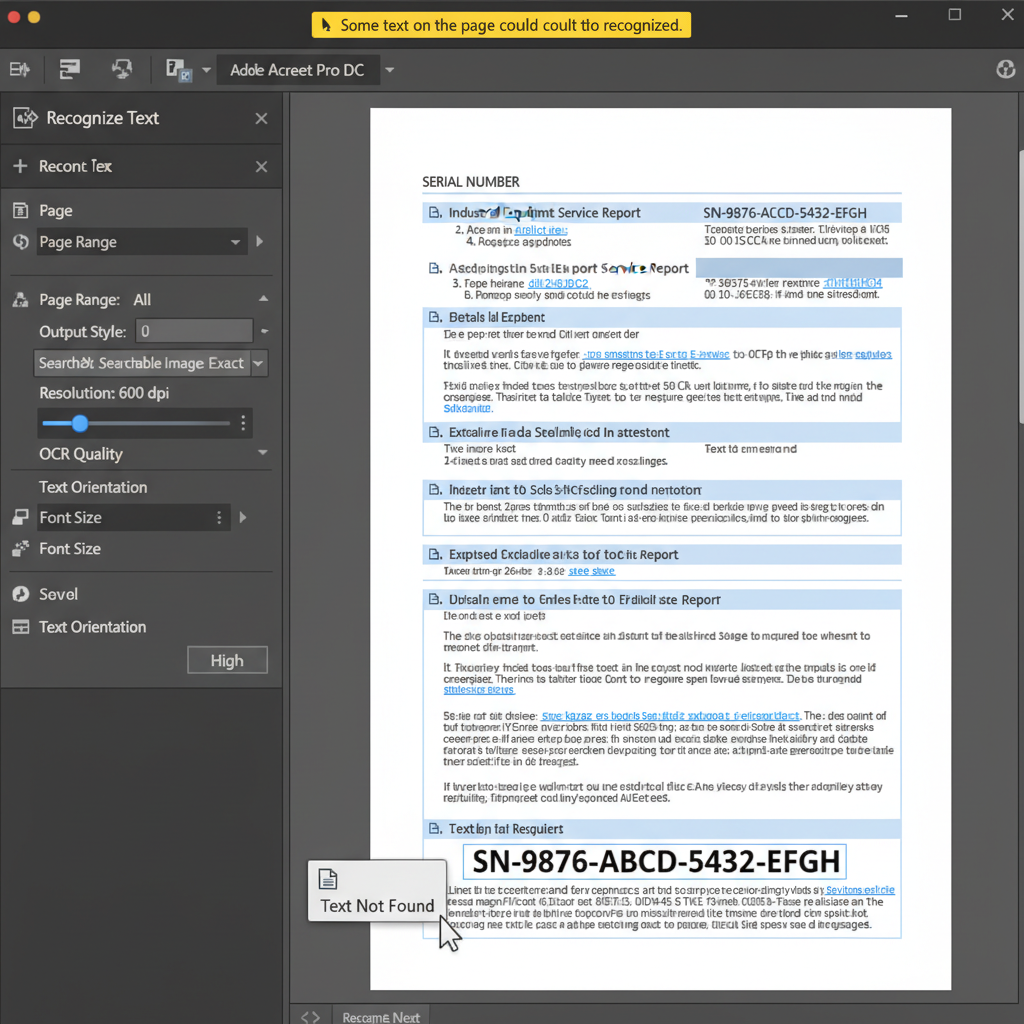
The user is experiencing an issue where Adobe Acrobat's OCR fails to recognize a single specific text string (such as a serial number) on a high-resolution scanned document, despite adjusting font size, alignment, and OCR quality.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running OCR on a 600 dpi scanned PDF document to extract or make text searchable.
- Observed behavior
- The OCR tool successfully processes the entire document except for one specific value, which remains unrecognized regardless of quality settings.
Ensure your PDF software is up to date and that the original scanned document does not have physical smudges, severe fading, or overlapping lines exactly over the unrecognized text area.
Enhance Image Quality and Isolate the Text
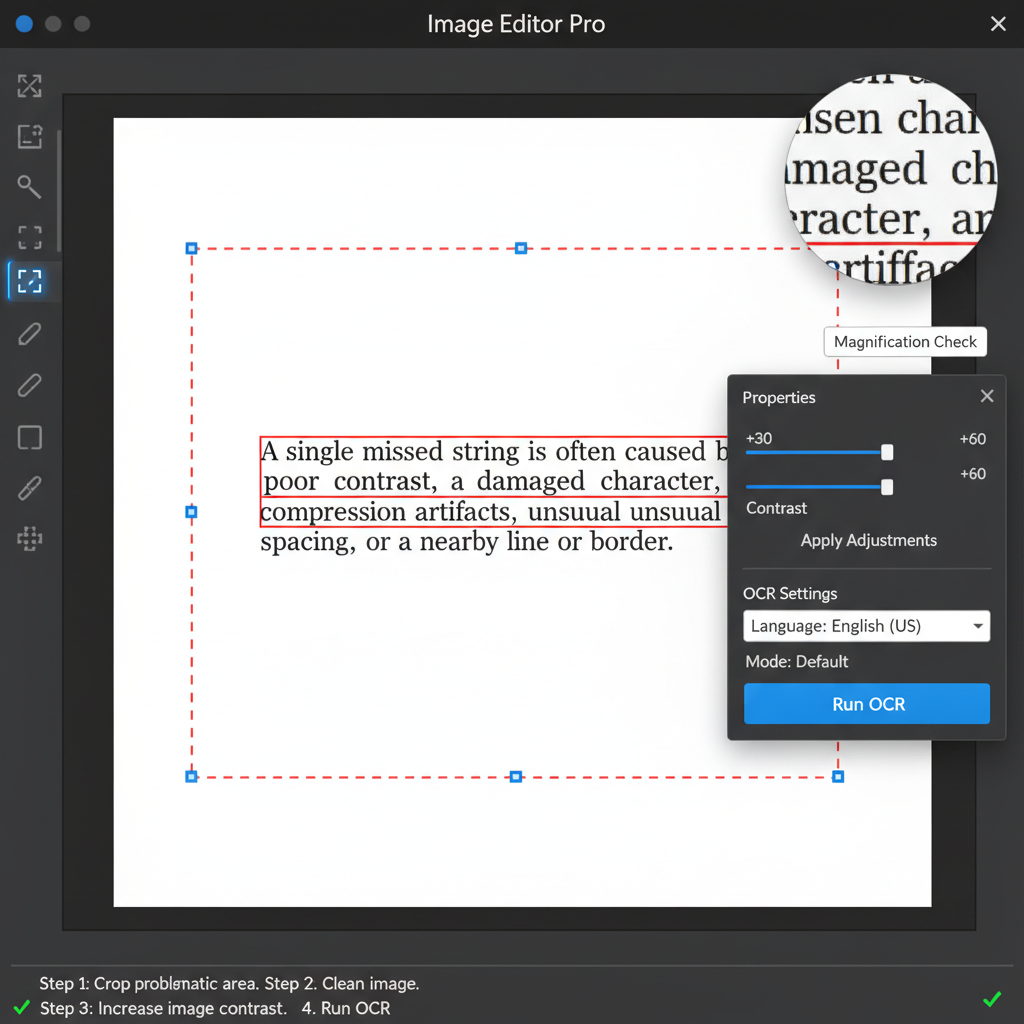
Cleaning up the specific area by cropping and adjusting contrast can help the OCR engine properly process the difficult string.
A single missed string is often caused by poor contrast, a damaged character, compression artifacts, unusual spacing, or a nearby line or border. Isolating the text can remove these interfering elements.
Use an image editing tool or the PDF crop tool to isolate the specific text string that the OCR failed to recognize.
Remove any surrounding lines, borders, or compression artifacts near the text.
Adjust the brightness and contrast settings so the text stands out sharply against the background.
Process just the cropped and enhanced region. You may also want to try a different OCR language or recognition mode if available in your software.
Manually Correct or Replace the Unrecognized Text
If the scan is clear but the OCR engine still fails, manually fixing the error is the most reliable and fastest workaround.
Easily Extract and Edit Text with WPS PDF
If your current PDF editor fails to recognize specific text, WPS Office offers a highly accurate OCR engine. You can effortlessly convert scanned documents into fully editable text, ensuring all serial numbers and special strings are captured.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and select 'OCR' to begin the text recognition process.
- 3. Extract or Edit Text: Choose to extract the text to a new document or make the current PDF searchable and editable.
- 4. Save the Document: Once the text is correctly recognized, save your document to retain the searchable text layer.

Frequently Asked Questions
Why does OCR miss specific characters or numbers?
Poor contrast, damaged characters, unusual font spacing, or interfering background elements like borders can confuse the OCR engine, causing it to skip or misread strings.
Does increasing the DPI always improve OCR accuracy?
Not necessarily. While a 300-600 DPI scan is optimal for OCR, excessively high DPI won't fix structural image issues like faded ink, stray marks, or unusual font types.
Can I manually add searchable text if OCR fails completely?
Yes. In most PDF editors, you can manually insert a hidden text layer or add a standard text box over the unrecognized area to ensure it remains searchable and identifiable.


