

Fix Acrobat XI Redaction Search Not Automatically Running OCR on PDFs

Question details
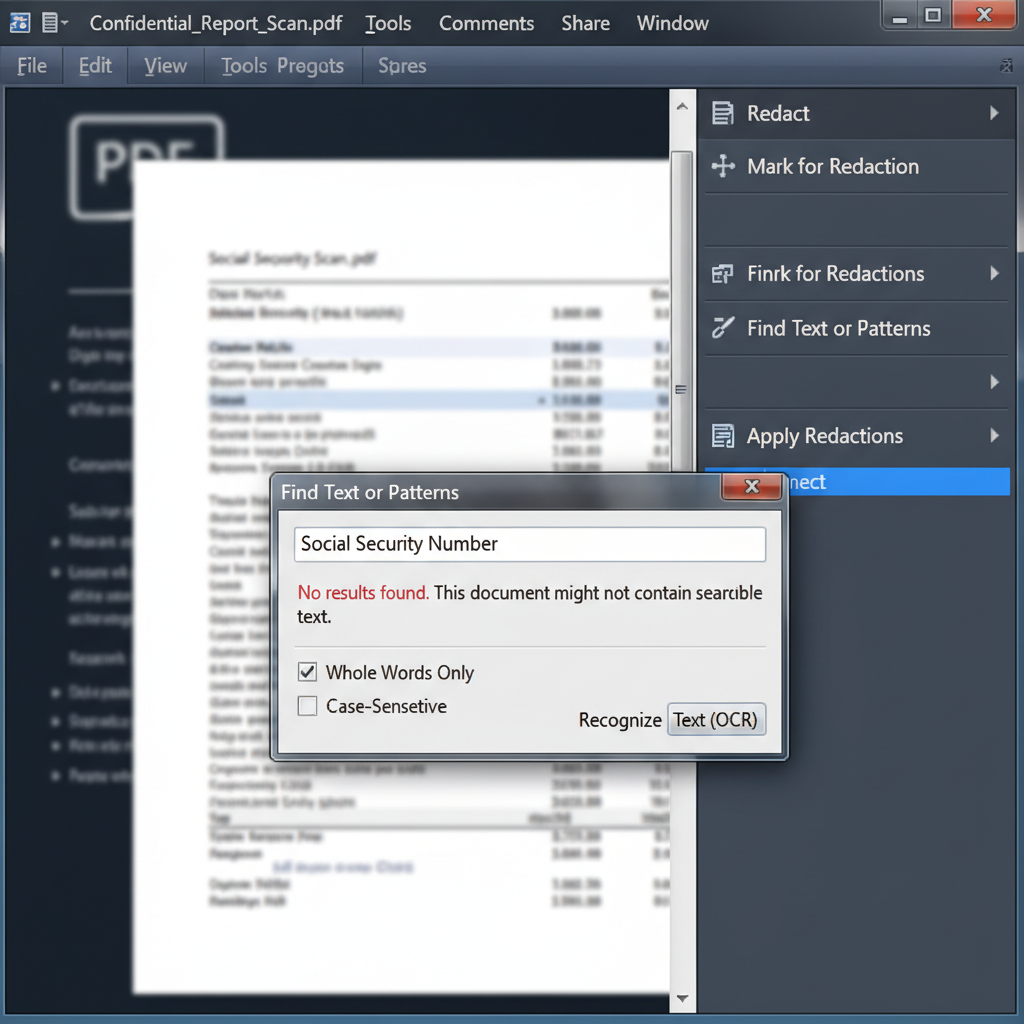
The user is attempting to redact sensitive information in a scanned PDF, but Acrobat XI redaction search fails because it does not automatically initiate OCR to make the document searchable.
- Product
- Adobe Acrobat XI
- Device & OS
- not provided
- Scenario
- Searching for and redacting specific text within a scanned, image-only PDF document.
- Observed behavior
- Acrobat does not automatically trigger the Optical Character Recognition (OCR) process during a redaction search, preventing the software from finding and redacting the specified text.
Verify whether the text in your PDF is already selectable by trying to highlight a few words with your cursor. If the entire page turns blue or acts as a single image, the document is not searchable and strictly requires OCR before redaction can be performed.
Manually Run OCR Text Recognition
Force the application to recognize text before launching the redaction search tool, ensuring all scanned images are converted into searchable data.
Redaction search requires a text layer to identify specific words. If the automatic trigger fails because of a previously saved 'Do Not Recognize' choice, running OCR manually will bypass the block and prepare your document for redaction.
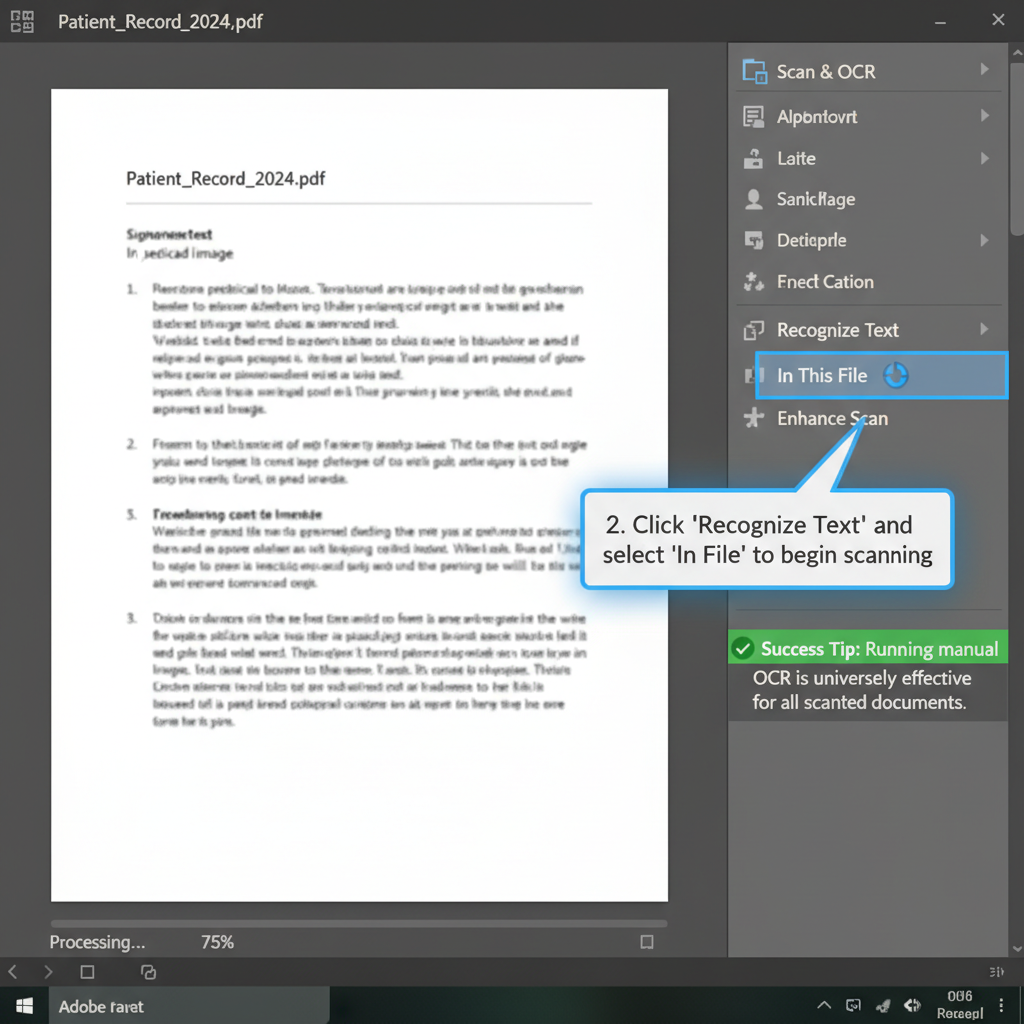
Open your scanned PDF document in Acrobat and navigate to the 'Scan & OCR' tool menu located in the right-hand pane.
Click on 'Recognize Text' and select 'In This File' to begin scanning the current document.
Once the OCR process finishes, try highlighting text on the page with your cursor to confirm it is now selectable.
Open the Redaction tool and run your search again; the software should now successfully locate and redact the designated terms.
Reset Acrobat OCR Prompts and Preferences
Clear previously stored user choices that command the application to skip text recognition automatically.
Enable Scan Optimization for Image Imports
Adjust the conversion settings so that imported image files are automatically optimized and OCR'd upon being converted to PDF.
Easily Recognize and Redact Text with WPS PDF
WPS Office provides a comprehensive PDF toolkit that seamlessly integrates Optical Character Recognition (OCR) and secure redaction. Easily extract text from scanned documents and permanently remove sensitive information without battling complex settings.
- 1. Open Scanned PDF: Launch WPS Office and open your image-based or scanned PDF document.
- 2. Run OCR Extract: Navigate to the 'Tools' tab and click on the 'OCR' feature to convert the page images into fully searchable text.
- 3. Select Redaction Tool: Switch to the 'Protect' tab and select the 'Redact' tool to initiate your search.
- 4. Apply and Save: Search for your sensitive keywords, apply the redaction marks, and save the document to permanently remove the text.

Frequently Asked Questions
Why does my PDF page turn entirely blue when I try to select text?
If an entire page turns blue or acts like a single block when clicked, the PDF is a flat image rather than a document with readable text layers. You must run OCR to convert that image into searchable text before interacting with individual words.
Do I need to run OCR on all PDFs before applying redaction?
No, OCR is only required for scanned PDFs or image-based documents. If your PDF was exported from a word processor and already contains selectable text, you can proceed directly to redaction search.
Why doesn't the redaction tool automatically OCR my scanned documents?
The application might have remembered a previous user choice to skip text recognition, or the default scan optimization settings for imported image formats may be disabled in your preferences.
Can I run OCR directly on a JPG or PNG file?
You must first convert the image file into a PDF. Depending on your software settings, OCR might run automatically during conversion, or you may need to initiate an additional manual OCR step afterward.


