

How to Fix Garbled Text When Converting PDF to Apache OpenOffice

Question details
The user needs to recover readable text from a PDF document that appears corrupted or unreadable after being converted for Apache OpenOffice.
- Product
- Apache OpenOffice
- Device & OS
- not provided
- Scenario
- Converting a PDF document to an editable format and opening it in Apache OpenOffice.
- Observed behavior
- The converted text appears corrupted, unreadable, or garbled, typically due to nonstandard fonts, incorrect encoding, or unusual file structures in the source PDF.
Ensure you have the original PDF file accessible and a basic plain-text editor (like Notepad or TextEdit) ready to test the document's baseline text encoding.
Test Source Text Encoding and Recreate Document
Determine if the issue stems from the source PDF's encoding by copying the text directly into a plain-text editor, which helps identify broken font dictionaries.
When a PDF is created using nonstandard fonts without properly embedding character mapping, standard conversion tools cannot interpret the text. This solution helps verify if the text layer is permanently corrupted.
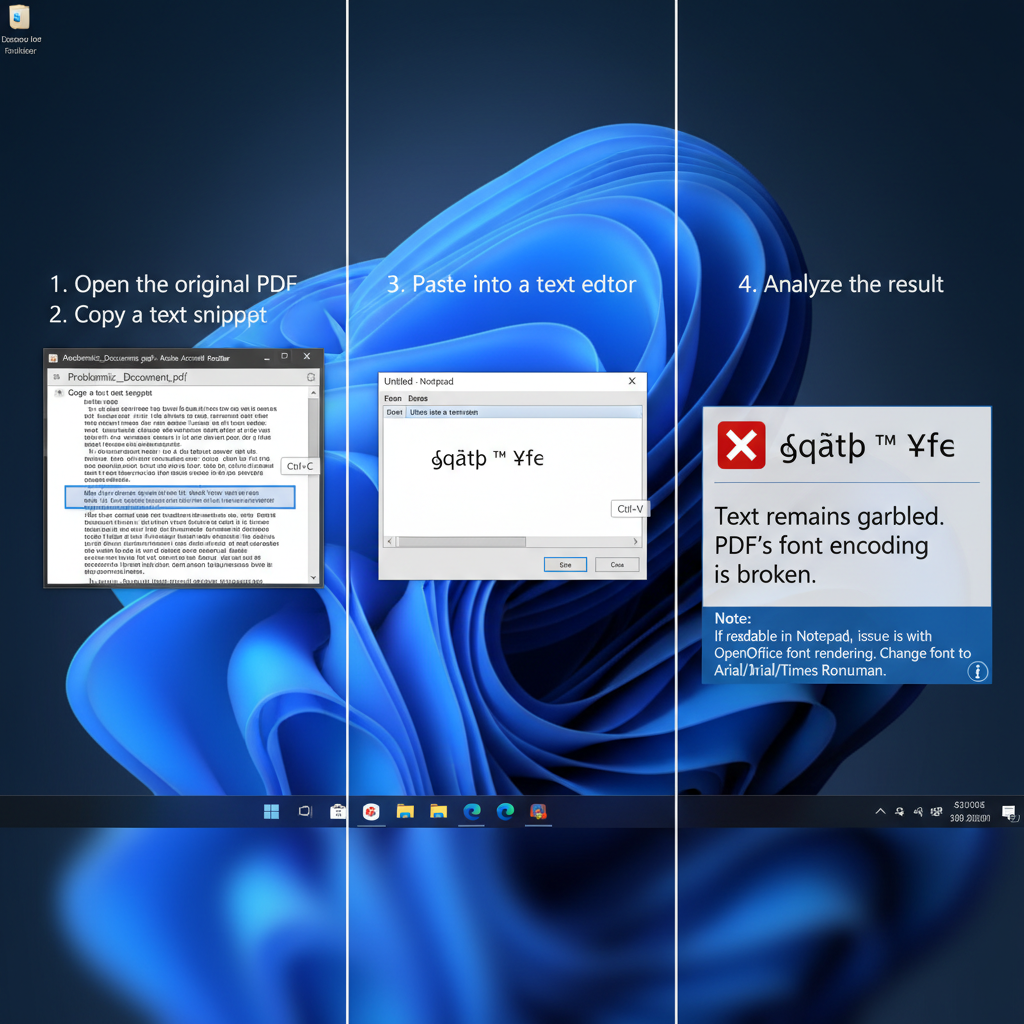
Launch your default PDF reader and open the problematic source PDF file.
Highlight a paragraph of the text that appeared garbled in OpenOffice and press Ctrl+C (or Cmd+C on Mac) to copy it.
Open a plain-text editor such as Notepad, and press Ctrl+V to paste the extracted text.
If the pasted text remains garbled in Notepad, the PDF's font encoding is broken. You will need to obtain a new copy from the creator or use an OCR tool to visually scan the text.
Use OCR Technology to Bypass Font Issues
When underlying text encoding is broken, Optical Character Recognition (OCR) visually reads the document to generate entirely new, accurate text.
Convert PDFs Accurately with WPS Office
Avoid garbled text and broken formatting by using WPS Office's built-in PDF to Word converter. Equipped with advanced OCR and intelligent font-mapping technology, WPS Office seamlessly transforms complex PDFs into highly editable documents without losing readability.
- 1. Open your PDF in WPS: Launch WPS Office and open your problematic PDF file in the dedicated PDF viewer.
- 2. Select PDF to Word: Navigate to the 'Tools' tab and click on the 'PDF to Word' conversion button.
- 3. Enable OCR feature: If your document contains broken encoding or scanned images, check the OCR option to ensure accurate visual text extraction.
- 4. Convert and Edit: Click 'Start' to convert. The accurately extracted text will immediately open in WPS Writer, ready for editing without any garbled characters.

Frequently Asked Questions
Why does my converted PDF text look like random symbols?
This typically happens because the PDF was created using non-standard or custom fonts that were not properly embedded into the document's structure. When converted, the software cannot map the visual characters to standard text encoding, resulting in random symbols or garbled text.
Can Apache OpenOffice open PDF files natively?
Apache OpenOffice requires a specific extension (like the PDF Import Extension) to open PDFs natively. However, this often imports PDFs as distinct graphics or isolated text boxes, making it highly prone to formatting and encoding errors compared to dedicated PDF conversion tools.
How do I know if my PDF is an image or encoded text?
Open the PDF in any standard PDF reader and attempt to select or highlight individual words. If you can only select the entire page as a single blue block, it is an image-based PDF. If you can highlight words but they paste as gibberish in another app, it is an encoding issue.
Is there a way to permanently fix a PDF with a bad font dictionary?
Once a PDF is exported with a missing or corrupt font dictionary, the underlying native text data cannot be retrieved through standard extraction tools. You must bypass the encoding layer by using a PDF tool with Optical Character Recognition (OCR), which visually reads the document to recreate the text from scratch.


