

How to Fix Microsoft Lens PDF Missing Searchable OCR Layer

Question details
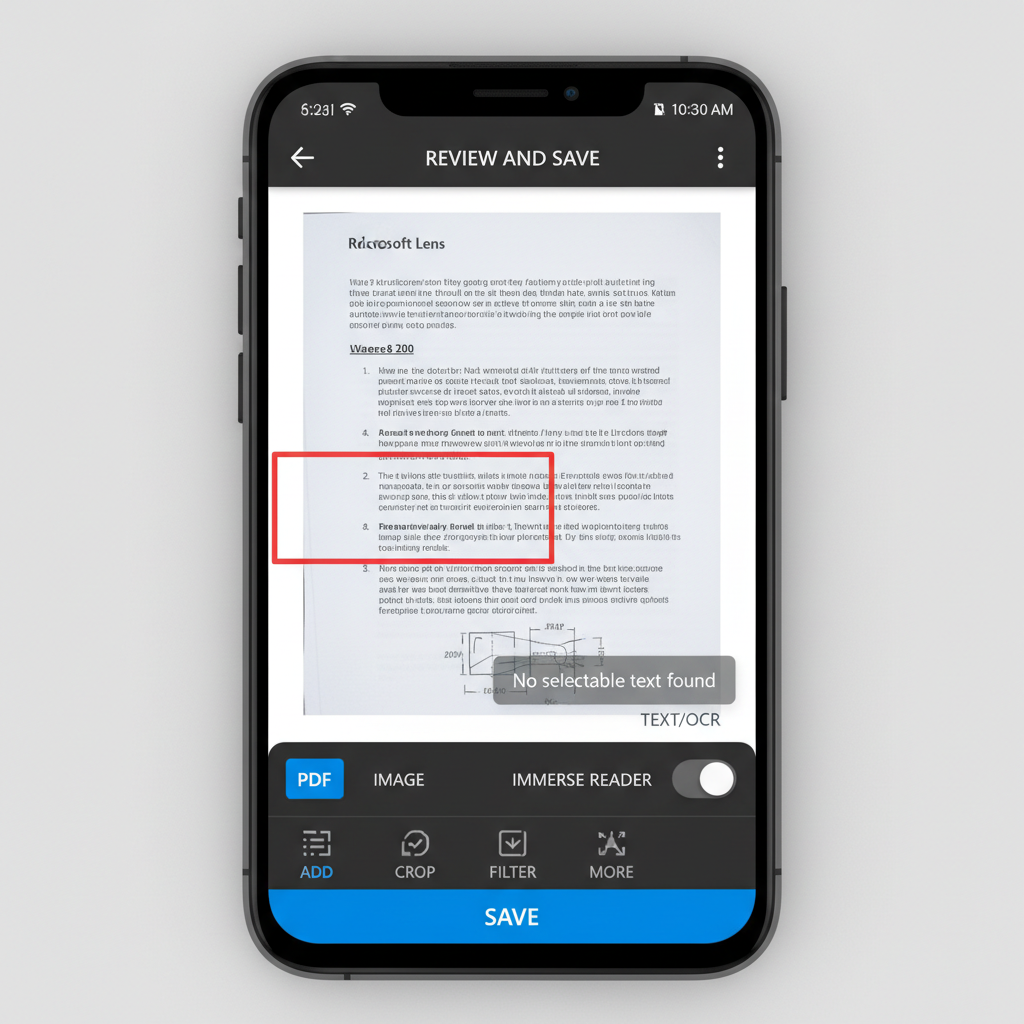
Users are experiencing issues where Microsoft Lens no longer generates a searchable OCR (Optical Character Recognition) layer when scanning documents to PDF.
- Product
- Microsoft Lens
- Device & OS
- not provided
- Scenario
- Scanning physical documents to PDF using Microsoft Lens and attempting to search or copy text.
- Observed behavior
- The resulting PDF is saved as a flat image without a searchable text layer, preventing users from selecting, copying, or searching for text within the document.
Ensure your device is connected to the internet, as some OCR processing requires cloud connectivity, and verify that you are scanning the item in 'Document' mode rather than 'Photo' mode.
Save the Scanned PDF to OneDrive for Cloud OCR Processing
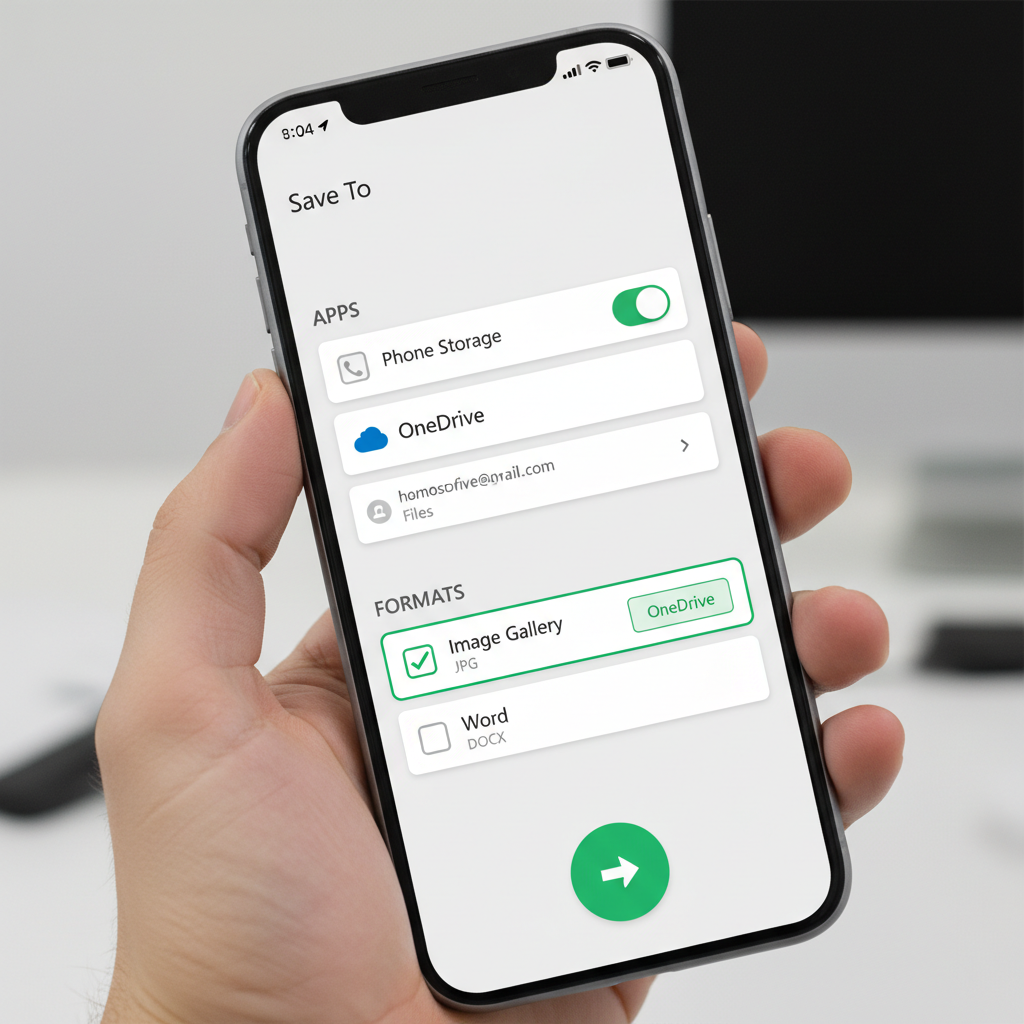
Storing the file locally on your phone may bypass the OCR generation. Uploading it to OneDrive triggers cloud-based OCR processing.
Recent updates to Microsoft Lens have shifted some OCR processing to the cloud. When you save a scan directly to your phone's local storage, the app may simply save a flat image to save time and processing power. Saving to OneDrive forces the document to pass through Microsoft's servers, where the text layer is actively generated.
Open Microsoft Lens, swipe to select the 'Document' mode, and take a picture of your paper document.
Adjust the cropping borders if necessary to frame only the document, then tap 'Confirm' followed by 'Done'.
On the 'Save To' screen, uncheck your local phone storage and ensure that 'OneDrive' is checked under the PDF section.
Open the saved PDF from your computer or another device via OneDrive to verify that the searchable OCR text layer has been successfully generated.
Update Microsoft Lens and Verify Scan Modes
Outdated app versions or incorrect scan modes can prevent OCR layers from being applied to your PDFs.
Use WPS Office to Easily Create Searchable PDFs
If Microsoft Lens continues to drop the OCR layer, you can use the built-in scanner and OCR tools in WPS Office. It accurately extracts text from images and creates highly compatible, searchable PDFs directly on your mobile device or PC.
- 1. Launch the scanner tool: Open the WPS Office mobile app and tap the 'Scanner' or 'Camera' icon on the home screen.
- 2. Capture the document: Select 'Document' mode, capture your physical paper, and adjust the crop boundaries as needed.
- 3. Apply OCR processing: Tap 'OCR' or 'Extract Text' to process the image and convert it into a searchable and editable text format.
- 4. Save as PDF: Save or export the finalized document as a PDF to your local device or WPS Cloud for immediate use.

Frequently Asked Questions
Why does Microsoft Lens sometimes save PDFs as images without text?
This typically happens when the file is saved directly to local phone storage without an internet connection, or if the scan was captured in 'Photo' mode instead of 'Document' mode. Cloud processing via OneDrive is often required to generate the OCR text.
Can I extract text from an existing unsearchable PDF?
Yes. You can use a dedicated OCR tool like the one built into WPS Office or Adobe Acrobat to process the existing flat PDF image and add a searchable, selectable text layer.
Is the OneDrive OCR processing immediate?
Not always. When you save a scan to OneDrive via Microsoft Lens, it is uploaded to Microsoft's cloud servers where the OCR processing happens in the background. It might take a few minutes for the text to become fully searchable.
Does Microsoft Lens support OCR for handwriting?
Microsoft Lens does support OCR for clear, legible handwriting, but it works most reliably with printed text. If handwriting is messy or cursive, the generated text layer may be highly inaccurate or omitted entirely.


