

How to Fix Misspelled Text When Converting PDF to Word

Question details
Converted Word documents contain spelling errors or incorrect characters after exporting from PDF.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF document into an editable Microsoft Word format.
- Observed behavior
- The resulting Word document has misspelled words, jumbled letters, or weird symbols, particularly when Optical Character Recognition (OCR) is applied to the file.
Check if your original PDF contains standard selectable text or if it is a scanned image, as this will dictate whether OCR is actually necessary.
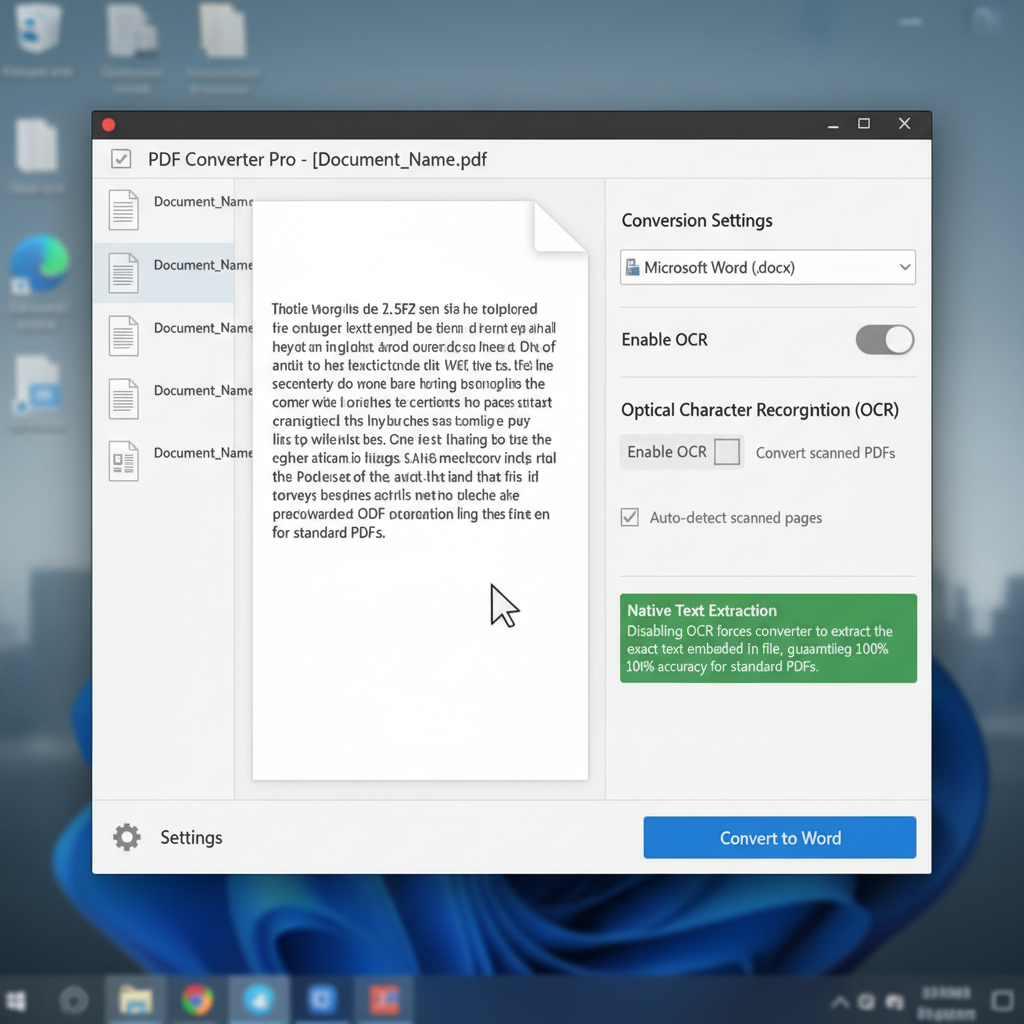
Disable OCR for PDFs with Native Text
If your PDF was created digitally and already contains selectable text, disabling OCR prevents the software from misinterpreting characters.
Optical Character Recognition (OCR) is designed to read text from images. When applied to standard, digitally-created PDFs that already have perfectly readable text, the OCR engine might misinterpret certain fonts, leading to unnecessary spelling errors or jumbled characters.
Launch your PDF to Word conversion software and import the problematic PDF file.
Look for a 'Settings' or 'Preferences' button, usually located near the output format options or at the bottom of the conversion window.
Find the setting labeled 'Enable OCR', 'Optical Character Recognition', or 'Convert scanned PDF'. Uncheck this option to disable it.
Click 'Convert' or 'Export' to generate the Word document. The text should now perfectly match the original PDF without OCR errors.
Use OCR for Scanned PDFs and Proofread Manually
Scanned PDFs require OCR to make text editable, but recognition errors may occur based on image quality.
Convert PDFs Accurately with WPS Office
WPS Office offers an advanced PDF to Word conversion tool equipped with an intelligent OCR engine. It automatically detects whether a file is standard or scanned, maximizing text accuracy and preserving the original layout with minimal spelling errors.
- 1. Open PDF in WPS Office: Launch WPS Office and open your target PDF file in the application.
- 2. Select PDF to Word: Navigate to the 'Tools' tab on the top ribbon and click the 'PDF to Word' icon.
- 3. Configure Conversion Settings: Choose the output language and format (.docx). WPS Office will automatically optimize the OCR settings based on the document type.
- 4. Start Conversion: Click 'Start' to export the file. Once finished, the accurate Word document will automatically open for editing.

Frequently Asked Questions
How do I know if my PDF is a scanned image or native text?
Open the PDF in a viewer and try to highlight a single word using your mouse. If you can select individual words and copy them, it is a native PDF with selectable text. If the entire page turns blue or you cannot highlight text at all, it is a scanned image.
Why does OCR introduce weird symbols instead of letters?
OCR analyzes the shapes of letters in an image and tries to match them to a digital font. If the original scan is blurry, low resolution, or uses heavily stylized fonts, the OCR engine may get confused and output random symbols instead of correct text.
Can I improve the OCR accuracy before converting?
Yes. If you have the original physical document, rescanning it at a higher resolution (at least 300 DPI) and ensuring the page is flat and well-lit will drastically reduce spelling errors during OCR conversion.
Will disabling OCR speed up the conversion process?
Yes. OCR is a resource-intensive process. Disabling it for standard PDFs allows the converter to quickly copy the embedded text, resulting in a much faster and more accurate conversion.


