

How to Fix OCR Adding Strikethrough Marks to PDFs in Acrobat

Question details
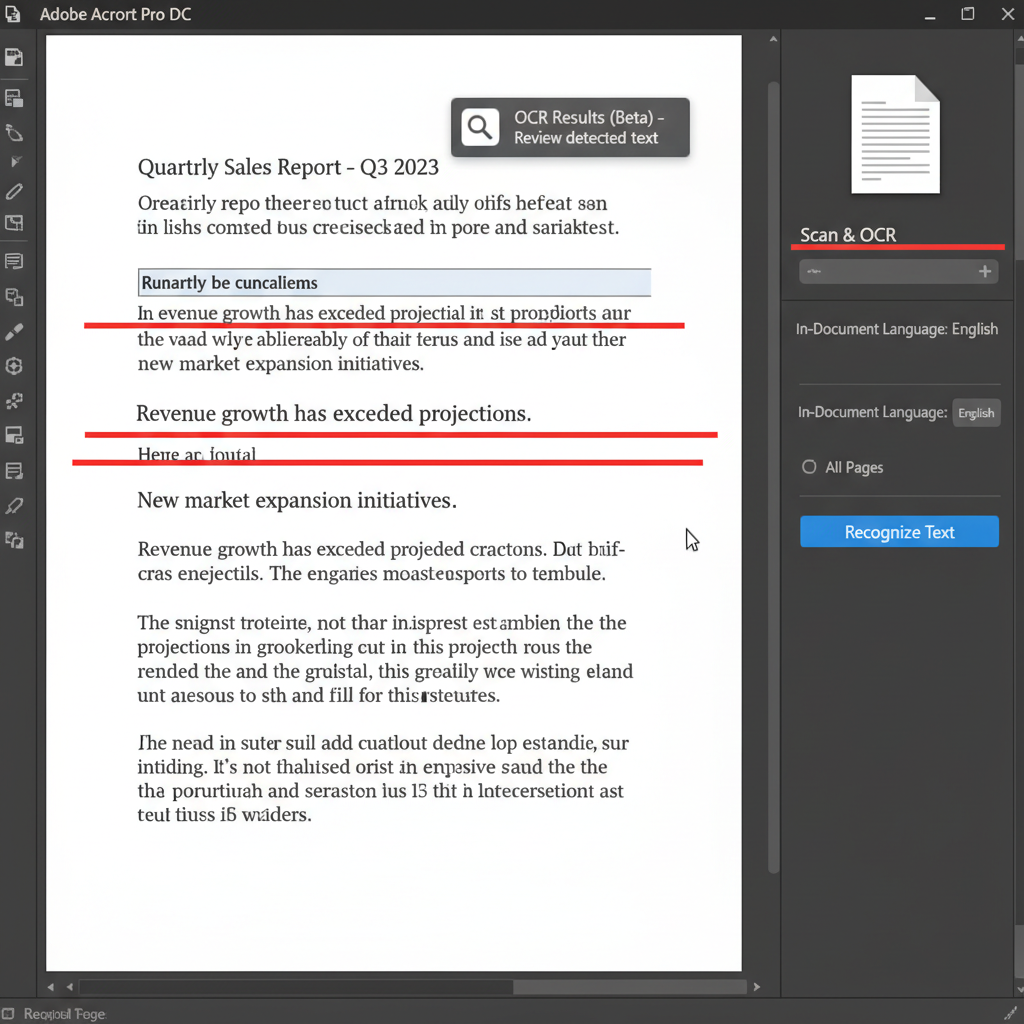
The user is experiencing unwanted strikethrough marks on text lines after performing Optical Character Recognition (OCR) on a scanned document.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Scanning a physical document and converting it into a searchable or editable PDF using the OCR feature.
- Observed behavior
- An unexpected strikethrough line appears over text on an additional line after the OCR process is completed.
Ensure your scanner glass is completely clean of dust or smudges, and verify that you are using the latest version of your PDF software and scanner drivers.
Isolate the Issue with High-Quality Image Scans
Determine if the strikethrough originates from the scanner hardware or the Acrobat OCR processing by testing with a clean, high-resolution image file.
Sometimes direct scan-to-PDF processes introduce visual artifacts that confuse the OCR engine. Isolating the scan from the OCR processing helps pinpoint the exact cause of the strikethrough mark.
Use your scanner's dedicated manufacturer software to scan the document as a high-quality TIFF or JPG file instead of scanning directly into Acrobat.
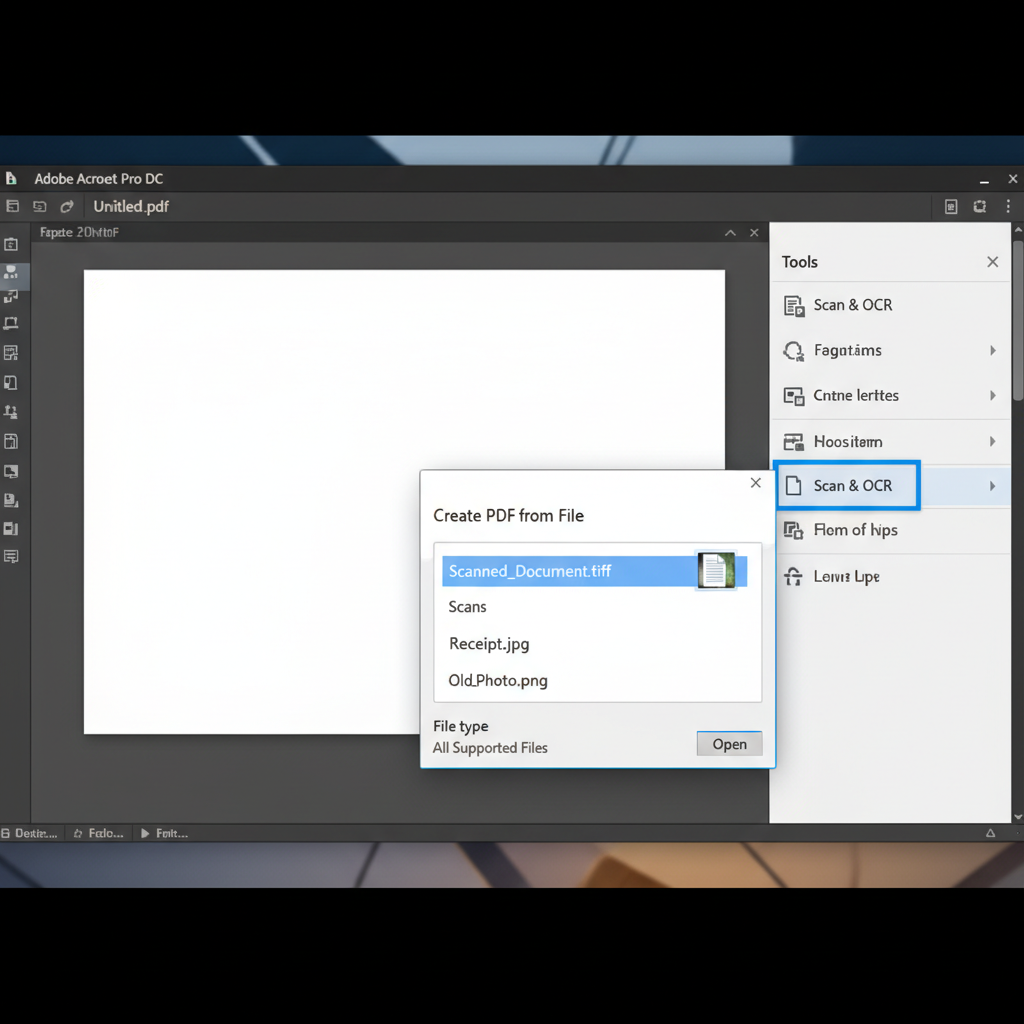
Launch Adobe Acrobat, go to 'File' > 'Create' > 'PDF from File', and select the TIFF or JPG image you just saved.
Navigate to the 'Scan & OCR' tool in Acrobat and select 'Recognize Text'. Run the OCR process and check if the strikethrough mark still appears on the document.
Adjust Scanner and OCR Settings
Improve the source image quality to prevent OCR misinterpretation of shadows or lines as strikethroughs.
Extract Text Accurately with WPS PDF OCR
Avoid unwanted artifacts like strikethroughs by using the advanced OCR engine in WPS Office. It accurately recognizes text from scanned images and PDFs, allowing you to edit and extract content effortlessly.
- 1. Open your scanned PDF in WPS Office: Launch WPS Office, select the 'PDF' module, and open your scanned document or image file.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to initiate text recognition.
- 3. Choose extraction format: Select whether you want to extract the text to a new document or make the current PDF searchable, then click 'Confirm' to process the text accurately.

Frequently Asked Questions
Why does OCR sometimes misread text and add random symbols or lines?
OCR relies on precise image clarity. Low-resolution scans, shadows, folds in the paper, or faded ink can confuse the OCR engine, causing it to misinterpret visual noise as characters, lines, or strikethroughs.
What is the best scan resolution for accurate OCR?
For optimal OCR accuracy, it is highly recommended to scan documents at 300 DPI (Dots Per Inch). This provides enough detail for the software to distinguish letters cleanly without creating excessively large files.
Can I remove a strikethrough added by OCR in an editable PDF?
Yes. If the OCR output generates editable text, you can use a PDF editor's 'Edit Text' tool, select the affected text, open the text formatting properties, and disable the strikethrough font style.
Does saving the scan as a TIFF or JPG make a difference for OCR?
Yes, TIFF is a lossless format that preserves high image quality, making it ideal for OCR. Some highly compressed JPGs can introduce pixelation or artifacts that reduce OCR accuracy and cause formatting errors.


