

How to Fix PDF OCR and Text Selection in Scanned Patents

Question details
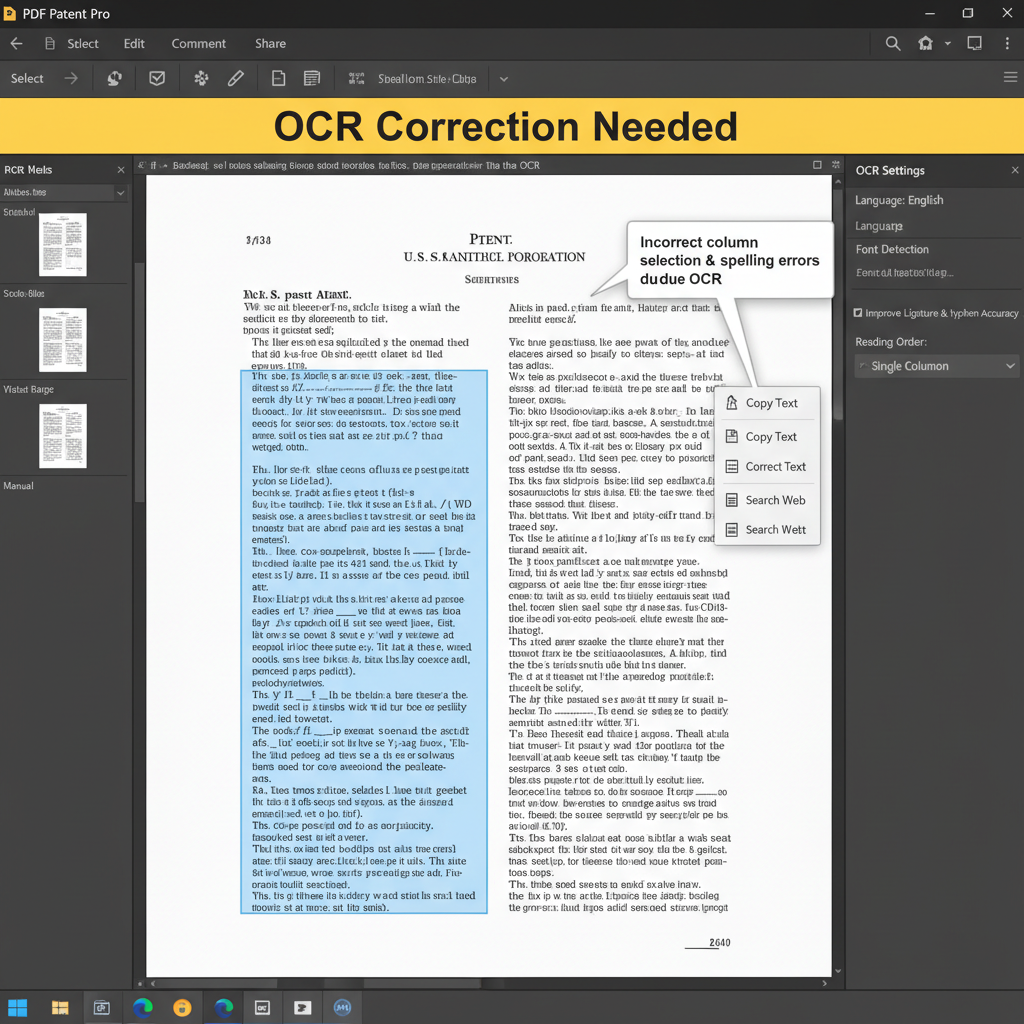
The user needs to improve OCR accuracy to fix ligature and hyphen errors, and correctly select text from a single column in a two-column scanned patent PDF.
- Product
- PDF Editors
- Device & OS
- not provided
- Scenario
- Extracting and copying text from U.S. patent PDFs that feature a two-column layout.
- Observed behavior
- The OCR generates spelling errors for ligatures, letter cases, and hyphens. Additionally, selecting text highlights across both columns instead of staying within one column due to inaccurate reading order.
Ensure you are using the latest version of your PDF editor and verify that the document language is correctly set before running the OCR process.
Re-run OCR and Use Block Selection in Adobe Acrobat
Update your software, re-recognize the text with correct language settings, and use a keyboard shortcut to select text within a single column.
Inaccurate OCR layers and reading orders often cause text selection tools to drag across multiple columns. By re-running the OCR engine and utilizing the Alt-key block selection trick, you can restrict your selection to a specific area.
Go to Help > Check for Updates in Acrobat to ensure you are running the latest version, which contains the most recent OCR engine improvements.
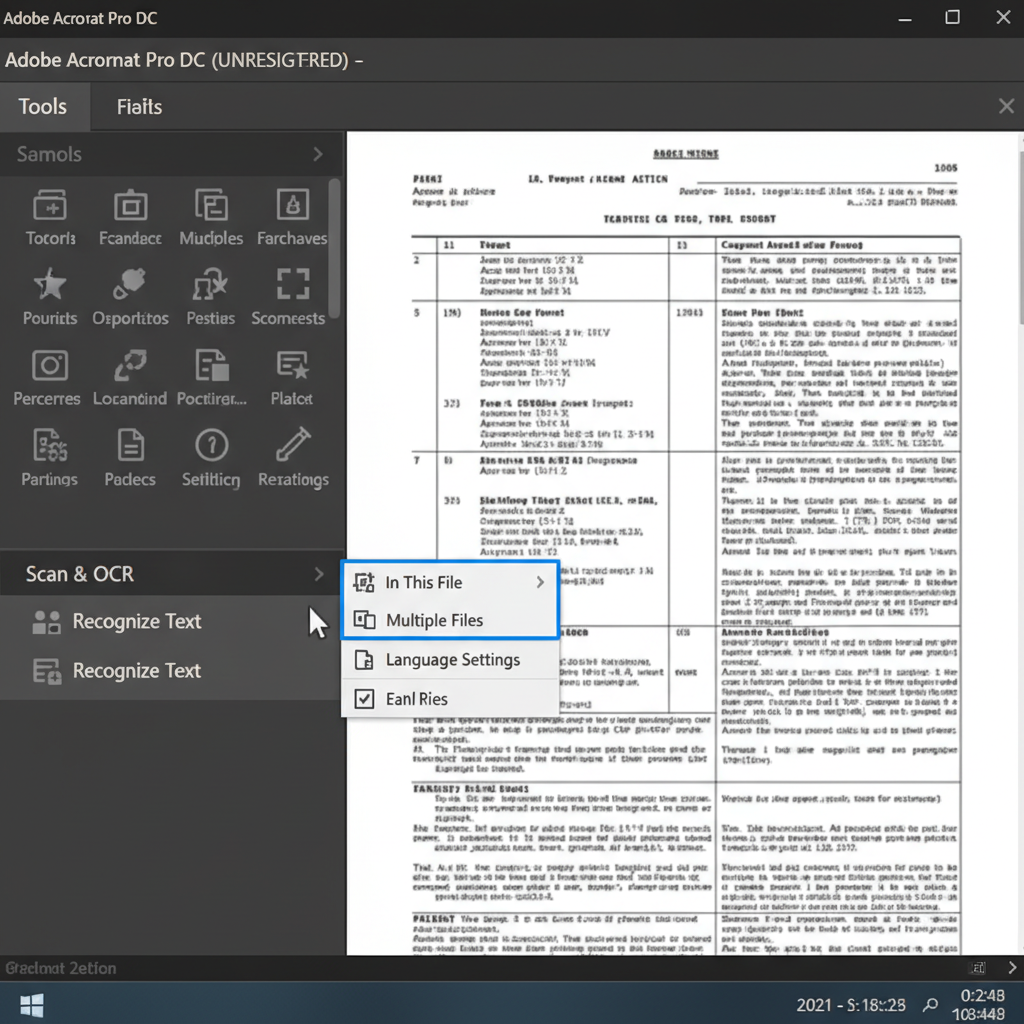
Navigate to Tools > Scan & OCR > Recognize Text. Ensure the document language matches the language of the patent text to minimize ligature and hyphenation errors.
Use the built-in OCR review tools to find and manually correct any remaining errors regarding letter cases, ligatures (like 'fi' or 'fl'), and hyphens.
Select the Text Selection tool. Position your cursor over selectable text, hold down the 'Alt' key, and left-click and drag a rectangular box around the specific column you want to copy.
Use WPS Office to Extract Text from Scanned PDFs
WPS Office provides a powerful built-in PDF editor with highly accurate OCR technology and intuitive text selection tools, making it easy to extract text from complex two-column documents like patents without format corruption.
- 1. Open the PDF in WPS Office: Launch WPS Office and click on 'PDF Edit' to open your scanned patent document.
- 2. Run the OCR Tool: Navigate to the 'Tools' tab and click 'OCR' to convert the scanned image pages into selectable and editable text.
- 3. Configure OCR Settings: Choose the correct document language and layout settings to ensure accurate recognition of ligatures and two-column structures.
- 4. Select and Copy Text: Once the OCR process is complete, use the text selection tool to highlight and copy the exact text block you need from a single column.

Frequently Asked Questions
Why does PDF text selection highlight across both columns?
This happens when the PDF's internal reading order or OCR layer is inaccurate. The software interprets the text horizontally across the entire page rather than reading down one vertical column before moving to the next.
Can I continuously select text from the bottom of column A to the top of column B?
Generally, block selection tools (like holding the Alt key while dragging) only allow you to select a rectangular area within a single column. You will need to copy and paste each column's text separately.
How do I fix ligature and hyphenation errors in PDF OCR?
Ligature errors (where characters like 'fi' or 'fl' are incorrectly combined) can be minimized by ensuring your OCR tool is set to the correct language and highest quality setting. If errors persist, you must use the OCR review or 'Edit Text' tools to manually correct them.
Does WPS Office support OCR for scanned PDFs?
Yes, WPS Office includes a built-in OCR feature that can accurately extract text from scanned images and PDFs, making it easy to edit or copy content from documents with complex multi-column layouts.


