

Improve OCR Accuracy in Adobe Acrobat Pro for Scanned PDFs

Question details
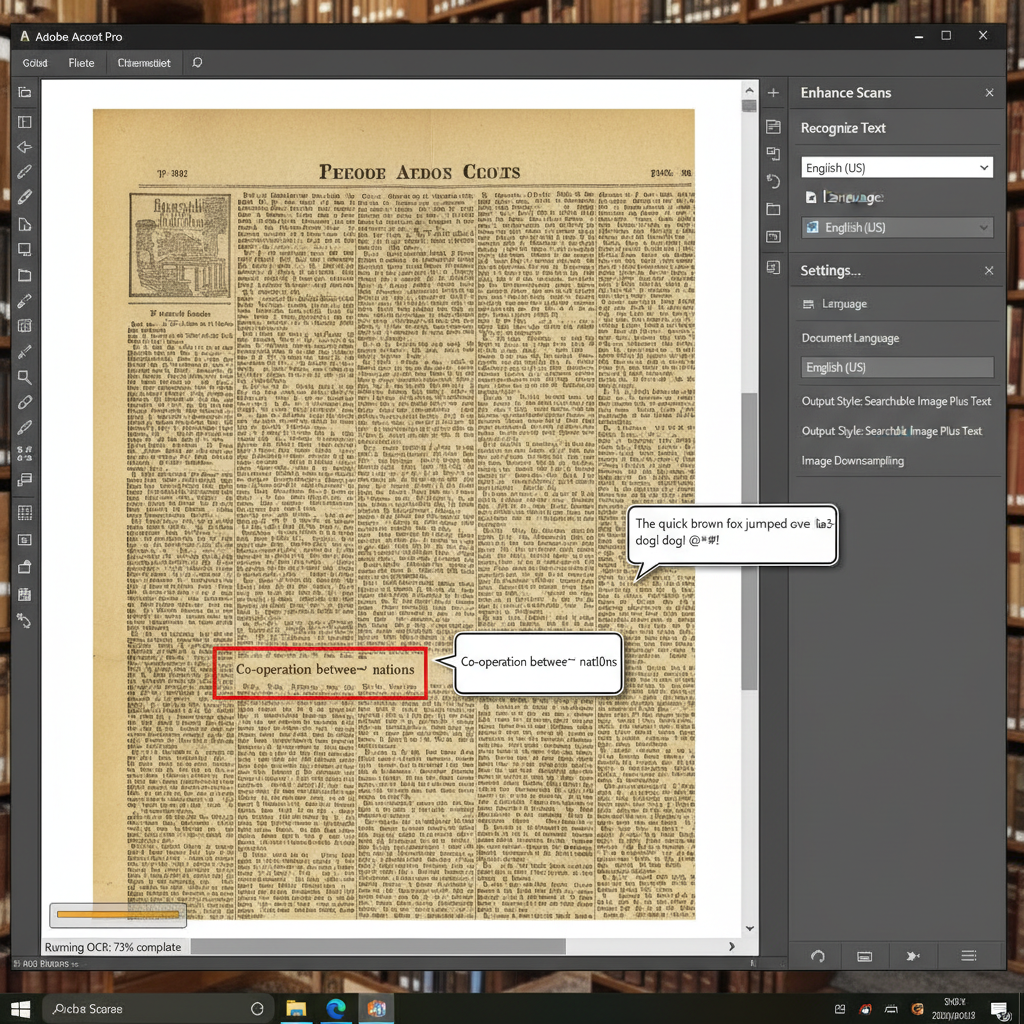
The user is experiencing OCR errors and unwanted special characters when processing scanned historical newspapers in Acrobat Pro and wants to know how to improve text recognition results.
- Product
- Adobe Acrobat Pro
- Device & OS
- Windows
- Scenario
- Running OCR on scanned historical documents or newspapers to create searchable PDFs.
- Observed behavior
- The OCR process produces inaccurate text, errors, and unwanted special characters due to poor scan quality.
Ensure your original physical documents are as flat and clean as possible before scanning, as OCR accuracy heavily relies on the quality of the source image.
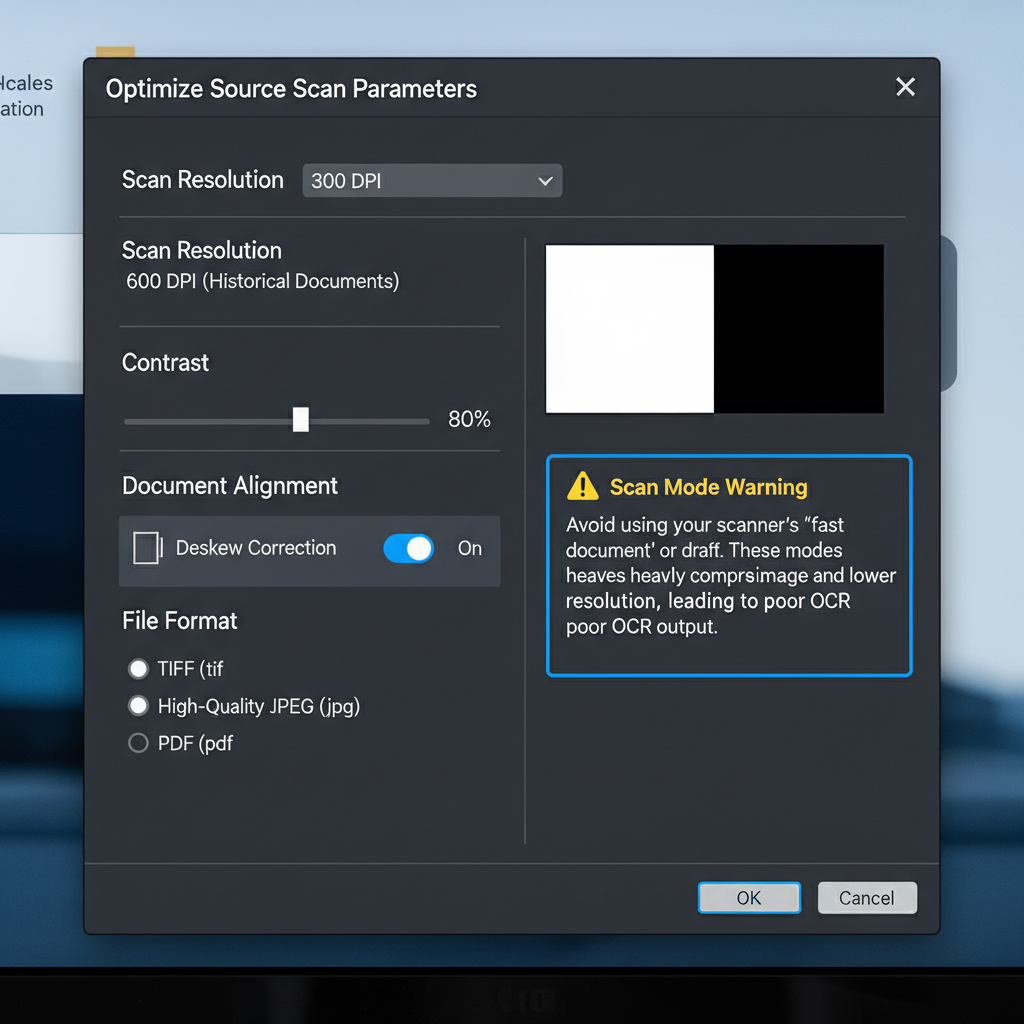
Optimize the Source Scan Settings
Improve the physical scan parameters to give the OCR engine the best possible image to read.
OCR engines analyze the visual features on a page to produce recognizable text. If the input scan is blurry, skewed, or highly compressed, the output will inevitably contain errors. Upgrading your software alone usually will not fix inaccurate recognition if the source file is poor.
Set your scanner to capture at least 300 DPI (dots per inch) for standard text, or 600 DPI for older historical newspapers with faded print.
Adjust the scanner's contrast settings higher to ensure the text stands out clearly against the background paper.
Ensure the physical document is placed squarely on the scanner glass to avoid skewed text lines, which confuse the OCR engine.
Save the initial scan in a high-quality, lossless format like TIFF or high-quality JPEG to prevent compression artifacts.
Configure Acrobat Pro OCR Settings Properly
Adjust the internal settings within Acrobat to better recognize challenging texts.
Use WPS Office for Accurate PDF Text Recognition
WPS Office provides a powerful, highly accurate OCR tool for PDFs. If you are struggling with poor OCR results in other software, WPS PDF's advanced recognition engine can easily convert scanned historical documents and images into editable, searchable text while maintaining the original layout.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select the extraction area: Drag to select the specific area of text you want to extract, or choose to process the entire document.
- 4. Choose output format: Select your desired output format, such as creating a Searchable PDF or extracting the text directly to a Word document.
- 5. Run recognition: Click 'Confirm' to run the OCR recognition and save your newly searchable file.

Frequently Asked Questions
Will upgrading to a newer version of Adobe Acrobat automatically fix my OCR errors?
Not necessarily. OCR capabilities are broadly comparable across recent versions (such as Acrobat Pro 2017 and 2020). Improving the source scan quality, such as resolution and contrast, is much more effective than simply upgrading the software.
What is the best DPI for scanning documents for OCR?
For standard printed text, 300 DPI is generally recommended. For historical documents, old newspapers, or very small fonts, scanning at 600 DPI will yield significantly better OCR accuracy.
Why am I getting weird symbols instead of text after running OCR?
Unwanted special characters and weird symbols appear when the OCR engine cannot confidently identify a letter due to low resolution, blurry text, poor lighting, or high JPEG compression in the source image.
Does the selected language matter for OCR processing?
Yes, selecting the correct language in your OCR settings is crucial. The OCR engine uses language-specific dictionaries to predict and correct words, which dramatically reduces recognition errors.


