

How to Fix PDF to Word Conversions Resulting in Gibberish or Bad Layouts
Question details
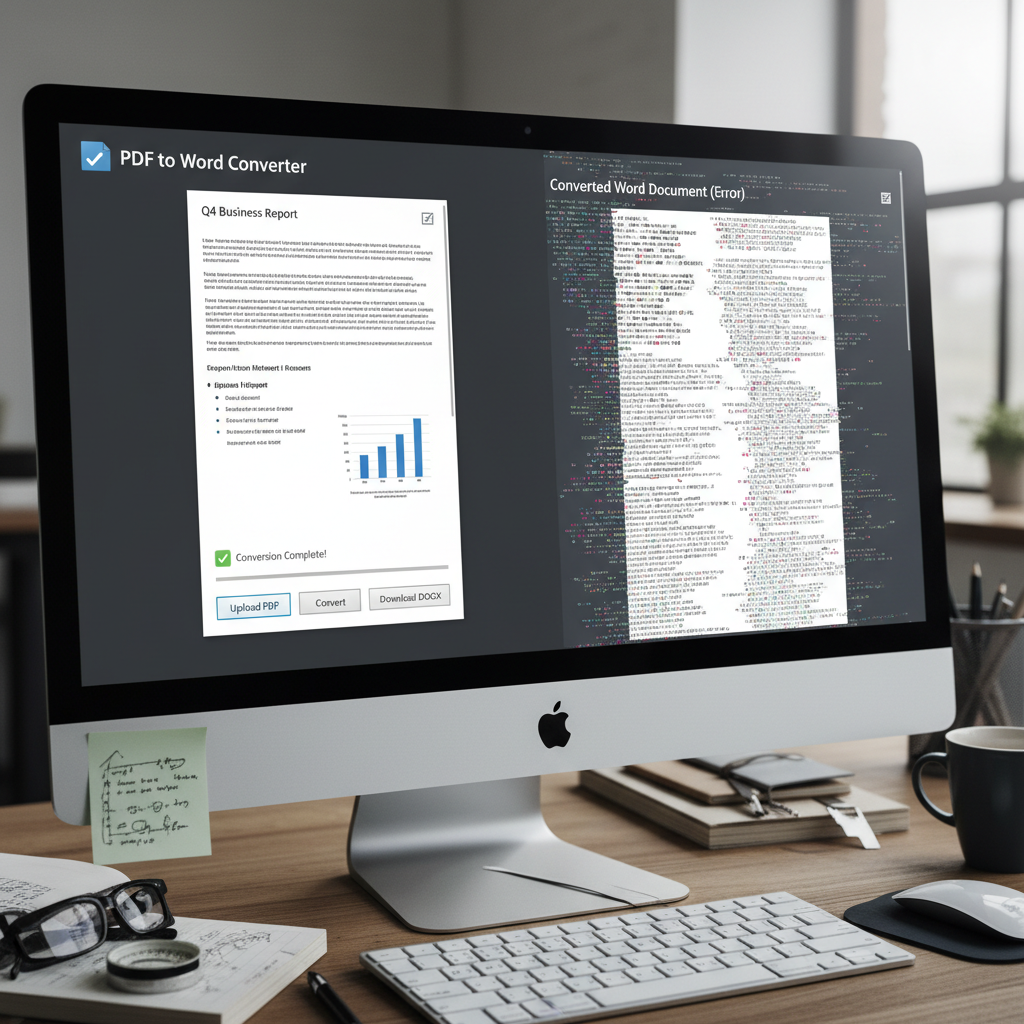
The user needs to resolve an issue where converting a PDF file to a Word document results in unreadable text and a broken layout.
- Product
- PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF document into an editable Word document for updating content or adjusting formatting.
- Observed behavior
- The resulting DOCX file displays gibberish, unrecognizable characters, and a severely altered layout that does not match the original PDF, with no error messages shown.
Verify whether your original PDF is a scanned image or contains encoded text by trying to highlight a single sentence with your cursor. If you can only select the entire page at once, you are dealing with an image-based PDF.
Run OCR on Scanned or Image-Based PDFs
Most gibberish text issues occur because the PDF is an image. Running Optical Character Recognition (OCR) extracts the actual text so it can be converted properly.
Standard PDF to Word converters attempt to extract embedded text. If a document was created using a scanner, it contains a picture of text rather than real text characters. When converted without OCR, the software may generate random symbols instead of readable words.
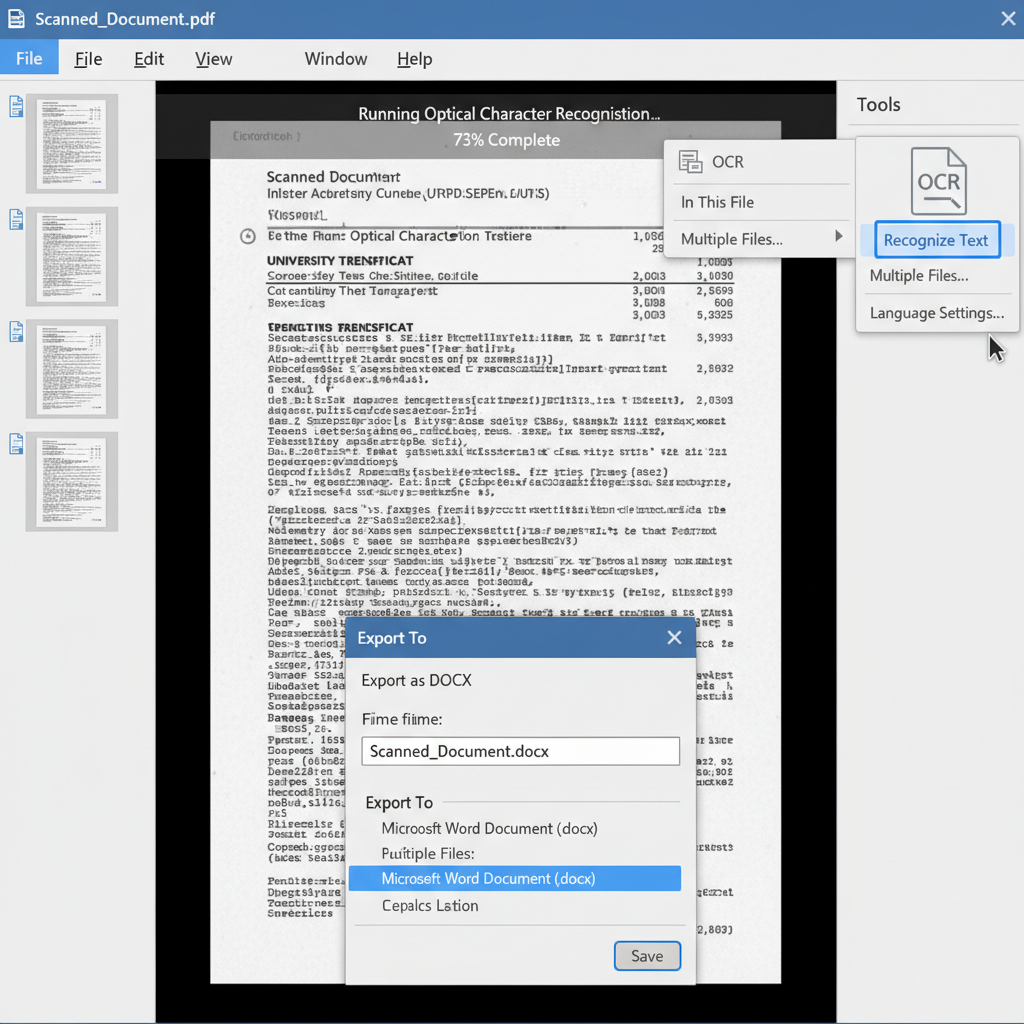
Launch your advanced PDF application, such as WPS Office or Adobe Acrobat, and open the problematic PDF file.
Navigate to the Tools or Edit menu and click on the 'OCR' or 'Recognize Text' option.
Run the OCR process on the entire document, ensuring the correct document language is selected.
Once the text is recognized and selectable, go to 'File', select 'Export to' or 'PDF to Word', and save the document as a DOCX file.
Fix Missing or Unsupported Fonts
If the PDF uses custom or non-standard fonts that aren't embedded or installed on your computer, the converter might substitute them with unreadable characters.
Test with an Alternative File to Identify Corruption
Sometimes the issue is isolated to a single corrupted PDF file. Testing a different file helps determine if the problem is with the document itself or the conversion application.
Convert PDFs to Word Without Gibberish Using WPS Office
WPS Office offers a built-in, highly accurate PDF to Word converter equipped with advanced OCR technology. It seamlessly extracts text from scanned documents and preserves your original layout, preventing gibberish and broken formatting.
- 1. Open PDF in WPS: Launch WPS Office and open the PDF file you want to convert.
- 2. Access PDF to Word: Navigate to the Tools tab on the top ribbon and click on 'PDF to Word'.
- 3. Enable OCR: If your document is scanned, select the OCR option in the conversion prompt to ensure accurate text extraction.
- 4. Convert and Save: Click 'Start' to convert the file. It will automatically open as a perfectly formatted, editable Word document.

Frequently Asked Questions
Why does my converted Word document have strange symbols?
This typically occurs due to missing fonts on your system or because the original PDF was an image without a readable text layer. Running an OCR tool or installing the required fonts usually resolves the strange symbols.
What is OCR and why do I need it for PDF conversion?
OCR stands for Optical Character Recognition. It analyzes images of typed or handwritten text and translates them into machine-encoded text. It is absolutely essential when converting scanned PDFs into editable Word documents, otherwise the converter only sees an unreadable picture.
Can I fix a broken layout after converting PDF to Word?
If the layout is slightly off, you can manually adjust margins, text boxes, and image placements in Word. However, using a high-quality converter with strong layout retention features minimizes layout shifts by preserving the original structure automatically.
How can I tell if my PDF is an image or contains actual text?
Try highlighting a specific word or sentence using your mouse cursor. If you can select individual words and copy them, the PDF contains text. If clicking and dragging selects the entire page as one big block, it is an image-based PDF.


