

How to Fix Uneditable Pages in a PDF Using Acrobat Pro DC

Question details
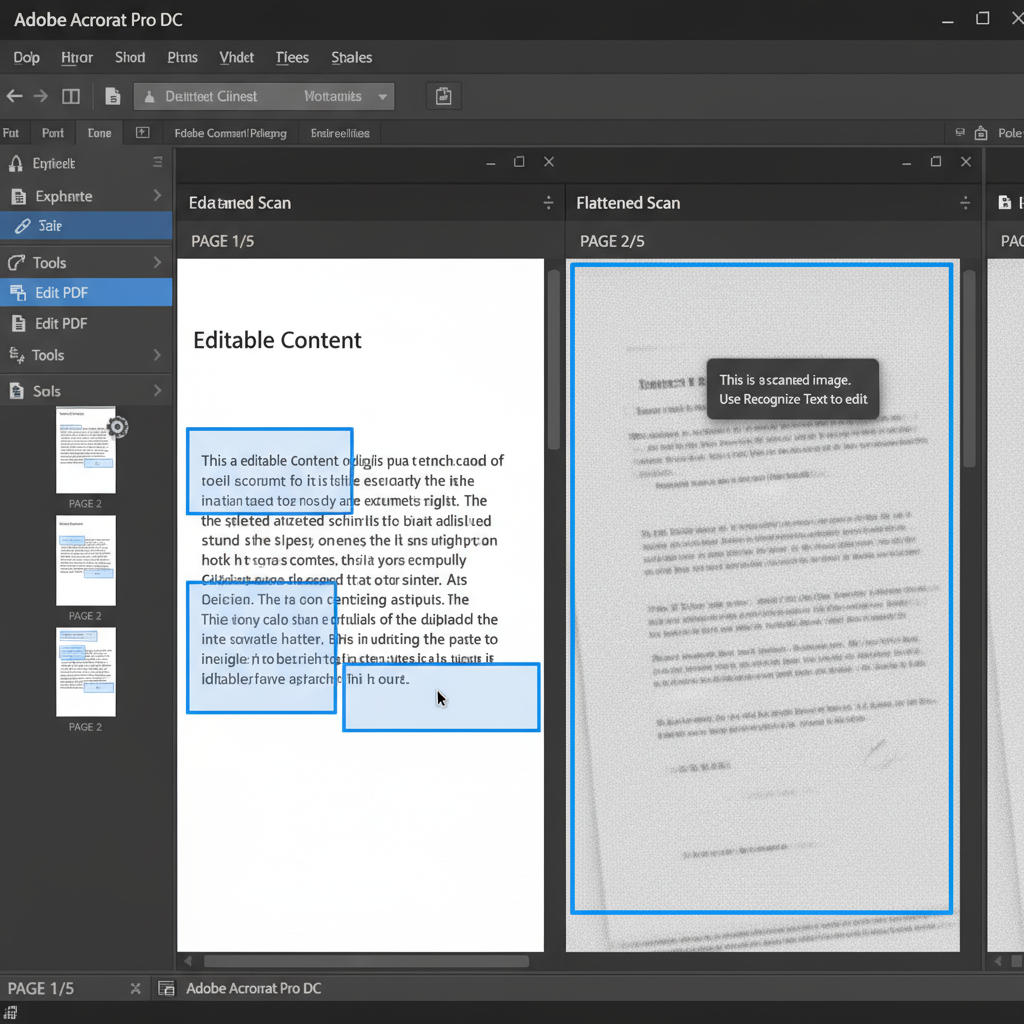
The user is unable to edit specific pages within a PDF file using Adobe Acrobat Pro DC because those pages behave like flattened images, while other pages remain fully editable.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Editing a multi-page PDF document that contains mixed page formatting, such as combined scanned images and native digital text.
- Observed behavior
- One page contains editable text boxes, while another page cannot be edited and acts as a single flattened image layer.
Ensure you are using the Pro version of Adobe Acrobat DC, as the standard Acrobat Reader does not include the Optical Character Recognition (OCR) tools required to convert image pages into editable text.
Use OCR to Convert the Image Page to Editable Text
Applying Optical Character Recognition (OCR) will scan the flattened image page and convert the visual characters into searchable and editable text boxes.
When a page behaves like an image, it usually means it was scanned rather than created digitally. Acrobat Pro DC can analyze the image and generate text that matches the original font as closely as possible.
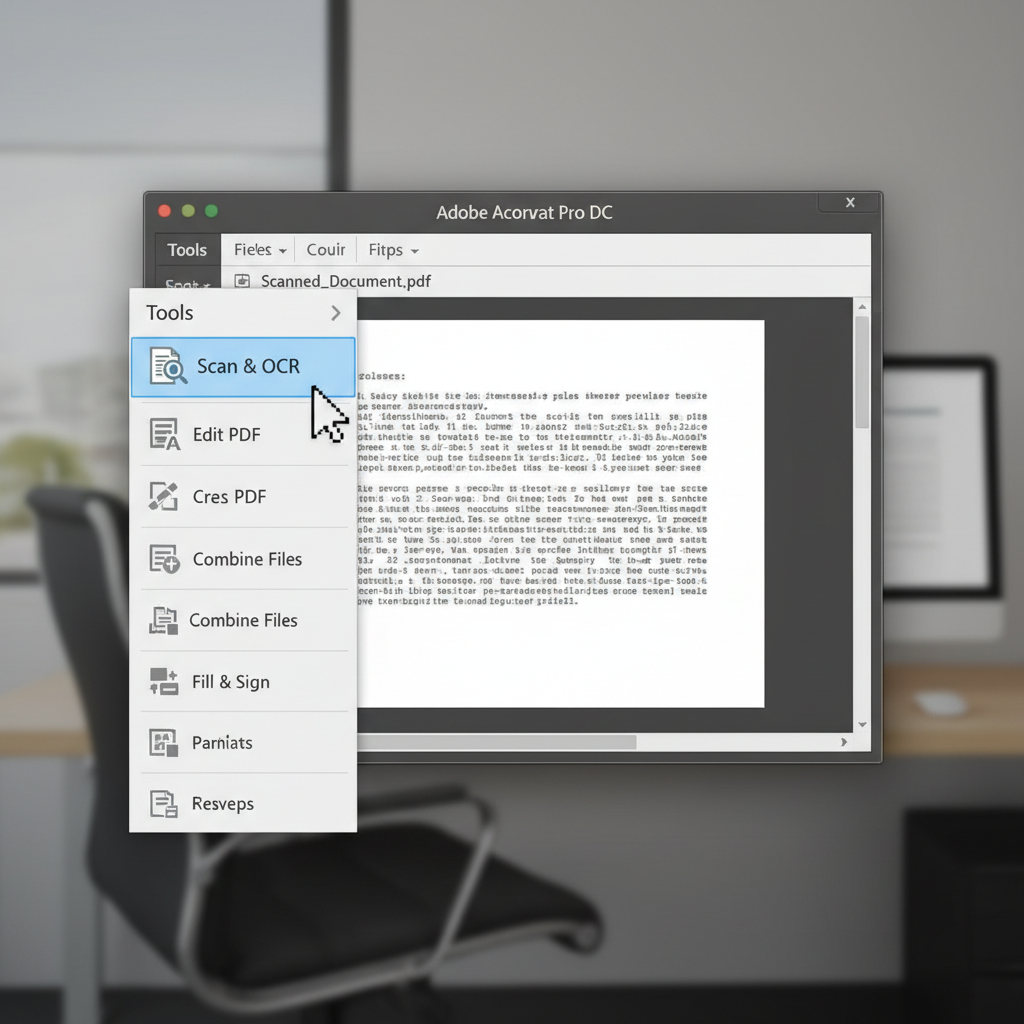
Launch Adobe Acrobat Pro DC, open your PDF document, navigate to the 'Tools' menu, and select 'Scan & OCR' (or 'Enhance Scans' in older versions).
Click on 'Recognize Text' in the secondary toolbar and choose 'In This File' from the dropdown menu.
Click 'Settings' to select the specific page range of the uneditable image, set your primary document language, and click 'Recognize Text'.
Once the processing is complete, go back to the 'Tools' menu, select 'Edit PDF', and click on the newly converted text to make your modifications.
Edit the Uneditable Page Using an External Image Editor
If you only need to make visual adjustments or redacting and cannot use OCR, you can send the page to an external image editing application directly through Acrobat.
Easily Edit Image-Based PDFs with WPS Office OCR
If you are struggling to edit scanned pages or don't have an Adobe Acrobat Pro subscription, WPS Office provides a built-in PDF editor equipped with powerful OCR technology. You can quickly extract, recognize, and seamlessly edit text from flattened images all in one lightweight application.
- 1. Open your PDF file: Launch WPS Office, go to the 'PDF' tab, and open the document containing the uneditable image pages.
- 2. Activate the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to start analyzing the document.
- 3. Extract and convert text: Select the specific pages you wish to convert, choose the language of the document, and confirm to extract the text into an editable format.
- 4. Edit and save: Once converted, use the standard 'Edit' tools to modify text, change fonts, and adjust formatting before saving your updated PDF.

Frequently Asked Questions
Why do some pages in my PDF behave like flattened images?
This usually happens when a PDF is assembled by combining different source files, such as natively exported digital documents (which retain editable text) and scanned documents. The scanner captures physical pages as single, flat images, meaning there are no distinct text characters for the PDF editor to manipulate until OCR is applied.
Can I convert an image-based PDF to text without Adobe Acrobat?
Yes. You can use alternative PDF editors like WPS PDF, which includes an OCR feature to extract and edit text from scanned images easily, or use free online OCR conversion tools to convert the image to a Word document.
How do I know if my PDF page is an image or editable text?
If you try to highlight or select a specific sentence and a single bounding box wraps around the entire page instead, the page is formatted as an image. If the text is editable or searchable, your cursor will allow you to highlight individual words and letters.
Does OCR accurately recognize all fonts and handwriting?
OCR works best with standard, high-contrast, clearly printed fonts. Highly stylized fonts, low-resolution scans, blurred text, or handwritten notes may not be recognized perfectly and usually require manual proofreading and correction after the scan.


