

How to Fix Unusable Excel Files After Exporting Data from PDF

Question details
Users need to extract information from PDF documents into Excel spreadsheets without losing formatting or data integrity.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Exporting data from various types of PDFs, including interactive fillable forms, regular text PDFs, and scanned image PDFs, into an Excel spreadsheet.
- Observed behavior
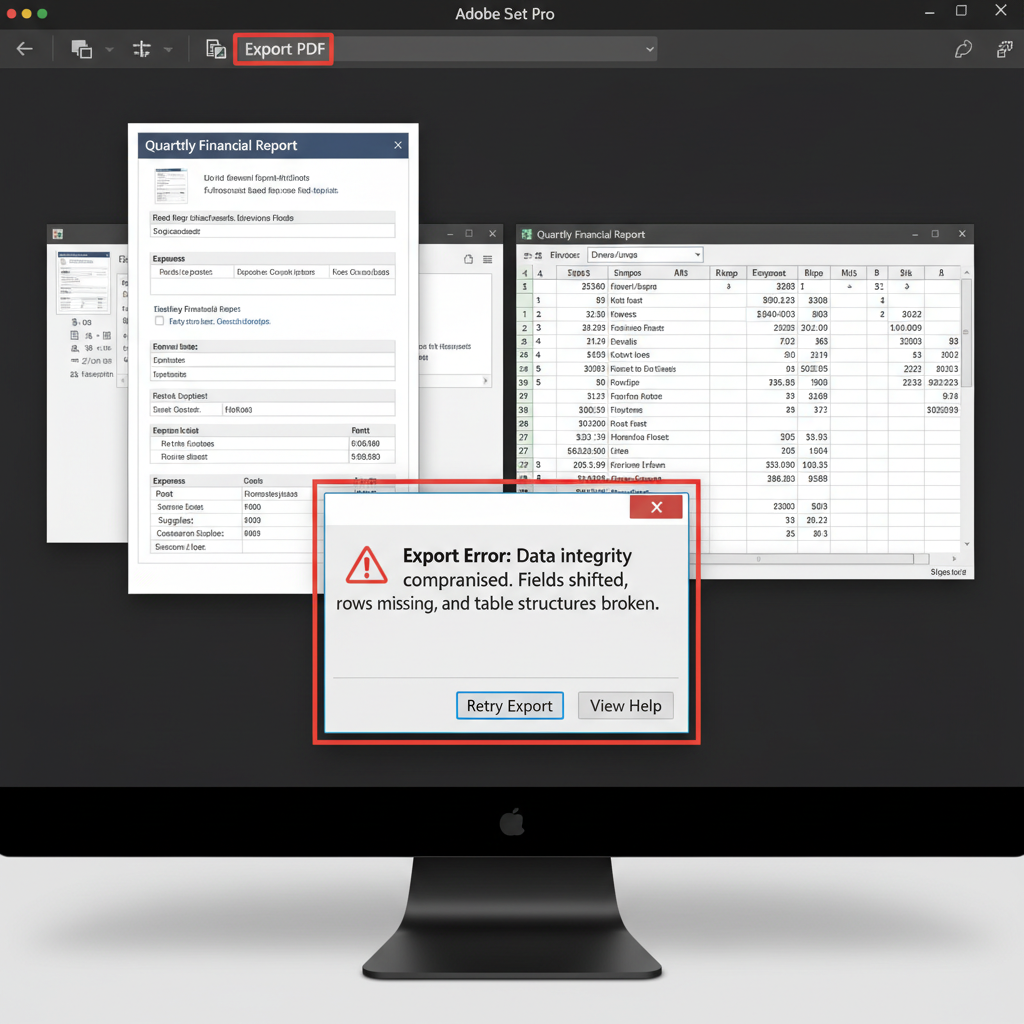
- Directly exporting the PDF to Excel produces shifted fields, missing rows, broken table structures, and unusable data layouts.
Determine whether your PDF is a fillable interactive form, a standard text document, or a scanned image, as each type requires a completely different extraction method for clean Excel data.
Export Form Data Directly as XML, XFDF, FDF, or TXT
If you are working with an interactive fillable PDF form, extracting the raw background data instead of converting the visual layout prevents shifted fields and alignment issues.
PDF forms store entered data independently from the visual document layout. By extracting just this data layer using Adobe Acrobat Pro, you bypass the visual conversion process that typically causes Excel cell misalignment.
Open your interactive fillable PDF file in Adobe Acrobat Pro.
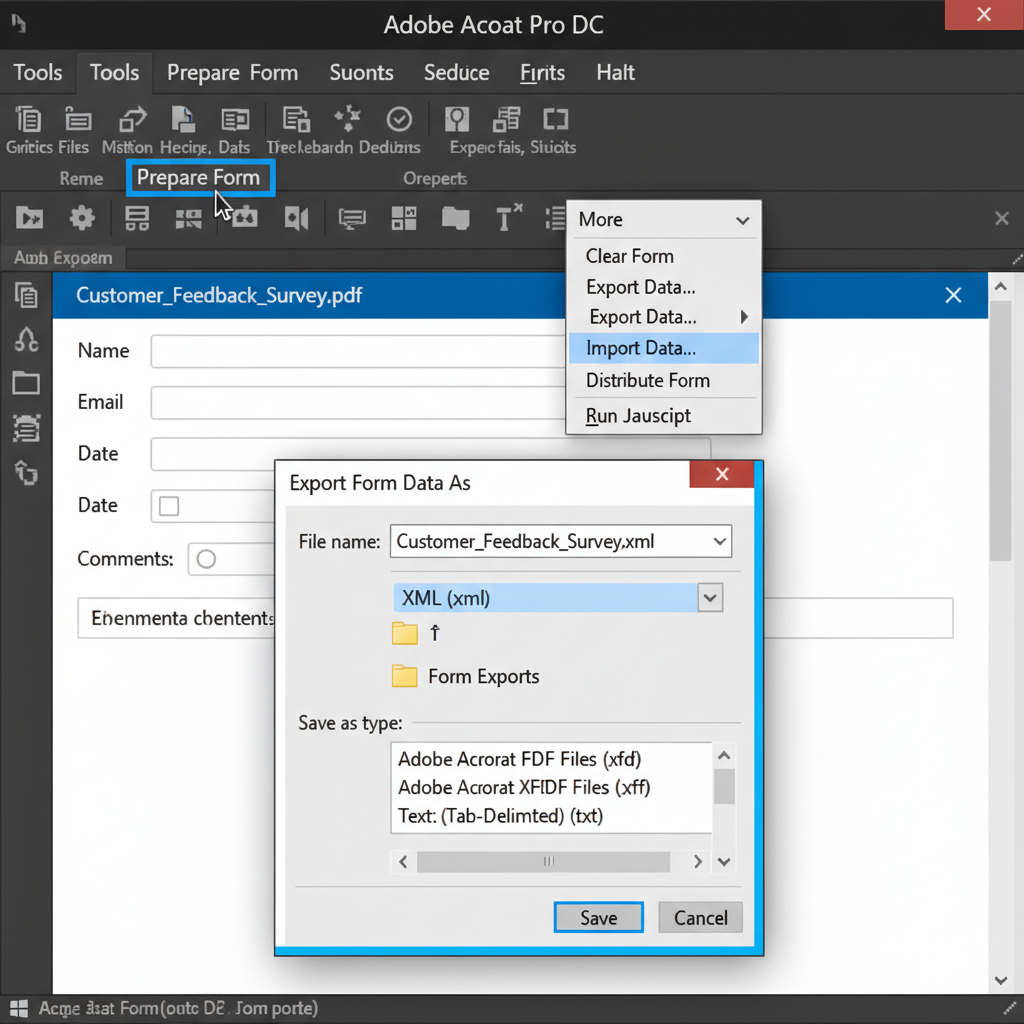
Navigate to the 'Tools' menu at the top and click on 'Prepare form'.
In the right-hand pane, click on 'More' and select 'Export Data' from the dropdown menu.
In the Export Form Data As dialog box, choose a raw data format such as XML, XFDF, FDF, or TXT. Choose a save location and click 'Save'.
Open Microsoft Excel, navigate to the 'Data' tab, and use the 'Get Data' feature to import the saved XML or TXT file directly into clean spreadsheet rows.
Convert Text and Scanned PDFs via OCR and CSV
For standard text PDFs or scanned image documents with complex visual layouts, use Optical Character Recognition (OCR) and extract to an intermediary CSV format.
Flawlessly Convert PDFs to Excel with WPS Office
Avoid shifted columns and broken tables by using the advanced PDF to Excel converter in WPS Office. It intelligently recognizes table structures and features powerful built-in OCR for scanned documents, ensuring your data is ready to use immediately without manual cleanup.
- 1. Open Your PDF: Launch WPS Office and open the PDF document you want to extract data from.
- 2. Select PDF to Excel: Navigate to the 'Tools' tab on the top ribbon and click on the 'PDF to Excel' icon.
- 3. Configure Settings: Choose your desired page range, and if the document is scanned, ensure the OCR language is correctly set.
- 4. Convert and Save: Click 'Convert'. WPS Office will instantly process the file and open a cleanly formatted spreadsheet that is fully compatible with Microsoft Excel.

Frequently Asked Questions
Why do my columns and rows get shifted when I convert a PDF to Excel?
PDFs are essentially digital prints designed to lock visual layouts, not underlying spreadsheet data structures. When converting to Excel, standard tools try to guess column and row borders based on visual spacing, which frequently causes merged cells, shifted columns, or lost data in documents with complex layouts.
Can I extract table data from a scanned PDF into an Excel file?
Yes, but standard extraction will not work because the PDF is just an image of text. You must use a PDF tool equipped with Optical Character Recognition (OCR) to convert the visual image into machine-readable text before exporting it to an Excel format.
How do I import FDF, XML, or TXT form data into an Excel spreadsheet?
After exporting your PDF form data into an XML, CSV, or TXT file, open Microsoft Excel. Go to the 'Data' tab on the ribbon and click 'Get Data' or 'From Text/CSV'. Follow the import wizard to accurately map the raw data into proper spreadsheet rows and columns.


