



Fix OCR and Table Formatting Issues When Exporting PDF to Excel

Question details
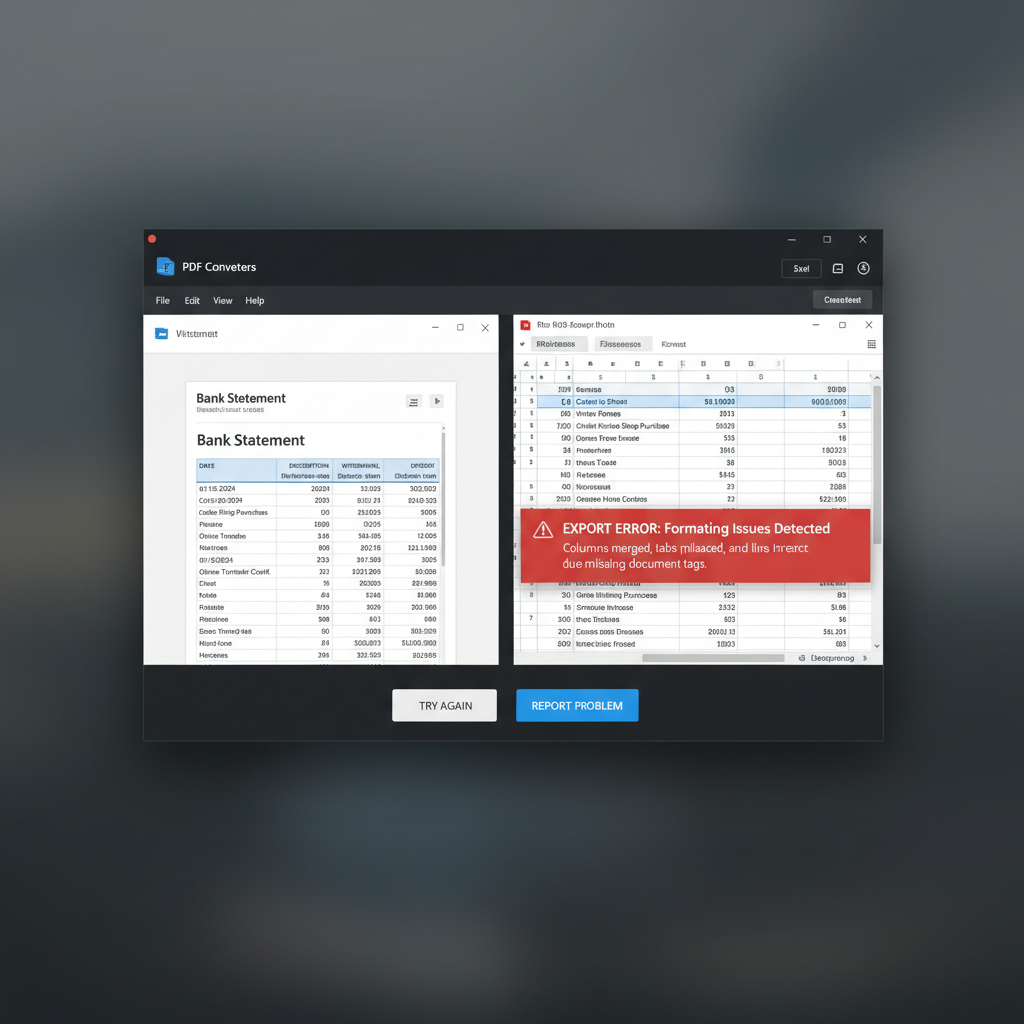
Users experience formatting errors such as merged columns, misplaced tabs, and incorrect line breaks when exporting PDF tables to Excel or CSV formats.
- Product
- PDF Converters
- Device & OS
- not provided
- Scenario
- Exporting tabular data such as bank statements from a PDF document to a spreadsheet for financial tracking or data analysis.
- Observed behavior
- The resulting Excel or CSV files lose their correct table structure, misaligning rows and columns due to missing document tags or poor PDF creation methods.
Verify if your PDF is a scanned image or a text-based document, as scanned PDFs require Optical Character Recognition (OCR) before table formatting can be analyzed and extracted.
Verify PDF Document Properties and Tagging
Check the PDF's creation properties to understand if it contains the necessary structural tags for accurate Excel conversion.
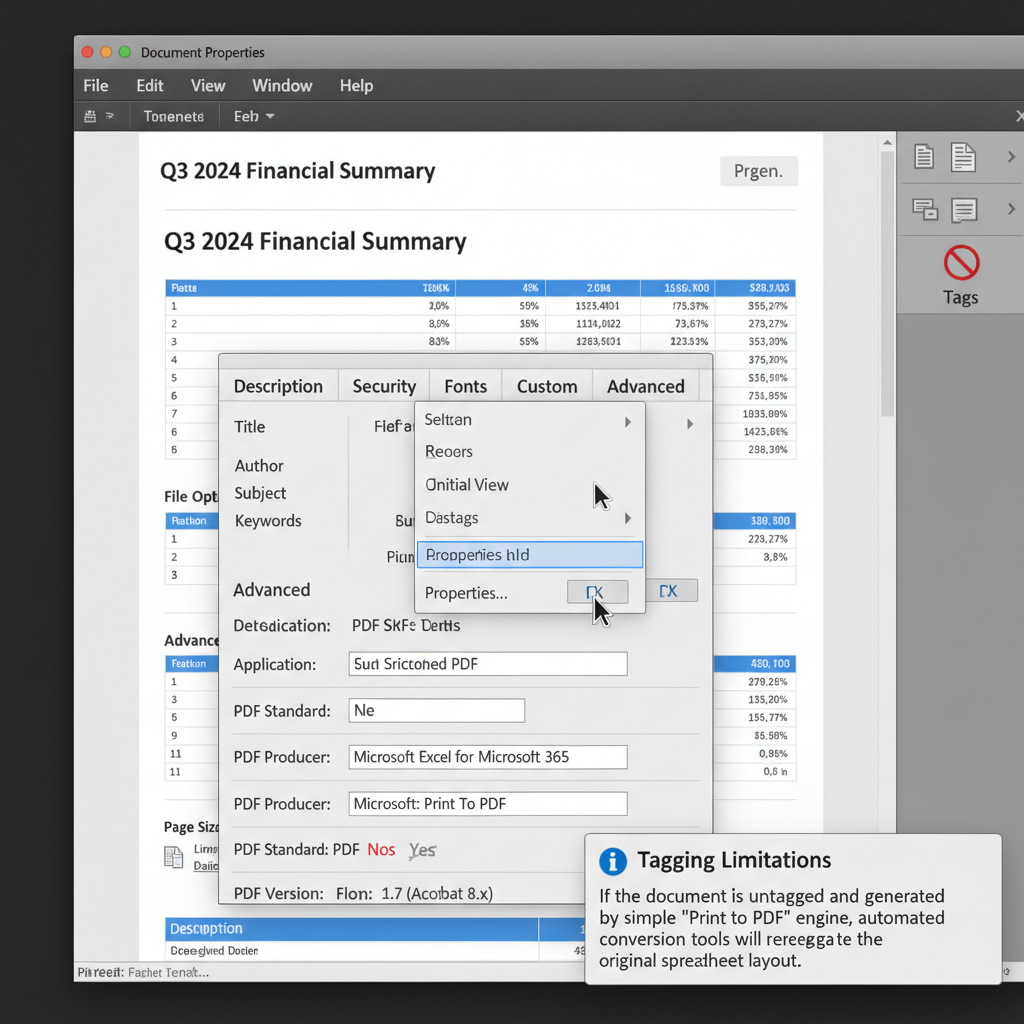
Conversion accuracy relies heavily on how the original PDF was created. If the source application did not include proper structural table tags, converters cannot determine where columns and rows should split.
Open the problematic PDF file in your PDF reader and navigate to 'File' in the top menu, then select 'Properties'.
Navigate to the 'Description' tab within the Properties window. Look for the 'Application' and 'PDF Producer' fields to identify the software used to generate the document.
Check if the document properties mention that it is a 'Tagged PDF'. If it is not tagged, complex table layouts are highly likely to convert with merged or misaligned columns.
Request or Recreate a Properly Structured File
Obtain a better source file by either requesting a native spreadsheet format or re-exporting the PDF with structural tags enabled.
Convert PDF to Excel Accurately with WPS Office
WPS Office features a powerful built-in PDF to Excel converter equipped with smart table recognition and OCR technology. It accurately detects rows, columns, and data structures, ensuring your bank statements and tables are exported to Excel with precise formatting.
- 1. Open the PDF: Launch WPS Office and open the PDF file you need to convert into a spreadsheet.
- 2. Access Conversion Tools: Navigate to the 'Tools' tab on the top ribbon and click on the 'PDF to Excel' button.
- 3. Configure Settings: Select your desired page range and output language. If the PDF is scanned, ensure the OCR option is enabled to extract the text.
- 4. Convert and Save: Click 'Convert' to process the document. Once finished, WPS Office will automatically open the perfectly structured .xlsx file ready for data analysis.
Frequently Asked Questions
Why do my converted PDF tables merge into a single column in Excel?
This happens when the original PDF lacks hidden structural 'tags'. PDF converters rely on these tags to know where a column ends and a new one begins. Without them, the software often misinterprets the spacing and groups all the text into a single block.
How can I tell if a PDF has proper table formatting before converting?
You can check the document's metadata by opening it and going to File > Properties. Look under the Description tab for the PDF Producer and whether it is marked as a 'Tagged PDF'. Tagged PDFs usually convert to Excel much more accurately.
Can OCR technology fix poor table formatting in scanned documents?
OCR (Optical Character Recognition) is essential for reading text from image-based scanned PDFs. While advanced OCR tools can intelligently guess table layouts based on visual borders and spacing, the structural accuracy still depends on the clarity of the scan and the sophistication of the OCR engine used.


