

How to Improve OCR Accuracy and Searchability in PDFs

Question details
The user wants to understand how to improve Optical Character Recognition (OCR) accuracy to ensure scanned PDFs are fully searchable and how to manage batch OCR processing efficiently.
- Product
- Device & OS
- not provided
- Scenario
- Converting scanned documents or image-only PDFs into fully searchable digital files using OCR technology.
- Observed behavior
- OCR accuracy drops when processing low-resolution scans, heavily compressed JPEGs, or damaged microfiche, leading to misidentified characters and failed document searches.
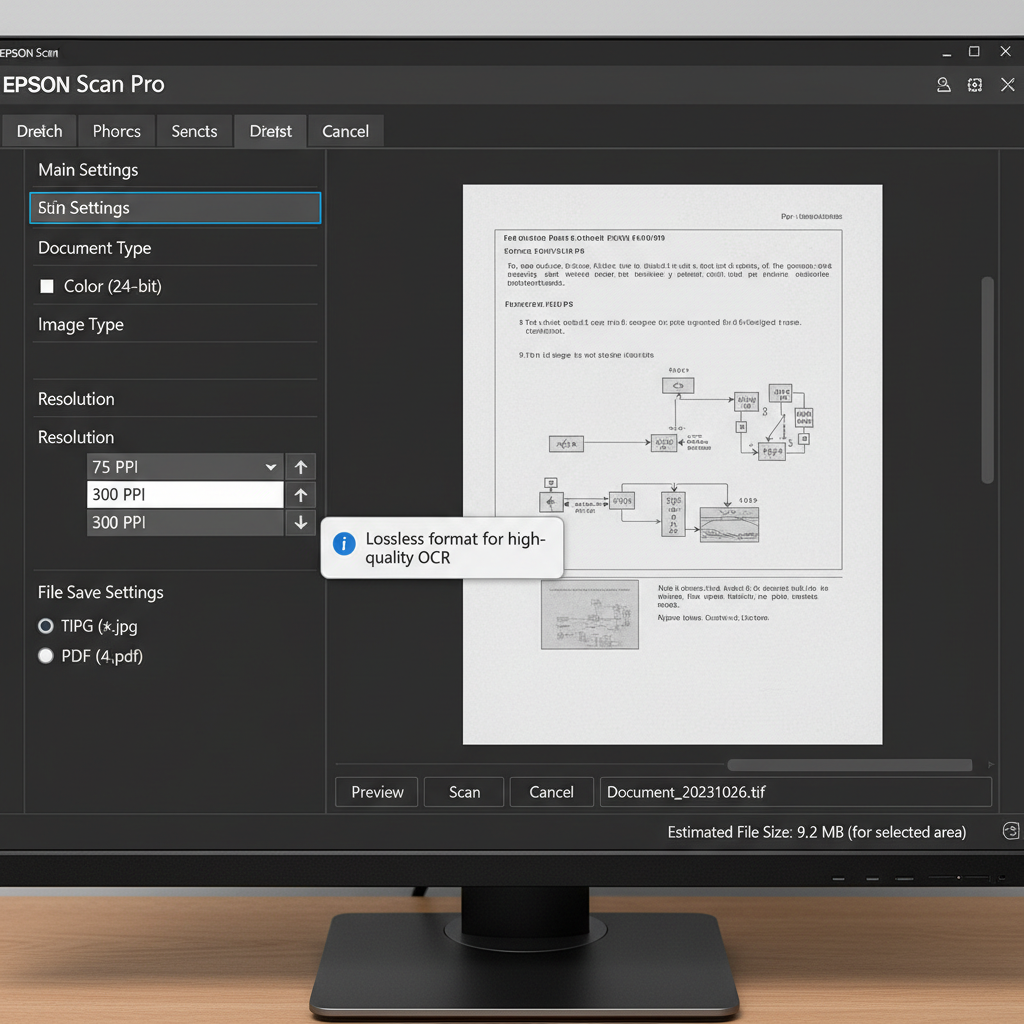
Ensure your source documents are scanned clearly at a minimum of 300 PPI (Pixels Per Inch) and avoid using lossy file formats like highly compressed JPEGs before applying OCR.
Optimize Scanner Settings for High-Quality OCR Output
Set up your scanner correctly to capture documents at the ideal resolution, which provides the OCR engine with the clearest text to recognize.
OCR relies heavily on the quality of the initial scan. Standard JPEGs use lossy compression that introduces artifacts, which can confuse OCR software. Scanning at an adequate resolution without heavy compression dramatically improves text recognition.
Open your scanner manufacturer's software and set the scanning resolution to at least 300 PPI. For documents with very small fonts or complex details, increase this to 600 PPI.
Save your scanned images as TIFF or lossless JPEG 2000 formats instead of standard, highly compressed JPEGs to prevent artifacts that interfere with character recognition.
Process Images with PDF OCR and Manually Proofread
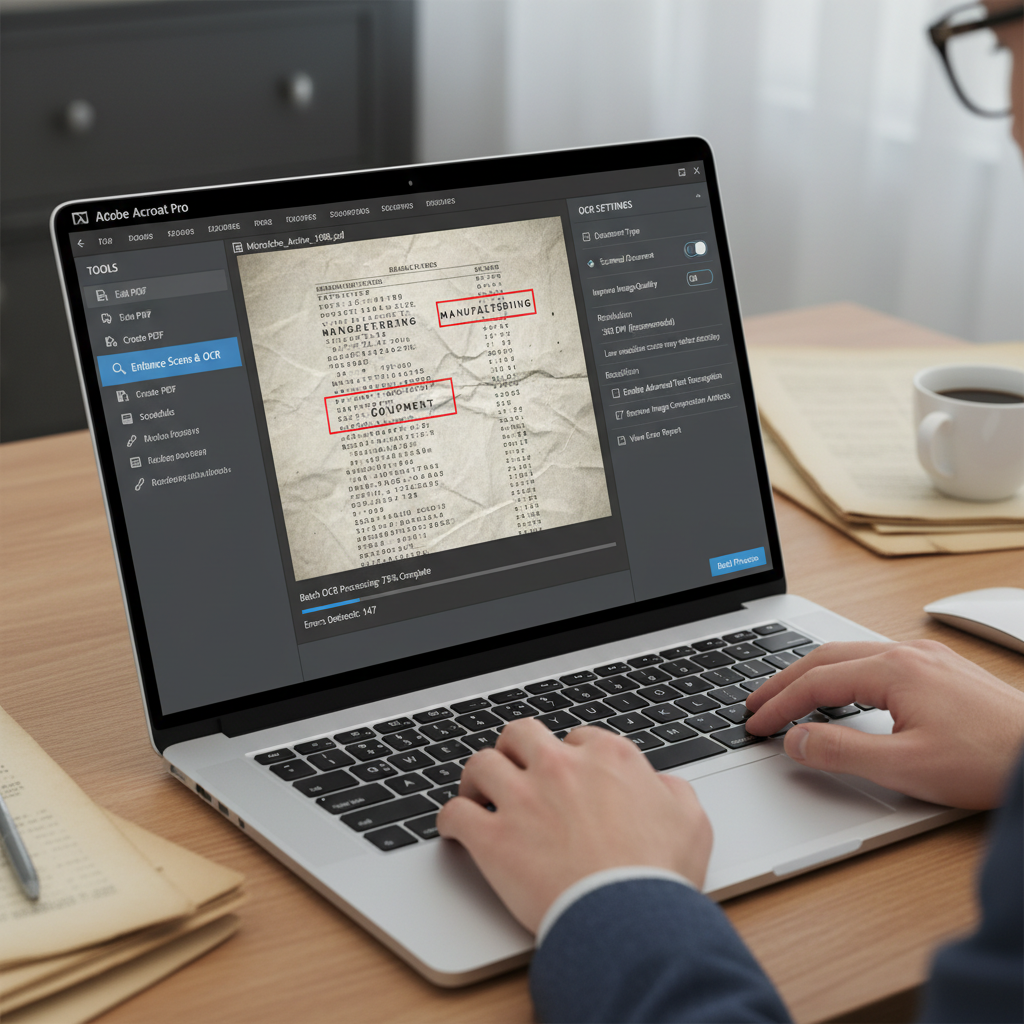
Run the OCR function in your PDF software and manually verify the recognized text to correct inaccuracies.
Use Batch Processing for Multiple Documents
Process large collections of scanned pages efficiently by pointing your PDF software's batch OCR tool to an entire folder.
Achieve High OCR Accuracy with WPS Office
WPS Office features a powerful, built-in OCR engine that quickly and accurately converts scanned images and PDFs into fully searchable and editable text.
- 1. Open the scanned document: Launch WPS Office and open your scanned, image-only PDF file.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Select extraction mode: Choose whether you want to 'Extract text' or 'Convert to editable document', and select the document's language for best accuracy.
- 4. Process and save: Click 'Start OCR' to let WPS Office process the file. Once finished, save the document as a fully searchable PDF or editable Word file.

Frequently Asked Questions
Why can't I find certain words when searching my OCR-processed PDF?
OCR accuracy depends on the original scan quality. If characters are smudged, too close together (like 'ri' being read as 'n'), or if words break across lines, the OCR engine may spell them incorrectly in the invisible text layer, causing exact-match searches to fail.
What is the best scan resolution for OCR processing?
A scanning resolution of 300 PPI (Pixels Per Inch) is generally recommended for optimal OCR results. For documents with very small fonts or complex details, scanning at 600 PPI can further improve character recognition accuracy.
Can I use highly compressed JPEGs for OCR?
It is not recommended. Standard JPEG uses lossy compression, meaning it discards image data to reduce file size. Heavy compression introduces visual artifacts and blurring that significantly interfere with the OCR engine's ability to accurately identify text.
Do I need to manually review documents after applying OCR?
Yes, manual proofreading is highly recommended for important documents. Even the most advanced OCR software can make errors when processing poor-quality scans, faded text, or scratched microfiche images.


