

How to Use OCR for Georgian Language in Adobe Acrobat

Question details
The user wants to use Acrobat's OCR tool to recognize Georgian text on a computer with a Spanish interface.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Applying Optical Character Recognition (OCR) to a scanned document containing Georgian text.
- Observed behavior
- The user is unsure if the Georgian language is natively supported by Acrobat's OCR engine and whether the Spanish interface settings prevent the Georgian language pack from being recognized.
Verify that you have the latest version of Adobe Acrobat installed, as Adobe periodically expands optical character recognition (OCR) language support in major updates.
Verify OCR Language Support in Acrobat Settings
Check the built-in language options within Acrobat's Scan & OCR menu to see if Georgian is natively supported in your installed version.
Adobe Acrobat's OCR engine relies entirely on its internal language database. The OCR capabilities are completely independent of your computer's interface language. Changing your operating system language from Spanish to Georgian will not magically add Georgian to Acrobat's OCR engine if it is not already supported.
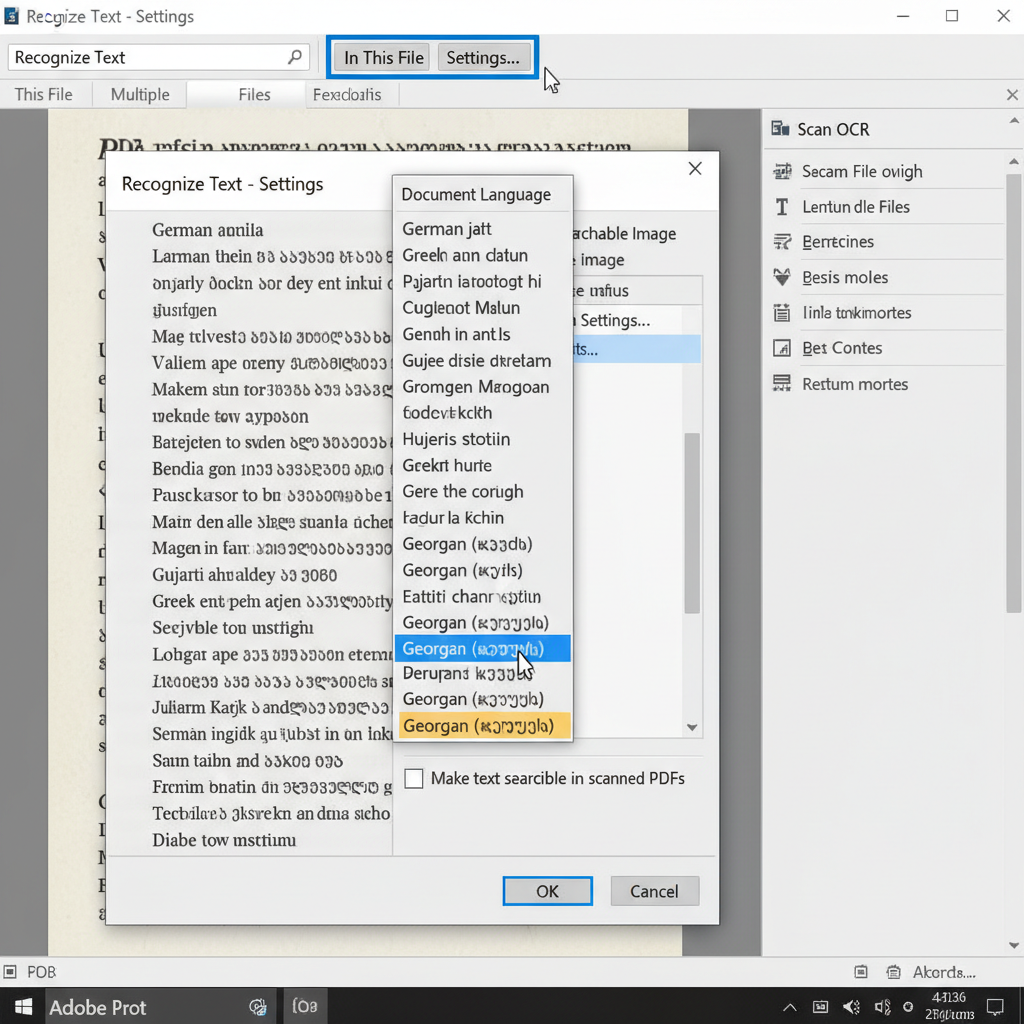
Launch Adobe Acrobat, open your scanned PDF document, and select the 'Scan & OCR' tool from the right-hand tool pane.
Click on 'Recognize Text' in the top toolbar, then select 'In This File' from the dropdown menu.
Click the 'Settings' gear icon. In the dialog box, click the 'Document Language' dropdown menu and scroll through the list to look for Georgian.
If Georgian is listed, select it and click 'Recognize Text'. If it is not listed, Acrobat cannot natively OCR Georgian text and you will need to use a dedicated third-party tool.
Use a Dedicated Third-Party OCR Application
If Acrobat does not support Georgian OCR, use specialized OCR software that fully supports the Georgian alphabet to create your searchable PDF.
Extract Text from Scanned PDFs with WPS Office
WPS Office provides an advanced PDF toolkit featuring highly accurate OCR capabilities. Easily convert your scanned documents into editable Word, Excel, or searchable PDF formats in just a few clicks.
- 1. Open PDF in WPS Office: Launch WPS Office and open your scanned PDF document in the PDF module.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select Output Options: In the OCR panel, specify your document language and choose whether you want to extract the text to a Word document, Excel spreadsheet, or plain text file.
- 4. Extract Text: Click the 'Extract' or 'Convert' button to process the document and instantly access your editable text.

Frequently Asked Questions
Does my computer's display language affect OCR language support?
No. OCR software uses its own specific language databases to recognize characters. Changing your computer's interface language (e.g., from Spanish to English) will not add new recognition languages to your PDF editor.
Can I add new OCR languages to Adobe Acrobat?
Acrobat's supported OCR languages are built into the software installer and updates. You generally cannot manually install a single custom language pack like Georgian unless Adobe officially includes it in a software update.
How do I know if my PDF is already searchable?
Open the PDF and try to highlight or search for specific words using Ctrl+F (or Cmd+F). If you can select individual letters and words smoothly, the document is already searchable and does not require further OCR processing.


