

Recommended Hardware Specifications for High-Performance PDF OCR

Question details
The user is looking for the optimal computer hardware specifications, specifically regarding processor type, RAM, and graphics memory, to ensure fast and efficient OCR processing for PDF files.
- Product
- PDF OCR Processing
- Device & OS
- not provided
- Scenario
- Setting up or evaluating a workstation designed for intensive Optical Character Recognition (OCR) tasks on PDF documents.
- Observed behavior
- Seeking clarification on whether an Intel i5 or i7 is necessary, how hyper-threading impacts performance, and the minimum baseline for system RAM and video memory.
Before investing in hardware upgrades, ensure your PDF software is updated to the latest version, as newer releases often contain significant performance optimizations for OCR engines.
Hardware Guidelines for Optimal OCR Performance
Follow these recommended hardware baselines to ensure smooth, fast, and stable Optical Character Recognition processing on your workstation.
Optical Character Recognition (OCR) is a resource-intensive process that relies heavily on your computer's processing power and memory. Meeting the minimum hardware requirements prevents system bottlenecks when converting large or high-resolution scanned documents.
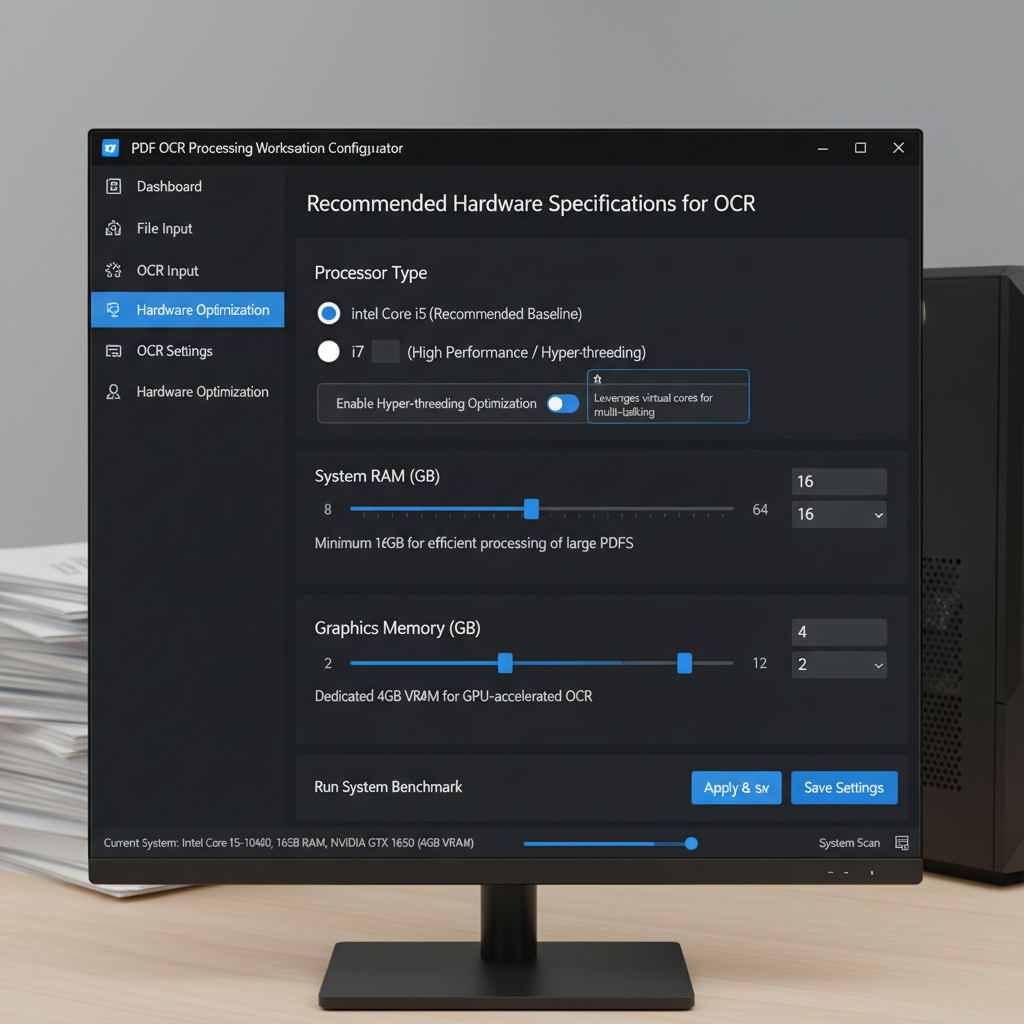
Choose either an Intel Core i5 or i7 processor. Both architectures are fully capable of handling OCR tasks efficiently. The OCR technology supports hyper-threading natively, which is available on both processor tiers and helps manage multiple processing threads simultaneously.
Equip your workstation with a minimum of 8 GB of RAM. This provides a practical baseline to store temporary image data in memory while the OCR engine parses the document text.
Ensure your system has a dedicated graphics card with at least 1 GB of video RAM (VRAM). While OCR is heavily reliant on the CPU, a basic dedicated GPU assists in rendering the document interface and accelerating visual tasks.
Perform Fast and Accurate PDF OCR with WPS Office
WPS Office features a highly optimized, built-in OCR engine that efficiently extracts text from scanned PDFs and images without requiring high-end, expensive hardware.
- 1. Open Your Document: Launch WPS Office and open the scanned PDF or image file you need to process.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon menu and click on the 'OCR' button.
- 3. Choose Extraction Options: Select the specific pages you want to process and choose whether to extract the text to a plain document or convert it directly into a formatted Word/Excel file.
- 4. Start Processing: Click 'Extract Now'. WPS Office will quickly analyze the document and provide editable text, operating smoothly even on standard hardware setups.

Frequently Asked Questions
Does OCR rely more on the CPU or RAM?
OCR is primarily a CPU-intensive task, meaning a faster multi-core processor (like an Intel i5 or i7) will significantly reduce processing times. However, having sufficient RAM (at least 8GB) is equally crucial to hold the large document data in active memory during extraction.
Do I need a high-end graphics card for PDF OCR?
Generally, no. A basic dedicated graphics card with 1 GB of VRAM is practical for standard rendering and UI responsiveness. High-end GPUs are usually unnecessary unless your specific OCR software heavily utilizes GPU hardware acceleration.
Why is my PDF OCR processing so slow despite having good hardware?
Slow OCR performance can be caused by extremely high-resolution scans (e.g., over 600 DPI), unoptimized PDF software, or other background applications consuming system resources. Try lowering your scanner DPI to 300 for a balance of speed and accuracy, or switch to a more lightweight PDF editor.


