

Why PDF Text Changes from μg to mg When Copied and How to Fix It

Question details
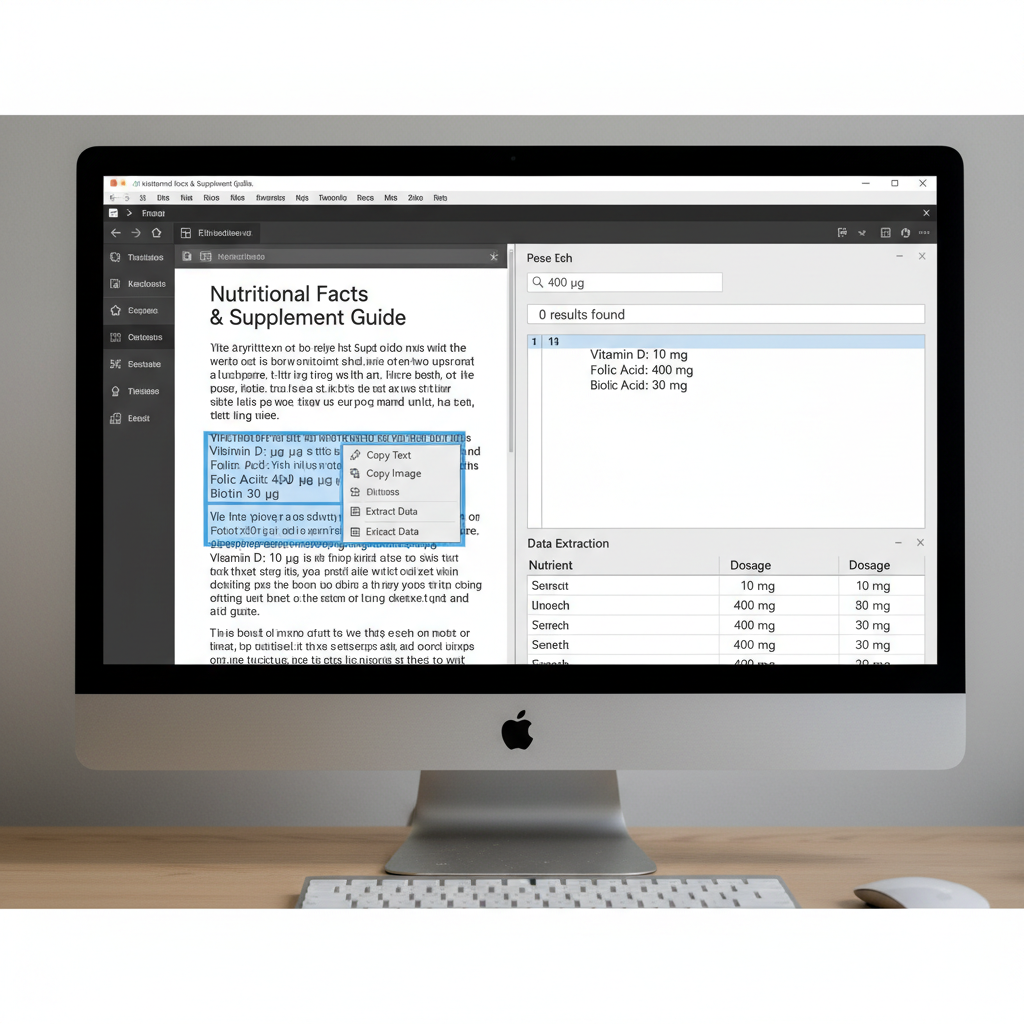
The user is experiencing an issue where copying the microgram symbol (μg) from a PDF results in pasting it as a milligram symbol (mg).
- Product
- PDF Reader/Editor
- Device & OS
- not provided
- Scenario
- Copying text or performing data extraction from a PDF document containing scientific units.
- Observed behavior
- The microgram symbol (μg) is incorrectly extracted or pasted as a milligram symbol (mg), leading to inaccurate search results and corrupted data extraction.
Before troubleshooting the PDF file, try pasting the copied text into a plain text editor like Notepad to ensure it is not an auto-correct feature of your word processor automatically changing 'μg' to 'mg'.
Use Optical Character Recognition (OCR) to Extract Text
Since the hidden text layer of the PDF contains incorrect character mapping, using an OCR tool bypasses the underlying code and extracts the text exactly as it visually appears on the page.
This issue typically arises because the PDF was created with a non-standard font encoding where the character code for 'μ' is mapped to 'm' in the document's internal dictionary. OCR reads the visual shape of the characters rather than the underlying embedded text data.
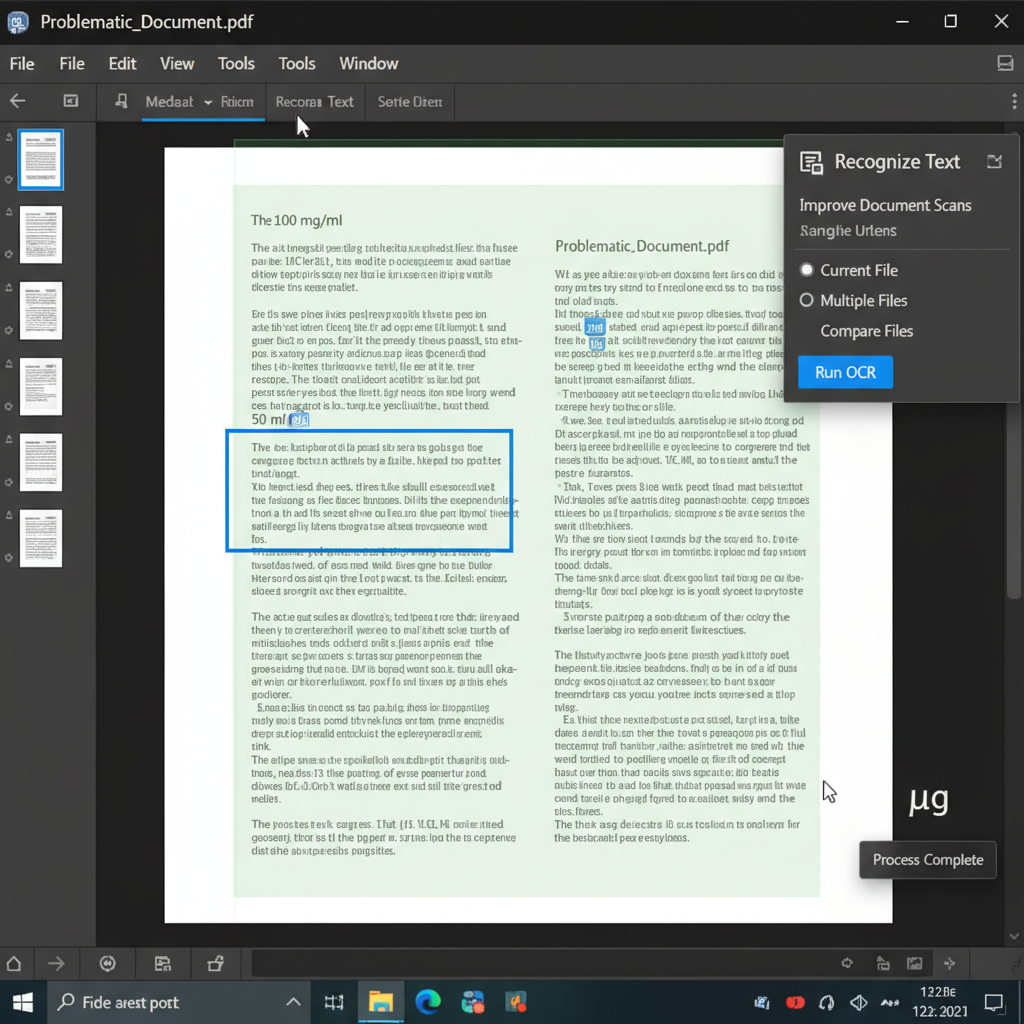
Launch your preferred PDF editor (such as WPS PDF or Adobe Acrobat Pro) and open the problematic document.
Navigate to the 'Tools' menu and select 'OCR' or 'Recognize Text'. Choose the option to convert the document into searchable and editable text.
Once the OCR process is complete, highlight the scientific units again, copy them, and paste them into your destination document. The 'μg' symbol should now paste correctly.
Request a Properly Encoded PDF from the Creator
The most permanent fix is for the original document author to re-export the file with properly embedded fonts and standard Unicode mapping.
Report the Rendering Issue to Adobe
If you suspect the issue is caused by a specific bug in Adobe Acrobat's handling of certain font types, you can report it directly to their engineering team.
Extract Text Accurately with WPS PDF OCR
Bypass hidden font-encoding errors and faulty character mappings using the powerful OCR engine built directly into WPS Office. Extract scientific symbols exactly as they appear on your screen.
- 1. Install WPS Office: Download and install WPS Office for free from the official website.
- 2. Open the PDF File: Launch WPS PDF and open the document containing the problematic microgram symbols.
- 3. Select the OCR Tool: Go to the 'Tools' tab on the top ribbon and click on 'OCR' to initiate the text recognition feature.
- 4. Extract the Text: Choose the area containing the text, let the OCR process complete, and simply copy the perfectly recognized 'μg' text to your clipboard.

Frequently Asked Questions
Why do other symbols also copy incorrectly from my PDF?
This happens when a PDF is created without properly embedding the fonts or standard Unicode character mappings. The system does not know what the visual character actually represents, so it substitutes it with an incorrect letter or a completely different symbol.
Can I fix the font encoding directly in an existing PDF?
Fixing font encoding within a compiled PDF is highly difficult without specialized preflight software. The most practical approach is either returning to the original source document (like a Word file) to recreate the PDF or using OCR software to extract the visual text.
How do I know if my PDF has embedded fonts?
Open the PDF in your reader, go to 'File' > 'Properties' (or 'Document Properties'), and navigate to the 'Fonts' tab. This tab will list all fonts used in the document and state whether they are 'Embedded' or 'Embedded Subset'.


