

Fix Adobe IFilter Not Searching OCR PDFs in SharePoint

Question details
Users are unable to search the contents of OCR-scanned PDFs and converted Word documents stored in a SharePoint library using the Adobe IFilter.
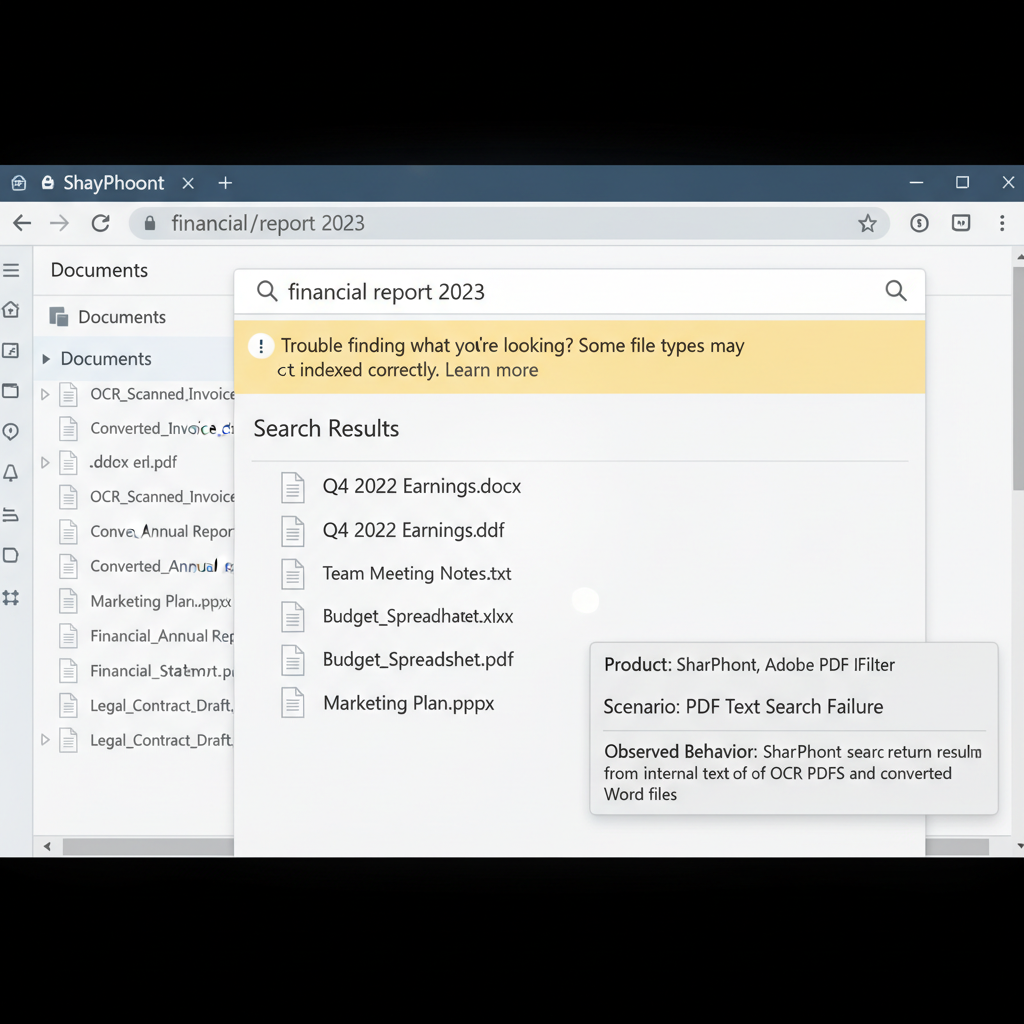
- Product
- SharePoint, Adobe PDF IFilter
- Device & OS
- not provided
- Scenario
- Searching for specific text inside PDF documents stored within a SharePoint document library.
- Observed behavior
- SharePoint search results do not return PDF documents based on their internal text content, indicating that Adobe IFilter is failing to extract text from OCR-scanned PDFs and converted Word files.
Ensure you have SharePoint Farm Administrator privileges to manage search topologies, verify IFilter server configurations, and trigger a full search crawl.
Verify IFilter Installation and Rebuild Search Index
Ensure the correct 64-bit Adobe PDF IFilter is installed on the SharePoint crawling servers and force a full search index rebuild to properly read PDF contents.
SharePoint relies on the Adobe PDF IFilter to extract text from PDF files during the crawling process. If the IFilter is missing, mismatched with the server architecture, or improperly registered, SharePoint will only index the file metadata and ignore the document contents.
Check your SharePoint crawl server to ensure that the 64-bit version of the Adobe PDF IFilter is installed and registered in the system's environment variables.
Navigate to SharePoint Central Administration > Search Service Application > File Types. Confirm that the 'pdf' file extension is listed and enabled.
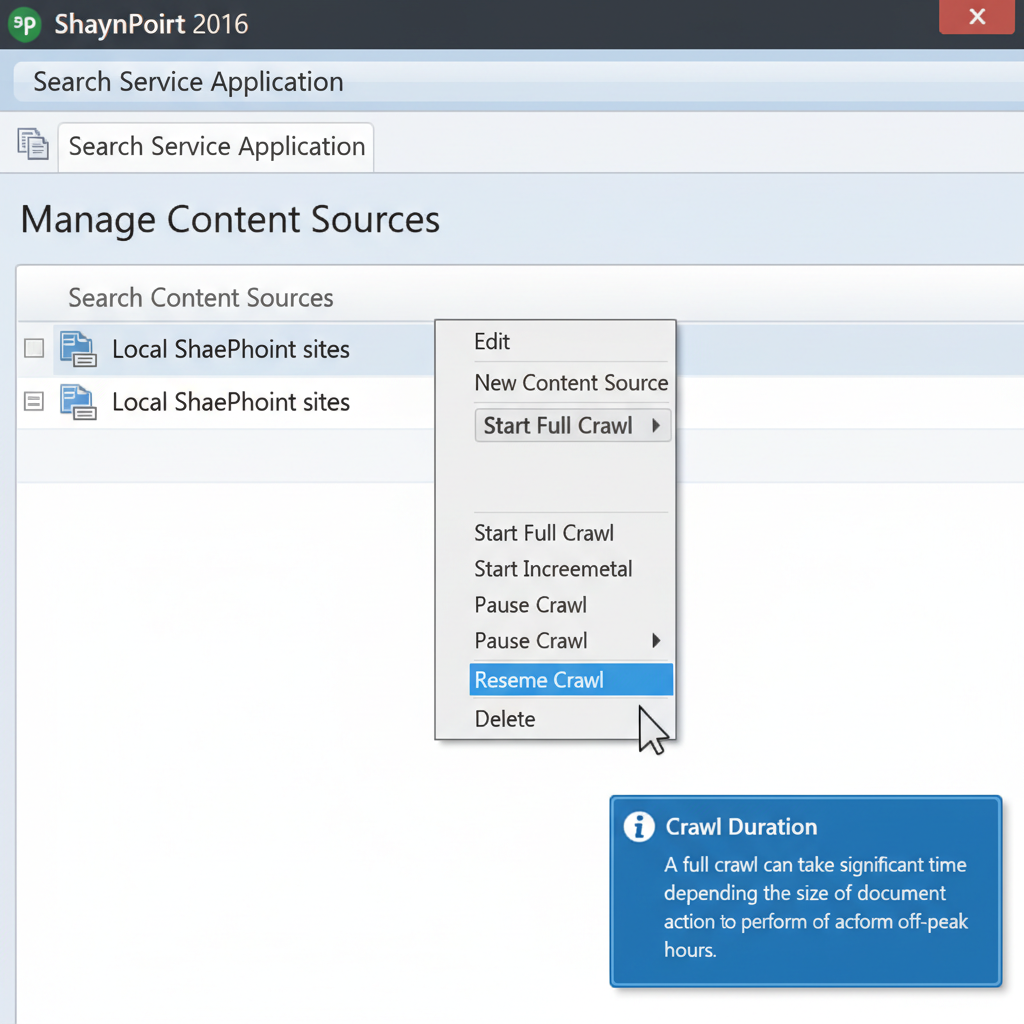
In the Search Service Application, navigate to Content Sources. Hover over your primary content source containing the PDFs, click the dropdown menu, and select 'Start Full Crawl'.
After the crawl finishes, check the Crawl Log for any specific errors or warnings related to your PDF files to ensure the IFilter successfully processed the text.
Validate OCR Text in PDF Documents
Ensure the problematic PDF files actually contain a searchable, invisible text layer rather than just flat scanned images.
Efficiently Manage, OCR, and Convert PDFs with WPS Office
While troubleshooting SharePoint server indexing requires administrative access, you can ensure your files are fully searchable before uploading them. WPS Office provides built-in, highly accurate OCR tools and seamless document conversion. It serves as a lightweight, fully compatible, and free alternative to Microsoft Office.
- 1. Open your PDF in WPS Office: Launch WPS Office and open the scanned PDF document you intend to upload to SharePoint.
- 2. Apply OCR Functionality: Navigate to the 'Tools' tab and select 'OCR' to detect and extract the text from the scanned image pages.
- 3. Save as Searchable PDF: Export or save the newly processed document as a searchable PDF to ensure SharePoint IFilter can index its contents upon upload.

Frequently Asked Questions
Why does SharePoint search ignore the contents of my uploaded PDF files?
SharePoint requires a dedicated PDF IFilter to decode and read the text inside PDF files. If this IFilter is missing, outdated, or misconfigured, the search engine will only index the file's title and metadata, completely bypassing the actual document text.
How do I know if the Adobe IFilter is registered correctly in Windows?
You can verify this in the Windows Registry of your crawling server. Navigate to 'HKEY_LOCAL_MACHINE\SOFTWARE\Microsoft\Shared Tools\Web Server Extensions\15.0\Search\Setup\ContentIndexCommon\Filters\Extension\.pdf' and ensure it points to the correct Adobe IFilter GUID.
Are there alternatives to the Adobe PDF IFilter for SharePoint?
Yes. Many organizations use alternative IFilters, such as the Foxit PDF IFilter or the PDFlib TET Plugin. These alternatives are specifically designed for high-performance enterprise search environments and often resolve persistent indexing issues.


