

How to Fix Overlapping OCR Text After Optimizing Scanned PDFs

Question details
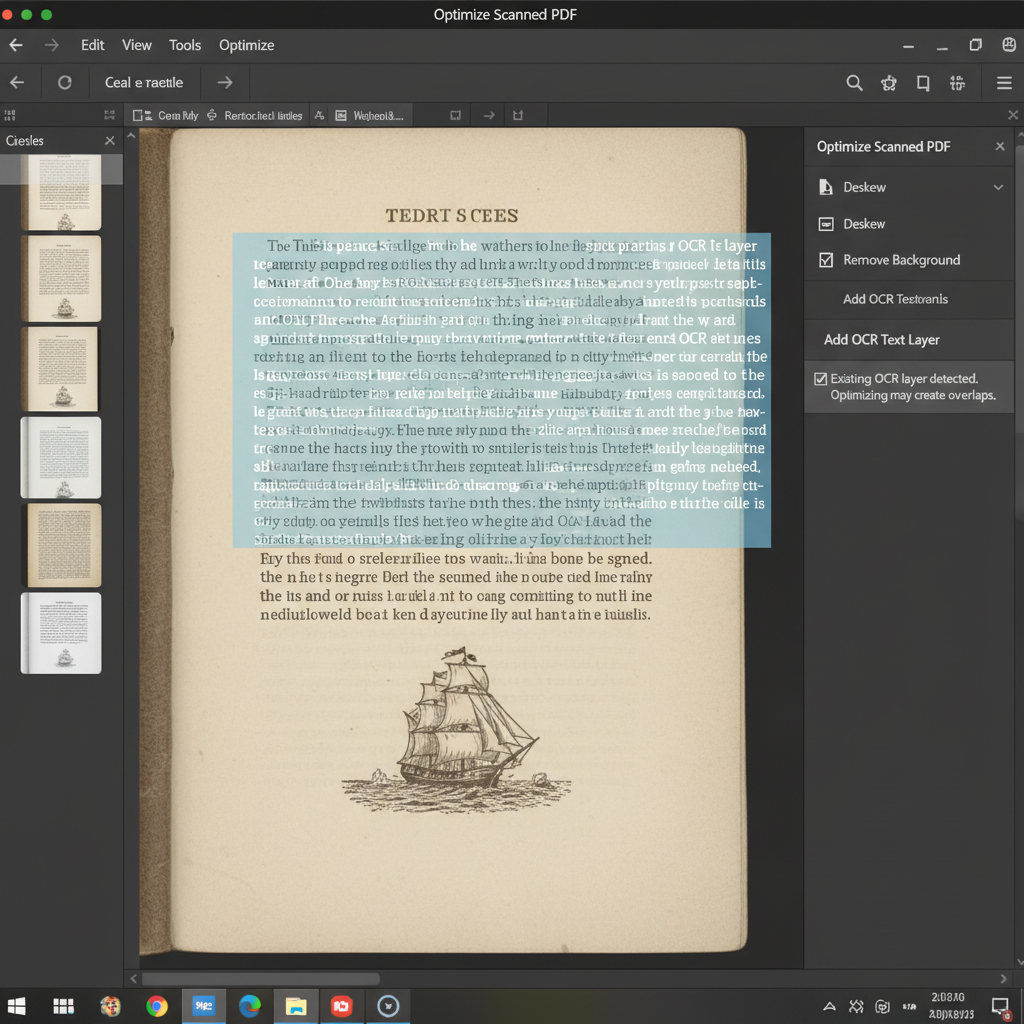
The user experiences overlapping searchable text on top of the original scanned page content when optimizing a scanned book PDF.
- Product
- PDF Editors
- Device & OS
- not provided
- Scenario
- Optimizing a scanned book PDF that already contains an invisible OCR text layer.
- Observed behavior
- Searchable text visibly overlaps and clashes with the original scanned images after the optimization process incorrectly adds a second OCR layer.
Check if your scanned PDF already has a searchable text layer before running any further optimization or OCR processes, as running OCR twice is the primary cause of text overlapping.
Prevent Duplicate OCR During PDF Optimization
Adjust your PDF editor settings to ensure OCR is only run once, avoiding the creation of a duplicate text layer.
Overlapping text occurs when a document that already has an invisible OCR text layer undergoes a second OCR process during PDF optimization. This forces the new text to become misaligned or visible over the original image.
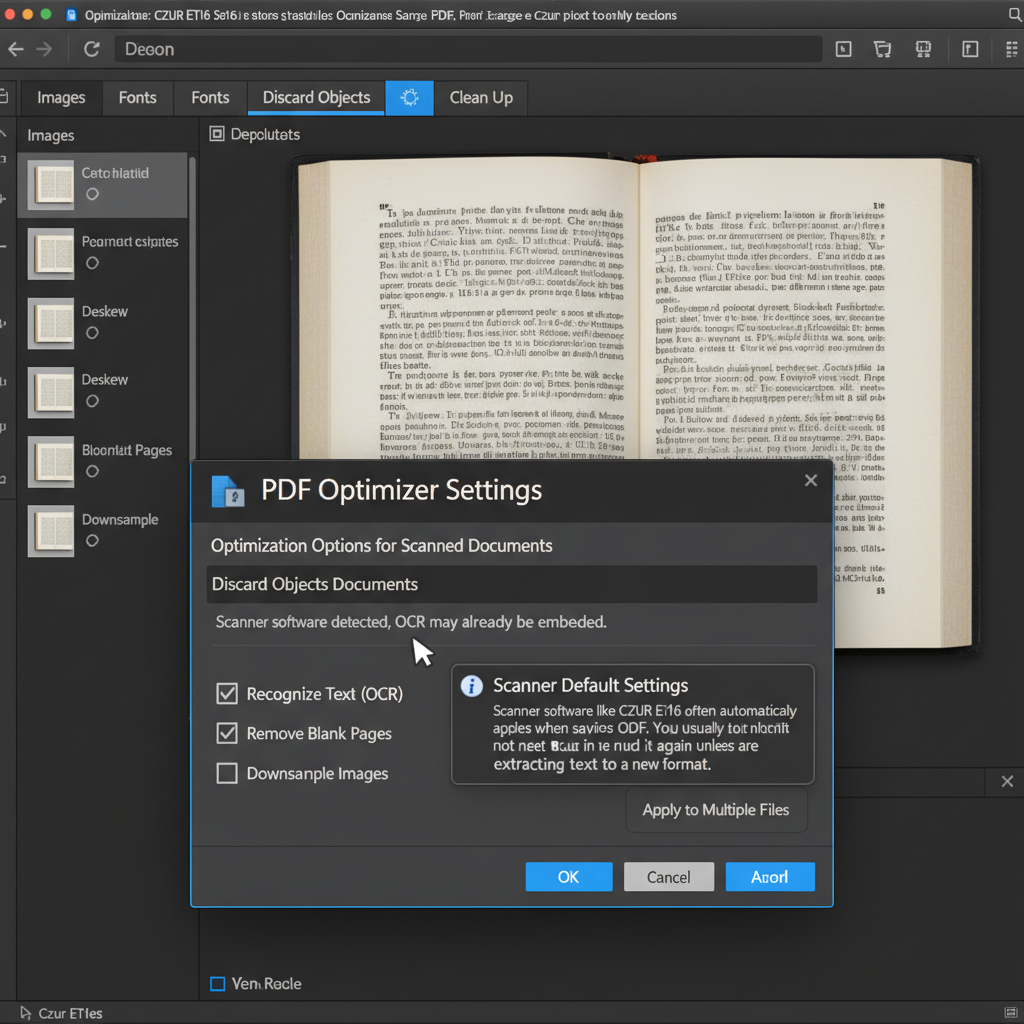
Open the PDF optimization or compression settings in your preferred PDF editing software.
Find the OCR (Optical Character Recognition) or 'Recognize Text' settings within the optimization menu.
Uncheck or disable the option to recognize text if the document already has a searchable text layer from the scanner.
Apply the optimization settings to reduce file size and save the PDF without duplicating the OCR layer.
Recreate PDF from Original Scans
If the file is already corrupted with overlapping text, recreate the PDF from the source images to ensure only one text layer is applied.
Extract and Optimize PDF Text Seamlessly with WPS Office
WPS Office provides advanced OCR technology that accurately recognizes text from scanned documents without creating messy overlapping layers. Easily optimize your PDFs, edit scanned content, and manage file sizes all within a single lightweight application.
- 1. Open Scanned PDF: Launch WPS Office and open your scanned PDF document.
- 2. Navigate to OCR Tools: Go to the 'Tools' tab on the top ribbon and select the 'OCR' feature.
- 3. Extract or Convert: Choose 'Extract Text' to pull clean text without overlapping, or 'Convert to Word' for an easily editable document.
- 4. Save Optimized File: Save your newly processed text or use WPS PDF compression tools to optimize the original file size without re-running OCR.

Frequently Asked Questions
Why does my scanned PDF have overlapping text?
This happens when a PDF that already contains a hidden OCR text layer goes through a second OCR process. The software creates a new text layer, causing the newly generated characters to visibly overlap and clash with the original scanned image.
How can I remove an existing hidden text layer in a PDF?
You can remove hidden text layers by using the 'Sanitize Document' or 'Remove Hidden Information' tools in advanced PDF editors. Alternatively, you can convert the PDF back to image formats (like JPG) and re-combine them into a new PDF.
Can I optimize a PDF file size without running OCR?
Yes, most modern PDF editors allow you to customize optimization settings. Simply uncheck the 'OCR' or 'Recognize Text' option in the compression dialogue before reducing the file size.


