

How to Use OCR for Scanned Files in Google Drive

Question details
The user needs to apply Optical Character Recognition (OCR) to large collections of scanned documents stored in Google Drive to make the files fully searchable.
- Product
- Google Drive
- Device & OS
- not provided
- Scenario
- Organizing and attempting to search through large collections of scanned PDF documents and image files stored in cloud storage.
- Observed behavior
- Scanned files remain as flat images, making it impossible to search for specific text or copy content directly within Google Drive.
Ensure your scanned files are in a supported format like PDF, JPEG, or PNG, and verify that the text in the original document is clear and well-lit for optimal OCR accuracy.
Use Google Drive's Built-in OCR via Google Docs
Convert image-based PDFs or scanned pictures directly into searchable text using Google Docs' native OCR capability.
Google Drive has a built-in feature that can automatically extract text from images and basic PDFs. While it may struggle with highly complex formatting or tables, it is completely free and works excellently for standard text documents.
Log in to your Google Drive account and find the scanned PDF or image file you wish to make searchable.
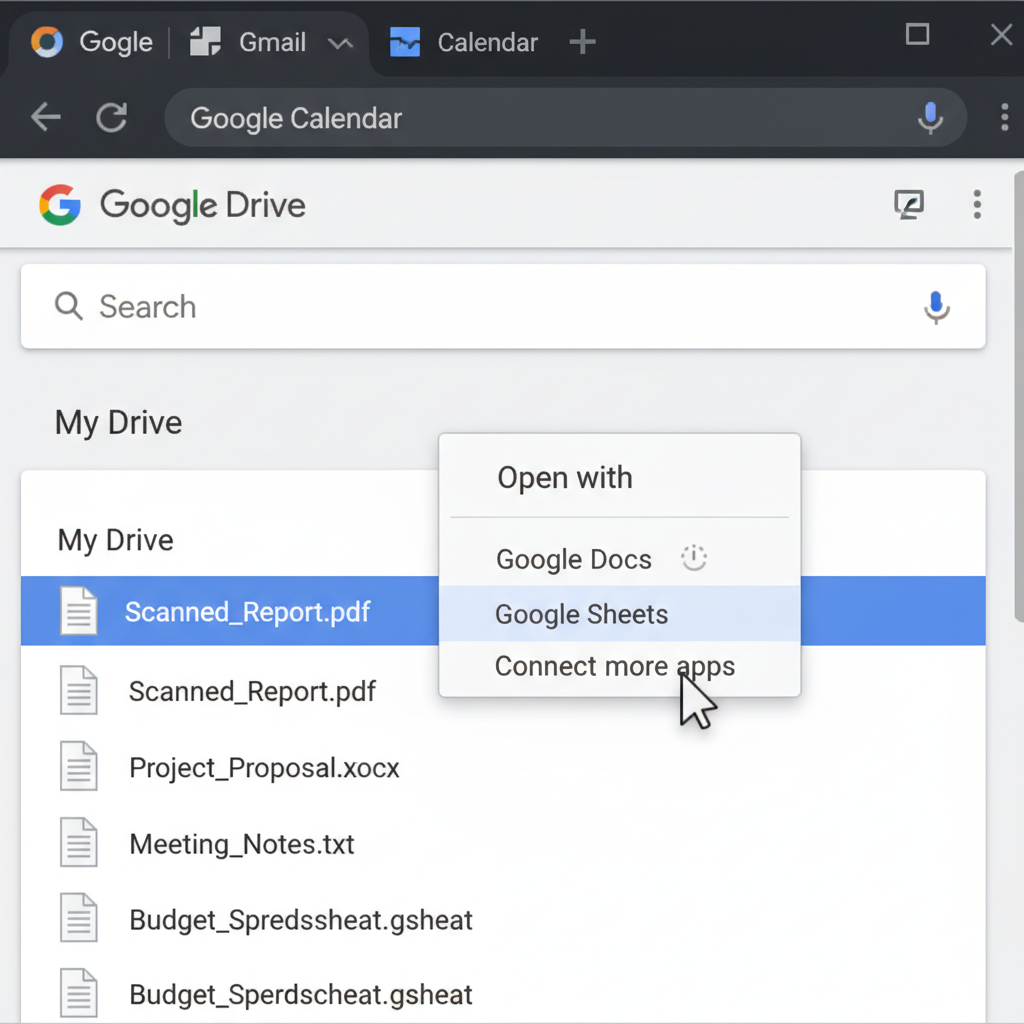
Right-click on the file, hover over the 'Open with' option in the context menu, and select 'Google Docs'. Google Drive will immediately begin processing the document.
A new Google Docs file will open. The original image will be placed at the top of the page, followed by the fully editable and searchable text extracted from the document.
Use Adobe Acrobat Integration for Google Drive
Utilize Adobe Acrobat's connected tools to run OCR on PDFs without losing the original document formatting.
Use WPS Office to Extract and Search Text in Scanned PDFs
WPS Office offers a powerful, desktop-level built-in OCR feature that quickly converts your scanned PDFs and images into fully editable and searchable formats with high accuracy, overcoming cloud storage file size limits.
- 1. Open your scanned document: Launch WPS Office on your computer and open the scanned PDF or image file you downloaded from Google Drive.
- 2. Access the OCR feature: Navigate to the 'Tools' tab on the top ribbon menu and click on the 'OCR' button.
- 3. Select conversion options: Choose whether you want to extract the text into a new Word Document, an Excel spreadsheet, or a plain text file.
- 4. Extract and save: Click 'Extract' to begin the conversion. Once completed, your newly searchable document can be saved and uploaded back to Google Drive.

Frequently Asked Questions
Why is Google Drive not recognizing text in my scanned PDF?
Google Drive's built-in OCR requires high-resolution images and clear text. If your file is blurry, contains complex multi-column layouts, is handwritten, or exceeds a file size of 2MB, the OCR process may fail or produce inaccurate text.
Does Google Drive automatically OCR uploaded PDFs?
Google Drive automatically indexes basic text in uploaded images and simple PDFs to improve searchability in the search bar. However, to actually extract, copy, or edit the text, you must manually open the file using Google Docs.
Can I use OCR on multiple files at once in Google Drive?
No, Google Drive's native 'Open with Google Docs' method only processes one file at a time. For batch OCR processing of multiple scanned documents, you will need dedicated desktop software like WPS Office or Adobe Acrobat Pro.
Is Google Drive OCR free to use?
Yes, the basic OCR functionality through Google Docs is completely free for all Google account users. More advanced, layout-preserving OCR requires paid third-party tools or premium desktop applications.


