

How to Use Acrobat Pro DC OCR Files with Google Classroom and Docs

Question details
The user needs to perform OCR on scanned PDFs using Acrobat Pro DC, export them to editable formats, and upload them for use in Google Classroom or Google Docs.
- Product
- Adobe Acrobat Pro DC / Google Docs
- Device & OS
- not provided
- Scenario
- Extracting and converting text from scanned PDF documents so they can be edited and shared as assignments in Google Classroom.
- Observed behavior
- OCR text recognition quality varies, and document formatting often changes or breaks when exporting to Word or opening the converted files in Google Docs.
Ensure your original scanned documents are of high resolution and free from stains or heavy fading, as scan quality heavily dictates the accuracy of the final OCR text.
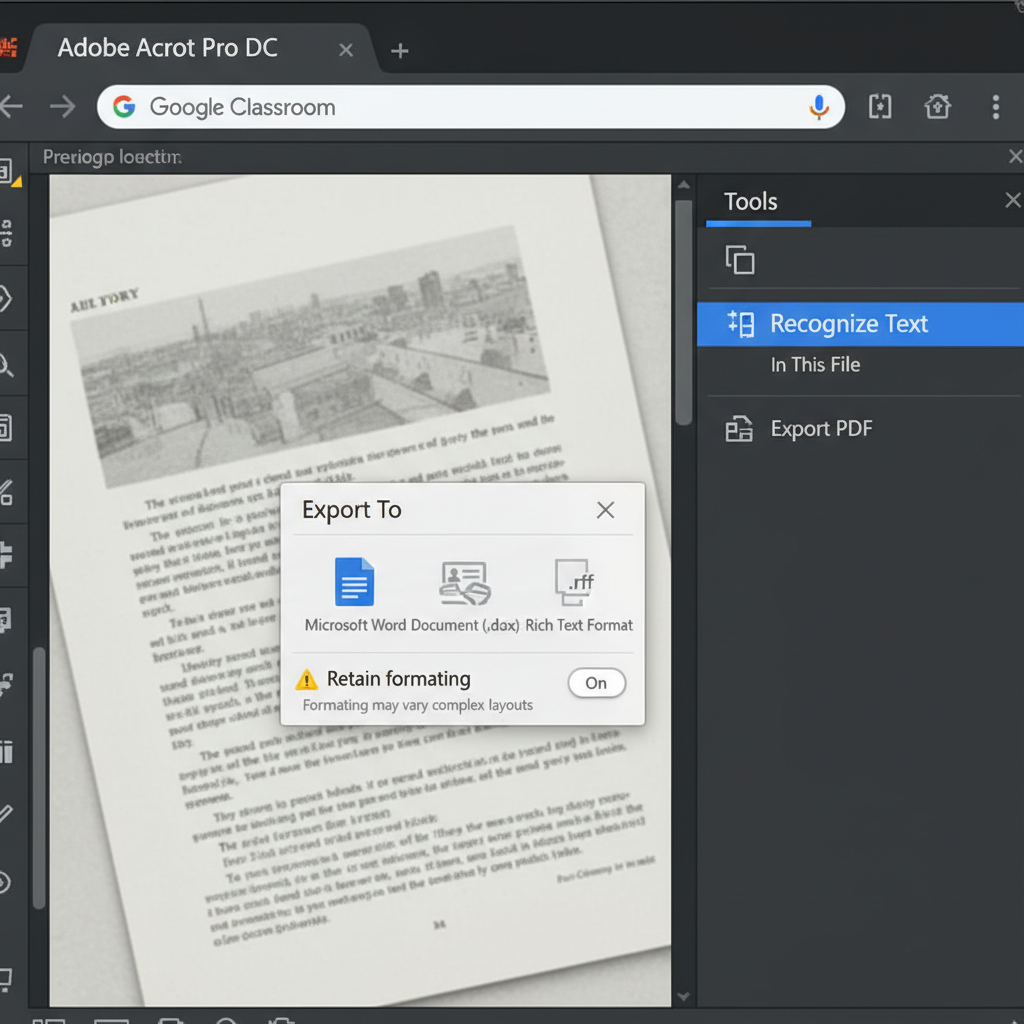
Optimize Scan Quality and Export to DOCX via Acrobat Pro DC
Improve the accuracy of OCR recognition by reviewing the scanned text and exporting the file to an editable Word document before uploading to Google Drive.
Acrobat Pro DC's OCR capabilities depend largely on the source file. Damage, low resolution, and unusual fonts will lower text recognition accuracy. While images are typically preserved during conversion, hyphenated words or complex layouts may require manual formatting adjustments once converted to a word processor.
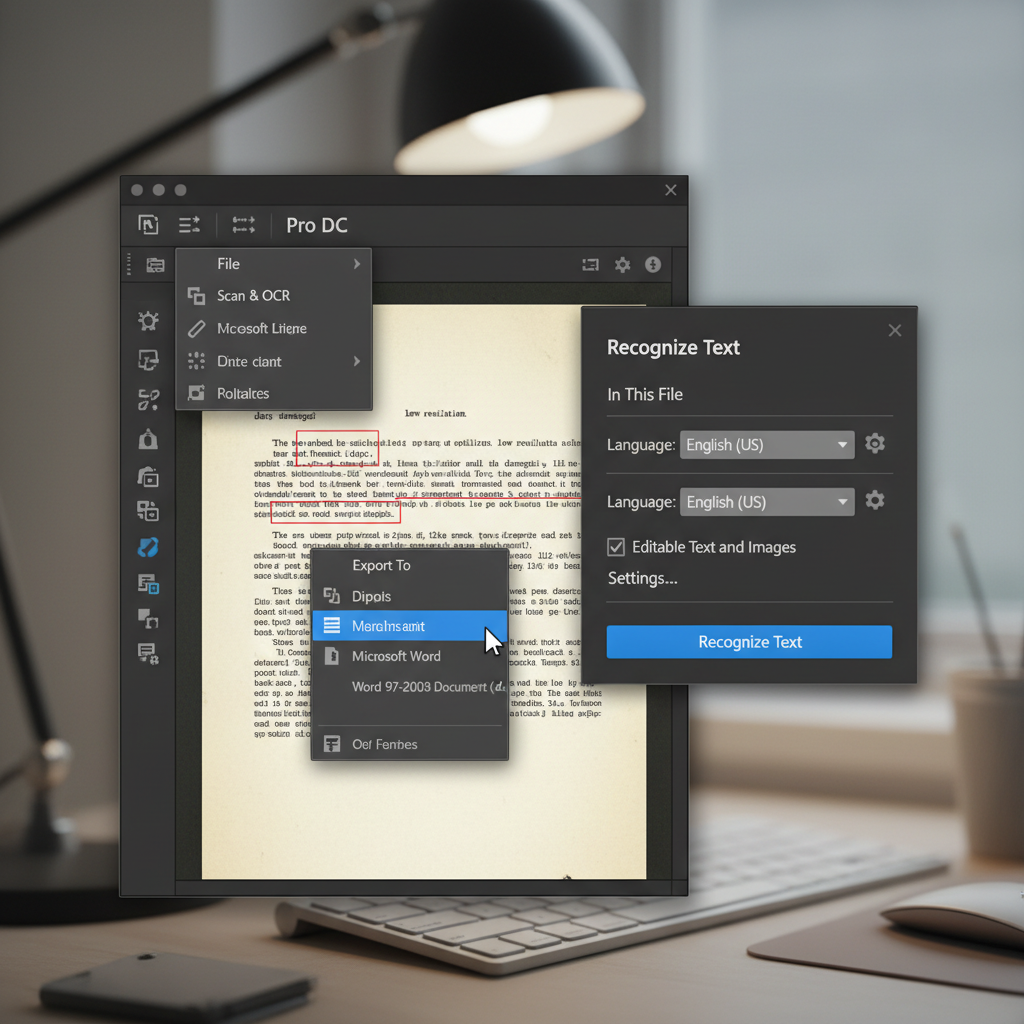
Open your scanned PDF in Adobe Acrobat Pro DC, navigate to the 'Scan & OCR' tool, and run text recognition. Carefully review faded text or misread letter combinations.
Go to 'File' > 'Export To' > 'Microsoft Word' > 'Word Document' (DOCX) to convert the PDF into a format suitable for extensive editing.
Open the exported DOCX file in a compatible word processor to fix any formatting errors or misjoined hyphenated words caused by the conversion process.
Upload the corrected DOCX file to your Google Drive and open it with Google Docs so it can be easily attached to your Google Classroom assignments.
Use WPS Office to Extract and Convert Scanned PDFs
WPS Office offers a highly accurate built-in OCR tool and a powerful PDF to Word converter, allowing you to easily digitize scanned documents, retain complex original layouts, and prepare assignments for your students with minimal formatting cleanup.
- 1. Open the scanned PDF: Launch WPS Office and open your scanned PDF document in the PDF editor.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and select 'OCR' or 'PDF to Word'.
- 3. Configure conversion settings: Choose DOCX as your desired output format and confirm the document language settings to ensure accurate text recognition.
- 4. Convert and edit: Click 'Convert' to generate a fully editable Word document. Review the preserved formatting and upload it to your Google Classroom.

Frequently Asked Questions
Why did the formatting change when I opened my converted DOCX file in Google Docs?
Google Docs uses a different rendering engine than Acrobat or standard desktop word processors. Complex layouts, unique fonts, and specific spacing elements from the original PDF may not translate perfectly into Google's cloud format and often require manual cleanup.
Why are some words hyphenated incorrectly after OCR?
When text is scanned, OCR software often reads line breaks literally. If a word is hyphenated across two lines in the original document, the OCR engine might not automatically merge the fragments back into a single word, requiring you to manually delete the hyphen and space.
Are images lost when using OCR on a PDF?
No, OCR primarily targets text recognition. The underlying images, graphs, or charts in your scanned document should remain intact, though their positioning might shift slightly when exported to an editable Word document format.


