

Automatically Create PDF Bookmarks from a Scanned Table of Contents

Question details
Create PDF bookmarks from a scanned table of contents or index with as much automation as practical.
- Product
- PDF documents and PDF editing tools
- Device & OS
- not provided
- Scenario
- A large scanned PDF has contents or index pages that can be used to build a navigable bookmark list.
- Observed behavior
- The desired result is a set of bookmarks that opens the corresponding PDF pages without creating each bookmark individually.
Check whether you can select text on the contents pages; if not, run OCR first. Compare printed page numbers with PDF page positions, since covers and introductory pages can create an offset.
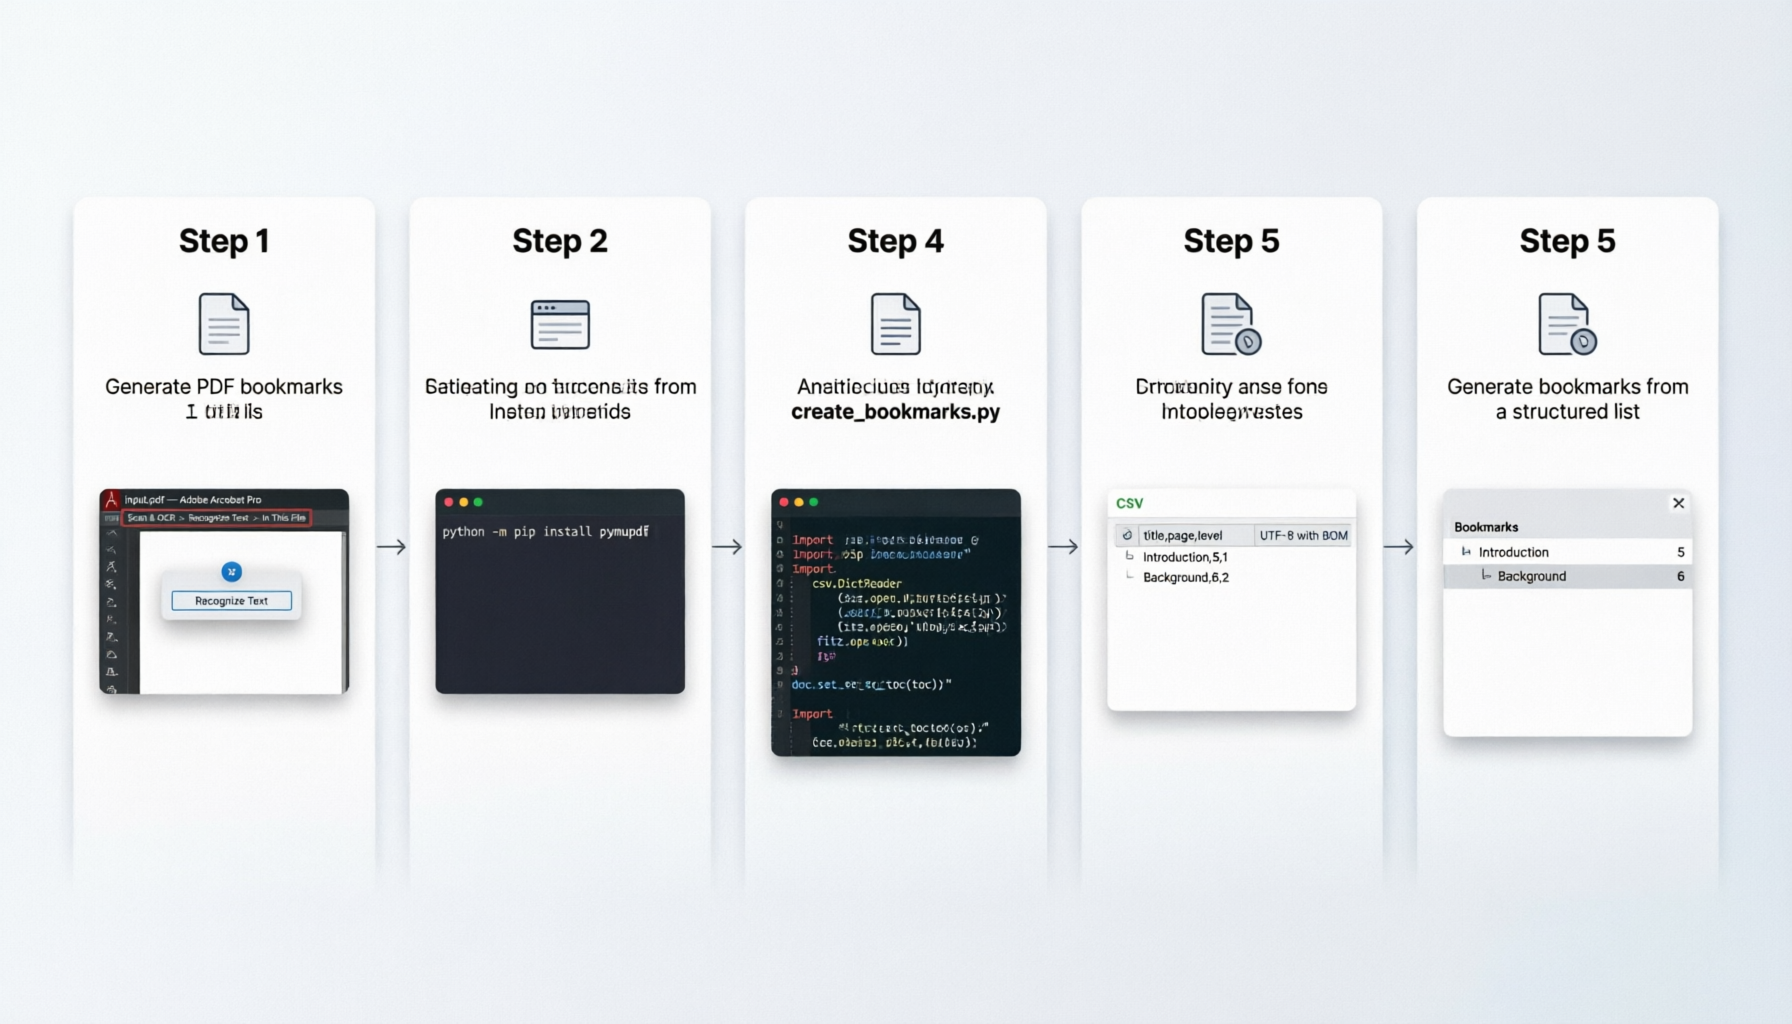
Generate PDF bookmarks from a structured list
Use OCR and a CSV list with a Python script to create many bookmarks in one operation.
This method automates bookmark creation, but preparing the list from OCR text may require manual editing or a separate parser. For an index entry with several references, choose a destination or create separate entries.
The script replaces any existing bookmarks in the output PDF. It uses actual PDF page positions, starting at 1, rather than printed page numbers.
In Adobe Acrobat Pro, open the PDF and select Scan & OCR > Recognize Text > In This File. Save the searchable result as input.pdf.
Copy or export the recognized contents text and create a UTF-8 file named bookmarks.csv with the columns title,page,level. Enter the actual PDF page position for each entry and use 1 for level unless you need nested bookmarks. For example: title,page,level followed by Introduction,5,1 and Background,6,2 on separate lines. Check OCR errors and page offsets before continuing.
Open a terminal in the folder containing input.pdf and bookmarks.csv, then run: python -m pip install pymupdf
Save the following as create_bookmarks.py, then run python create_bookmarks.py in the same folder: import csv import fitz doc = fitz.open('input.pdf') toc = [] with open('bookmarks.csv', newline='', encoding='utf-8-sig') as f: for row in csv.DictReader(f): toc.append([int(row['level']), row['title'].strip(), int(row['page'])]) doc.set_toc(toc) doc.save('bookmarked.pdf') doc.close()
Open bookmarked.pdf and select the Bookmarks panel. Test several entries, especially the first and last entries and any nested bookmarks, and correct the CSV and rerun the script if needed.
Use a PDF tool that imports or generates bookmarks
Use this option if your PDF editor supports importing a bookmark list or generating bookmarks from recognized text.
Review and Add PDF Bookmarks in WPS Office
Use WPS Office to open a PDF, review its contents, and add bookmarks from the navigation panel. This is a manual alternative; it does not assume automatic conversion of an index into bookmarks.
- 1. Open the PDF: Launch WPS Office and use Open to select your scanned PDF.
- 2. Check the contents: Go to the table of contents or index pages and identify the sections and their corresponding PDF page positions.
- 3. Add bookmarks: Open the Bookmarks panel, navigate to a destination page, and use the panel's add bookmark control to name the entry. Repeat for the sections you need.
- 4. Save and test: Save the PDF, then select entries in the Bookmarks panel to confirm that they open the intended pages.

Frequently Asked Questions
Why do I need OCR before using a scanned table of contents?
Scanned pages are often images, so their text cannot be selected or processed. In an OCR-capable editor, use the OCR or Recognize Text command to create searchable text first.
Why does a bookmark open the wrong page?
Printed page numbers may not match PDF page positions because of covers or introductory pages. Check the PDF viewer's page counter and use that position in the bookmark list.
Can an index entry link to more than one page?
A single PDF bookmark normally has one destination. Create separate bookmarks for the references you need, or choose the most useful destination.
Will the Python script preserve existing bookmarks?
No. The set_toc command replaces the existing bookmark tree in the output file. Review the current Bookmarks panel before running it.
Does OCR automatically create the bookmark list?
OCR recognizes text but does not necessarily identify titles and destinations as bookmarks. You may need to format the recognized entries as a CSV list or use a tool with a dedicated bookmark-generation feature.


