

Automate PDF Page Sorting and Table of Contents Creation

Question details
The user needs to process a large archive of scanned certification reports by categorizing, numbering, running OCR, and generating tables of contents automatically.
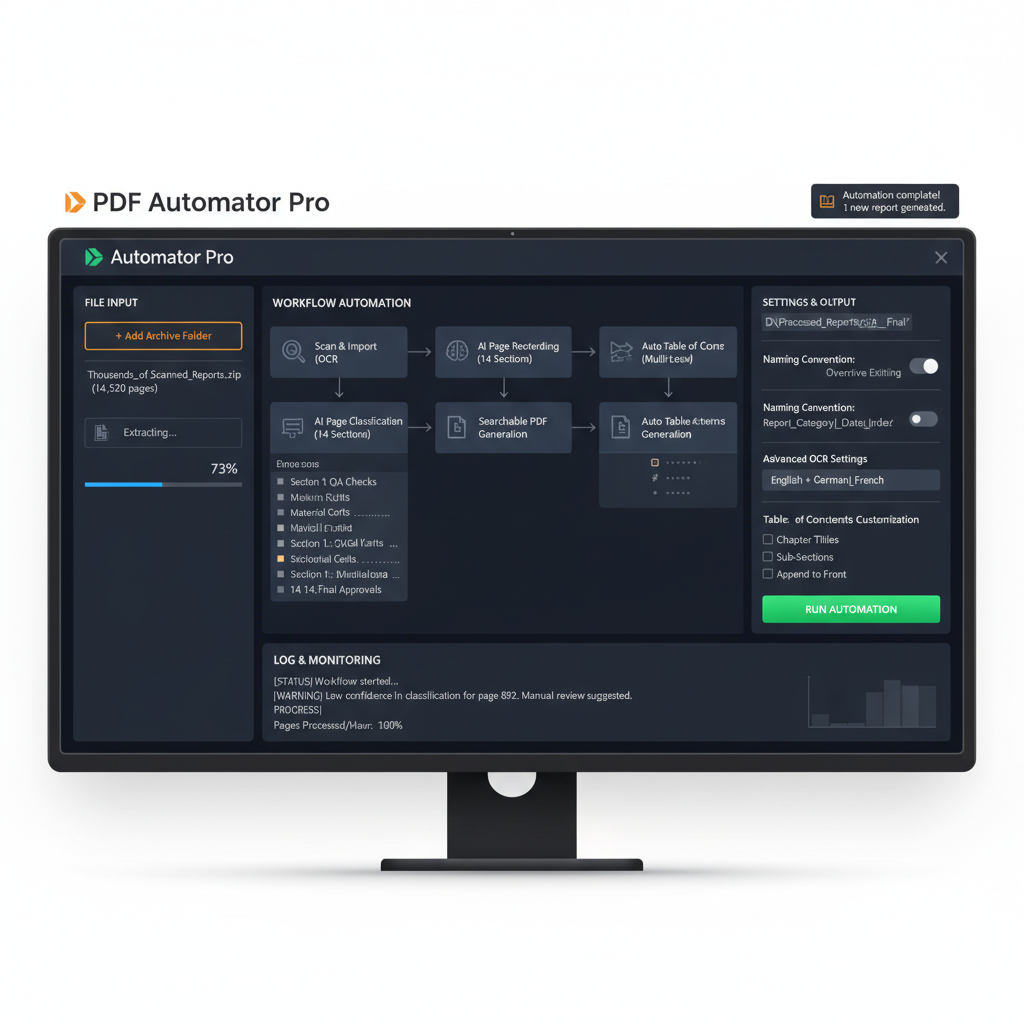
- Product
- Device & OS
- not provided
- Scenario
- Handling thousands of scanned pages that need to be categorized into 14 sections, reordered, and compiled into searchable PDFs with multiple tables of contents without manual intervention.
- Observed behavior
- Manual processing is too slow and costly, so an automated workflow involving OCR, page classification, and indexing is required to manage the massive volume of long files efficiently.
Ensure your scanned documents are at least 300 DPI, as clear images are required for the OCR engine to accurately recognize text for automated categorization and bookmarking.
Use Dedicated PDF Automation Plug-ins or Standalone Software
For processing thousands of long documents, dedicated plug-ins or standalone applications are highly recommended as they operate significantly faster than standard scripting.
While Acrobat JavaScript can automate tasks, it executes synchronously and can be 100 to 1,000 times slower than compiled software, making it highly impractical for massive file volumes.
A specialized standalone tool or C++ plug-in can utilize multi-threading to handle OCR, classify pages into sections, insert headers, and generate tables of contents at scale.
Look for enterprise-grade PDF processing tools or custom plug-ins designed for high-volume batch processing and document categorization.
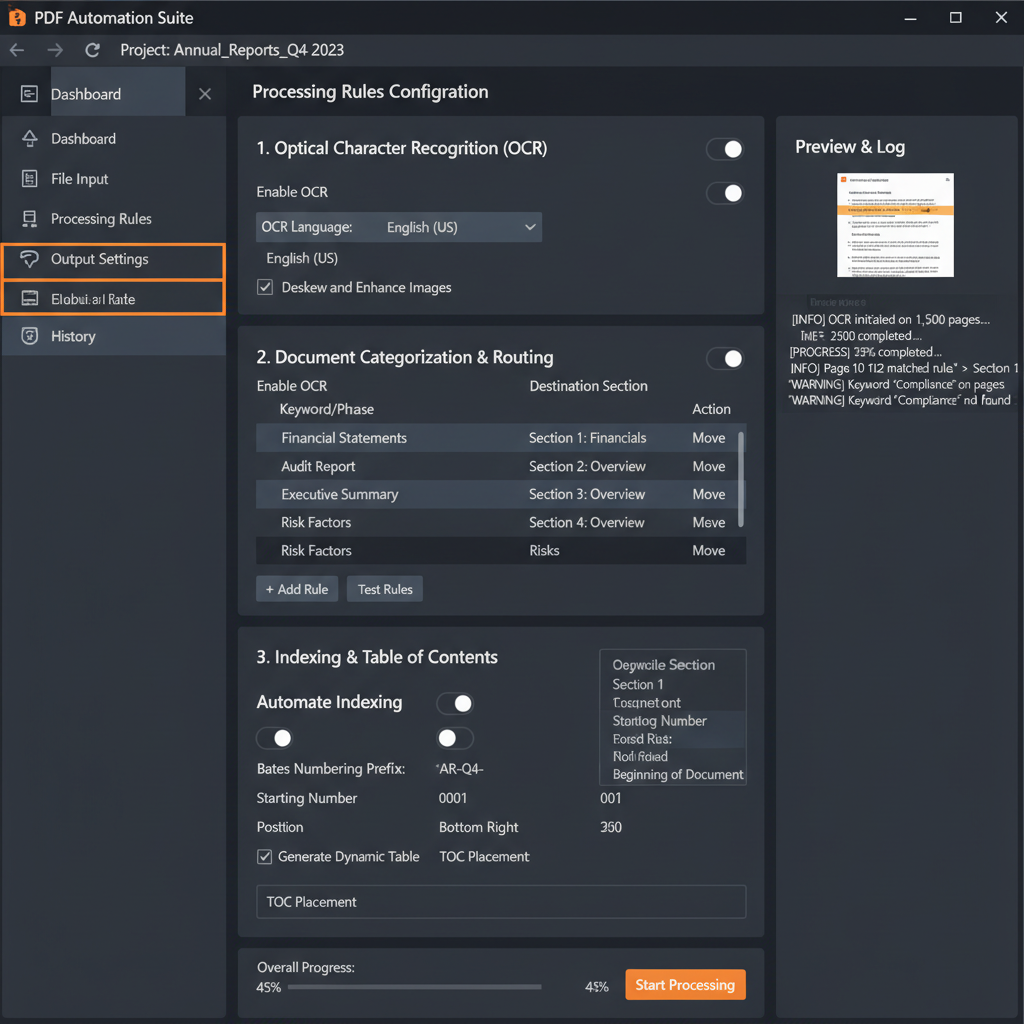
Set up the software to run Optical Character Recognition (OCR) first. Then, define keyword-based rules to identify which of the 14 sections a page belongs to based on the extracted text.
Configure the tool's settings to automatically apply sequential Bates numbering to the categorized pages and generate a dynamic Table of Contents based on the newly mapped structure before saving.
Utilize Acrobat JavaScript for Smaller Batches
If you are processing smaller files or breaking the archive into manageable chunks, you can write custom scripts to automate pagination and basic sorting.
Streamline PDF Sorting, OCR, and Indexing with WPS Office
While fully automated enterprise routing requires custom programming, WPS Office provides a powerful, built-in suite of PDF tools to rapidly handle OCR, page extraction, and table of contents creation without expensive plug-ins.
- 1. Run OCR on Scanned Reports: Open your scanned PDF in WPS Office. Navigate to the 'Tools' tab and click 'OCR' to convert the document images into selectable, searchable text.
- 2. Organize and Categorize Pages: Go to the 'Page' tab. Use 'Extract Pages' or 'Split PDF' to manually or semi-automatically divide your large archive into the 14 required sections.
- 3. Add Page Numbers: Switch to the 'Insert' tab and click 'Page Number' to apply sequential numbering or custom headers across your newly organized document.
- 4. Generate Table of Contents: Open the Navigation Pane on the left. Create Bookmarks for your section headers, which can then be used to generate a structured Table of Contents.

Frequently Asked Questions
Can OCR automatically categorize my PDF pages?
OCR itself only converts images of text into machine-readable text. To automatically categorize pages, you need an additional script or rule-based software that reads the OCR text, searches for specific keywords, and routes the pages accordingly.
Why is JavaScript not recommended for processing massive PDF files?
Acrobat JavaScript executes synchronously and runs within the standard application memory space. Processing thousands of pages requires enormous memory, making scripts hundreds of times slower than dedicated compiled plug-ins, often leading to performance issues and crashes.
How do I create a table of contents from scanned PDFs?
First, you must process the document with OCR so the text is recognizable. Once searchable, you can use your PDF editor to bookmark key section headers. Advanced PDF tools can then take those bookmarks and automatically generate a clickable table of contents page.


