

How to Run Text Recognition on Only the First PDF Page

Question details
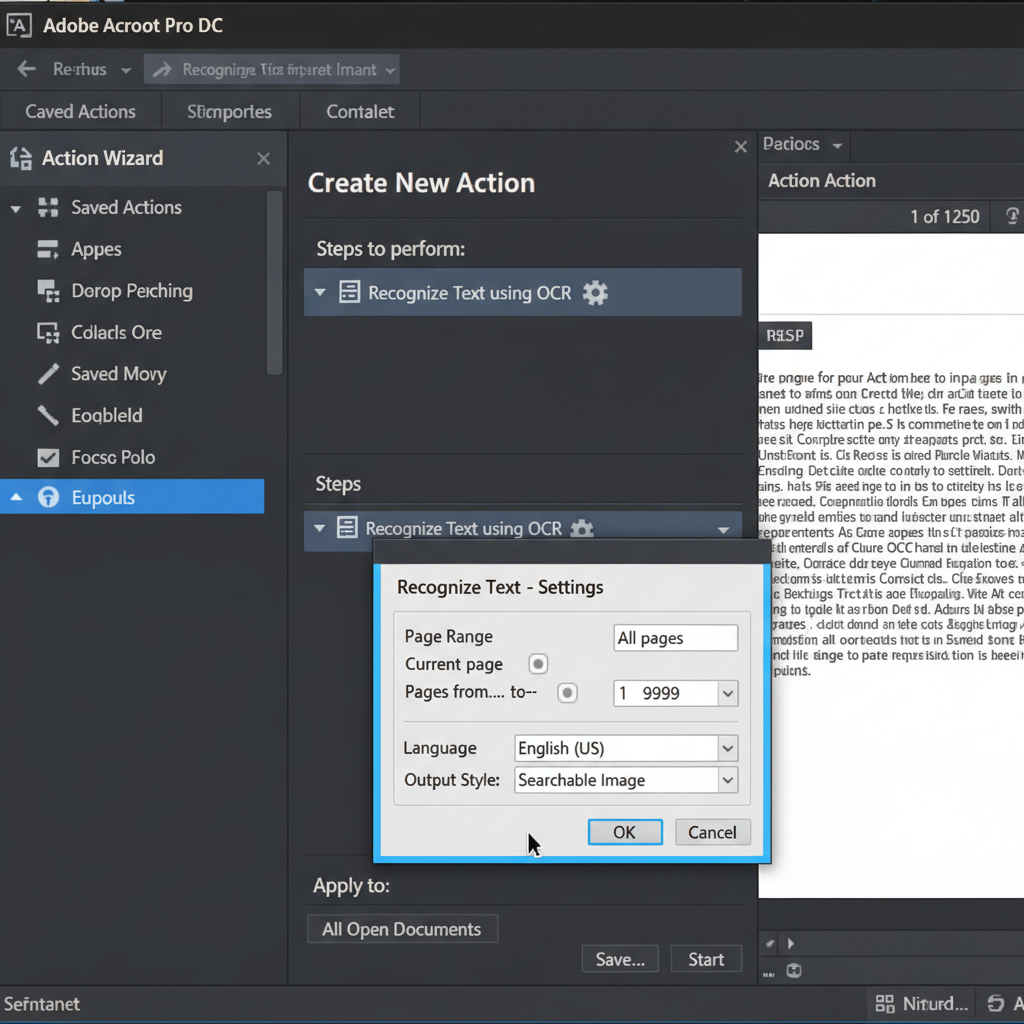
The user wants to perform text recognition strictly on the first page of a large PDF to avoid long processing times and system resource exhaustion.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Using the Action Wizard to process a large multi-page PDF document where only the first page requires OCR.
- Observed behavior
- The Action Wizard does not natively support running text recognition on a specific page or limited page range, forcing the entire document to be processed.
Verify the exact physical page number you need to extract, as the first page of the document's content might differ from the cover page or roman-numeral preface pages.
Extract and Replace the First Page for Text Recognition
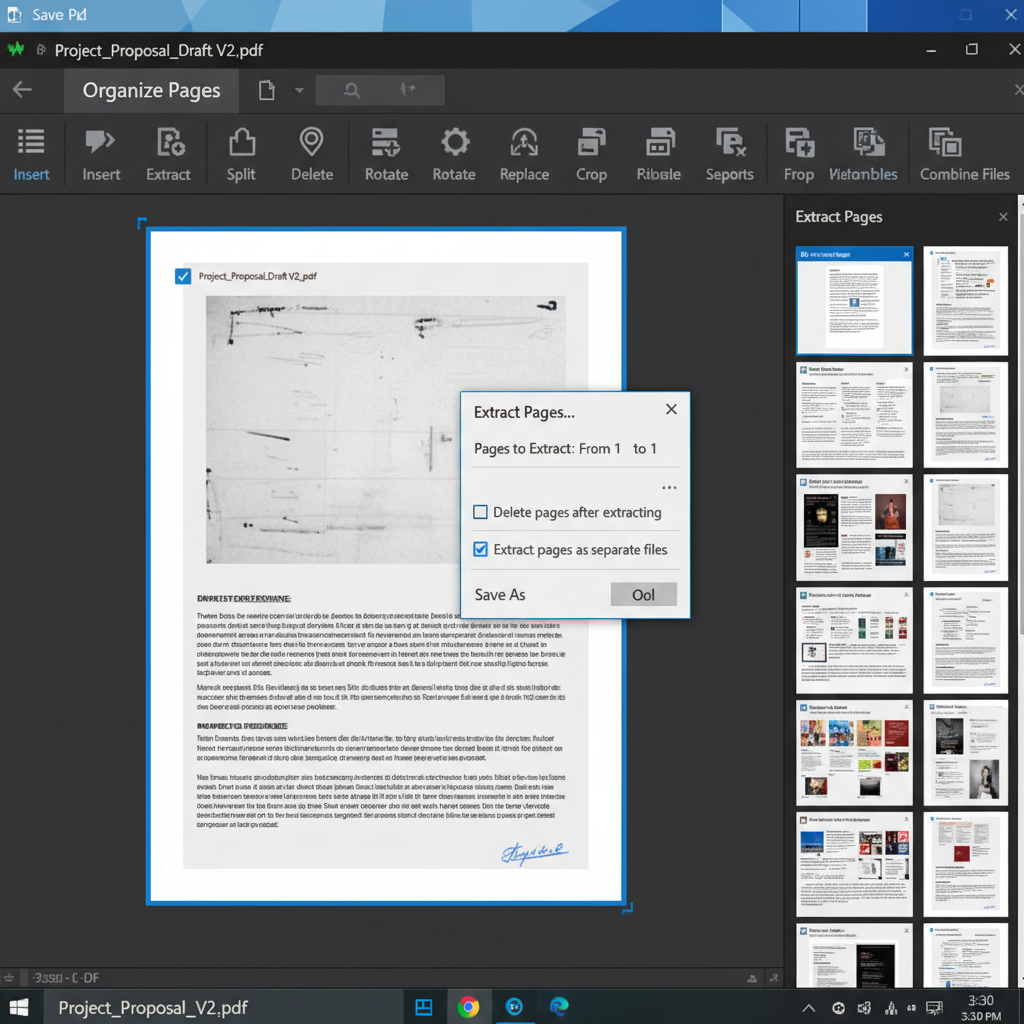
Since Action Wizard processes entire documents, you must extract the first page as a separate file, run OCR on it, and insert it back into the original document.
This workaround ensures your system only expends resources scanning the single page you need. After processing, you simply swap out the unrecognised page in your main file.
Open your large PDF document. Go to the 'Organize Pages' tool, select the first page, and choose 'Extract' to save it as a new, independent PDF file.
Open the newly created single-page PDF. Run your standard text recognition or OCR action on this file and save the changes.
Return to your original multi-page PDF document. Using the 'Organize Pages' tool, select and delete the unrecognised first page.
Click 'Insert' within the Organize Pages menu, locate your OCR-processed single-page PDF, and insert it at the very beginning of the document.
Use WPS PDF to Run OCR on Specific Pages Automatically
Skip the tedious process of extracting and replacing pages. WPS Office includes a powerful built-in OCR feature that lets you specify exact page ranges to process in seconds.
- 1. Open the PDF: Launch WPS Office and open your large multi-page PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Set the Page Range: In the OCR settings dialog box, locate the 'Page Range' option and set it to process only page 1.
- 4. Extract or Convert: Click 'Extract Text' or choose to convert the selected page into a searchable PDF format instantly.

Frequently Asked Questions
Can Acrobat Action Wizard process specific page ranges for text recognition?
No, Acrobat does not natively support running text recognition on a specific page range directly through the Action Wizard. You must extract the target pages into a separate file first.
Why does my large PDF fail or freeze during text recognition?
Processing very large PDF documents requires significant memory and CPU power. If your system runs out of resources, the application may freeze, which is why isolating specific pages is an effective workaround.
Will OCR accurately recognize handwritten text on my PDF cover page?
Standard PDF text recognition engines are optimized for typed or printed fonts. They generally struggle to interpret handwritten text accurately, so manual transcription may be required.


