

Extract PDF Pages Based on Barcode Detection in Adobe Acrobat

Question details
Separate a large PDF into files containing pages with and without barcodes.
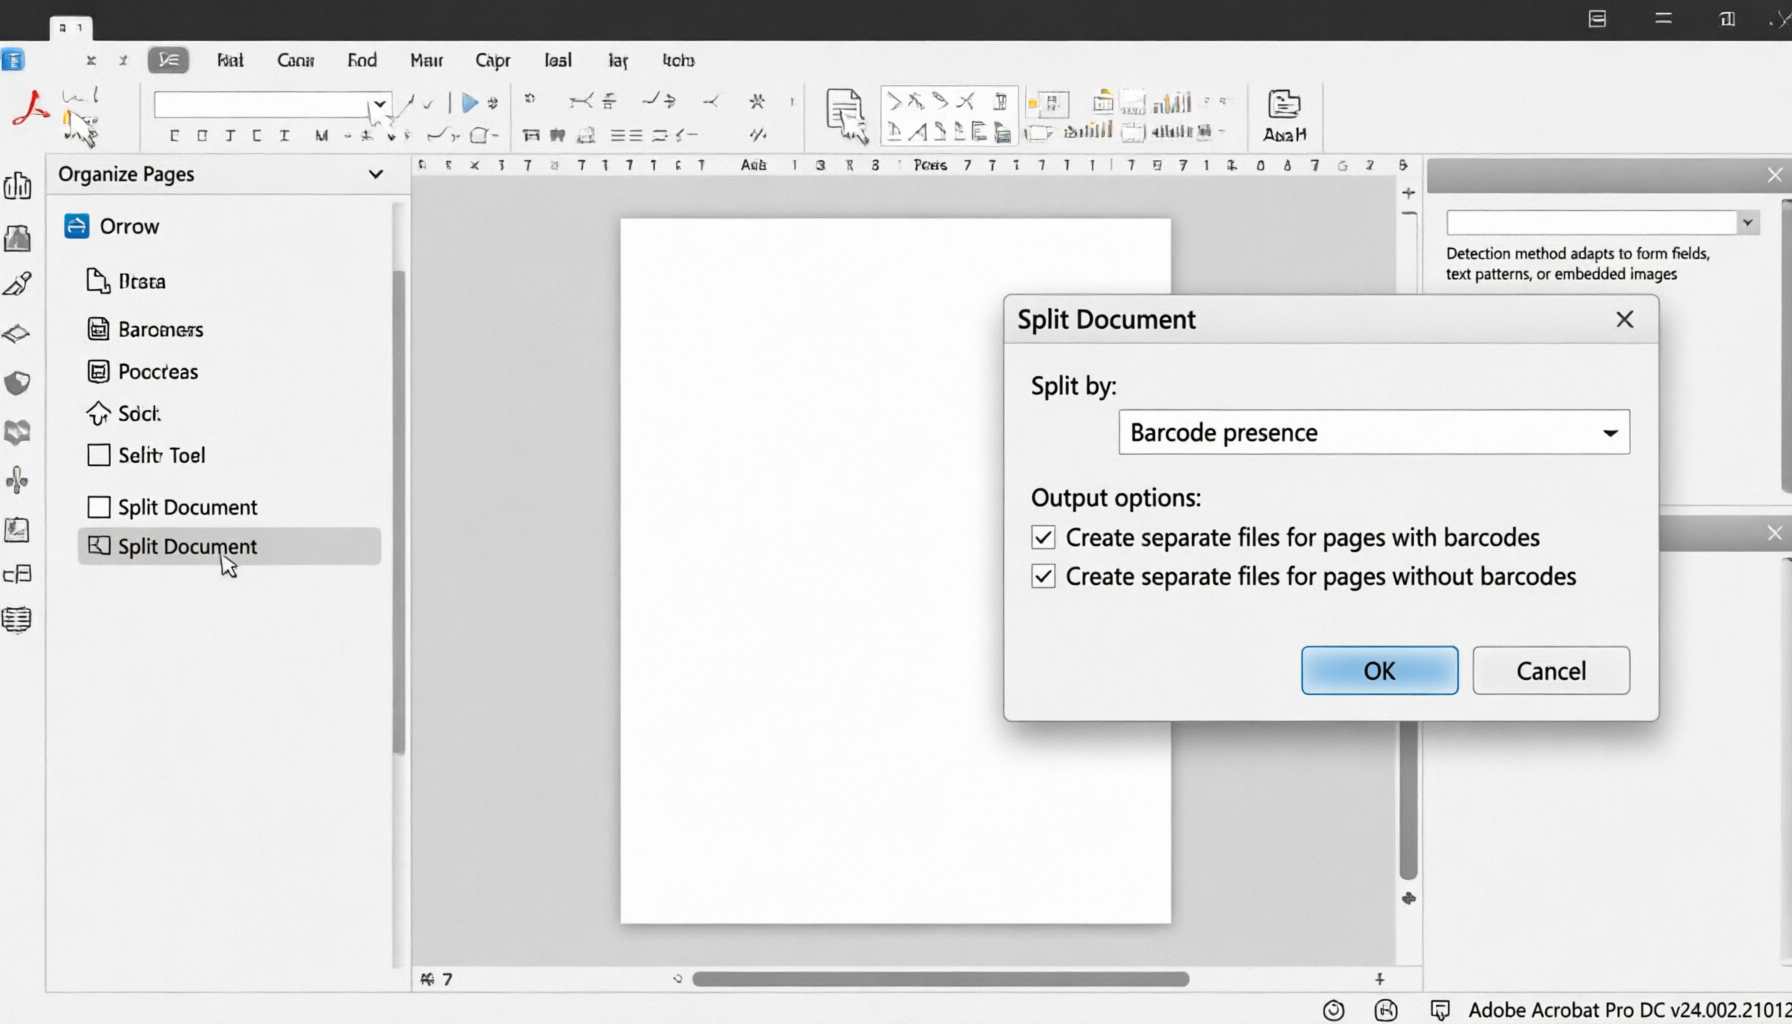
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- The user needs to classify PDF pages by barcode presence and extract each group into a separate PDF.
- Observed behavior
- The detection method depends on whether the barcode is represented by a form field, identifiable text, or an image.
Open the PDF in Acrobat and check whether the barcode is a form field, has associated searchable text, or appears only as an image. Make sure your Acrobat edition supports page extraction.
Classify pages using form fields or searchable text
Use this approach when a reliable form field or text pattern identifies the pages that contain barcodes.
A script can classify pages using a known field or text pattern, but a field or text match alone does not necessarily prove that a barcode is present. Check that the marker consistently corresponds to a barcode before relying on it.
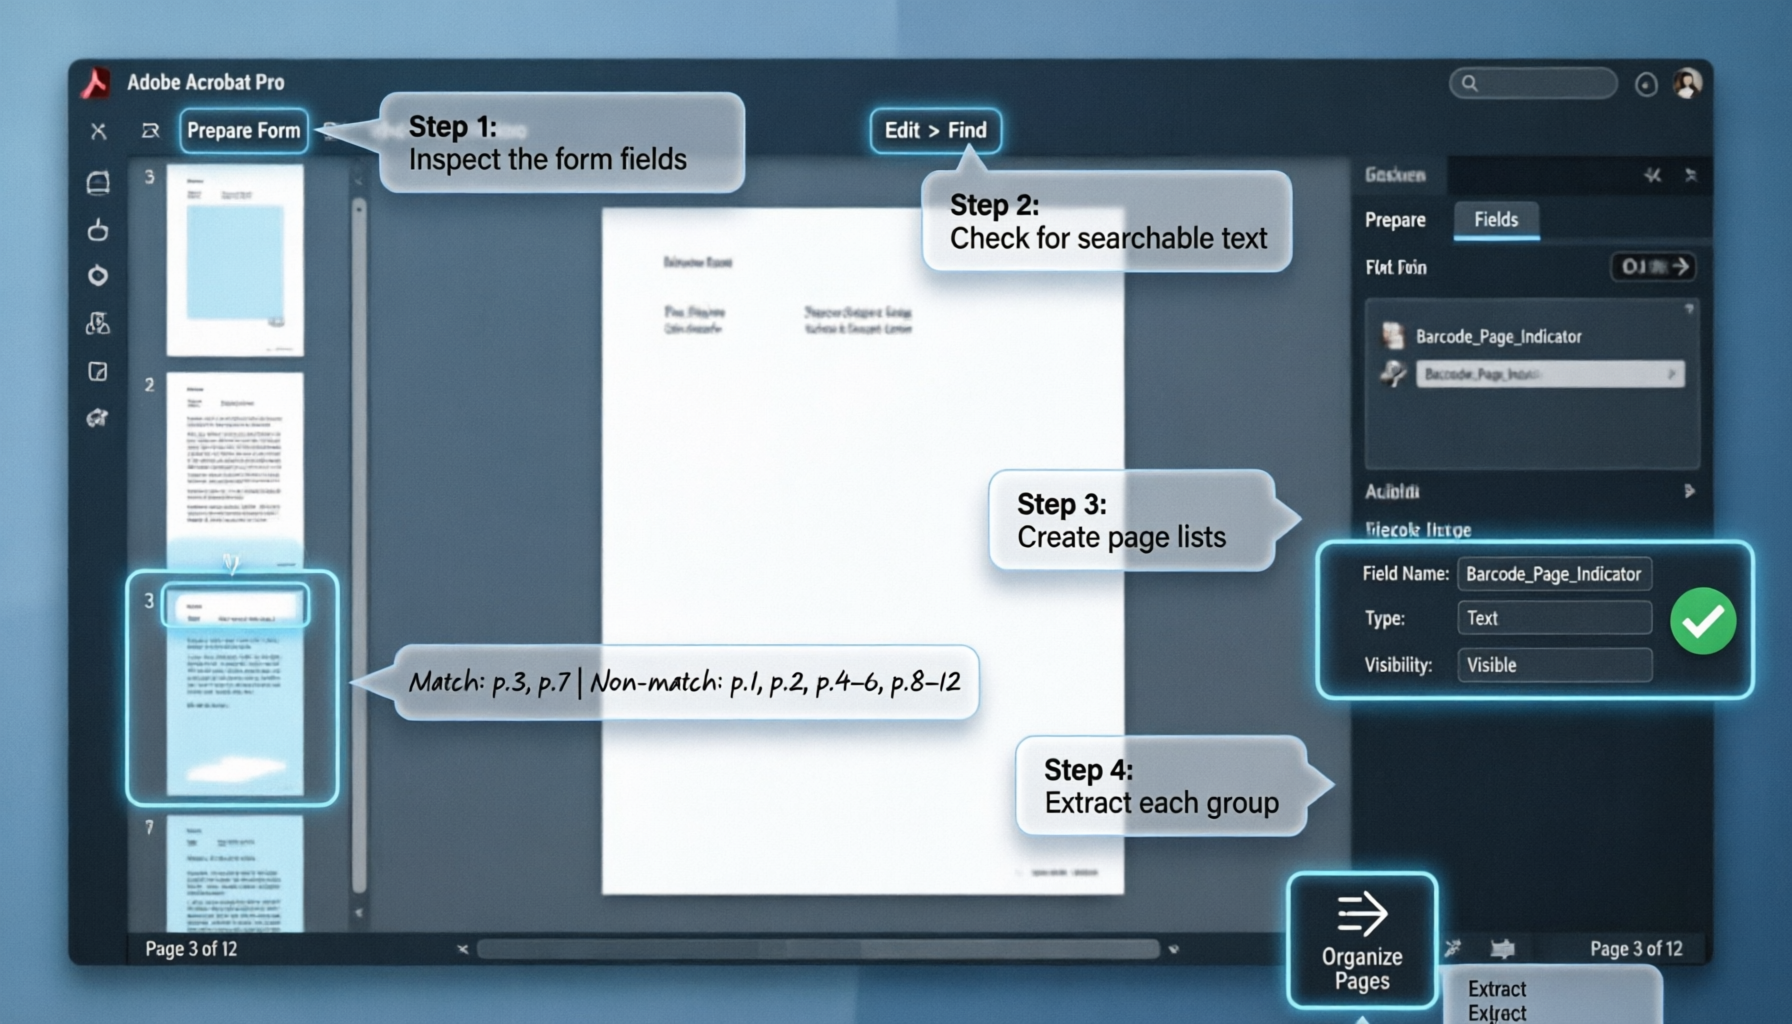
Open the PDF in Acrobat and choose Tools > Prepare Form. Check whether barcode pages have a consistently named field that can identify them.
Use Edit > Find to search for a distinctive text pattern associated with the barcode. Compare the results with several pages to verify that the pattern identifies the intended pages.
Record the matching and nonmatching page numbers, or use an Acrobat JavaScript that checks the verified field or text pattern and reports the page numbers for each group.
Open Tools > Organize Pages, select the barcode pages, and choose Extract. Save the extracted PDF, then repeat from the original document for the non-barcode pages.
Use barcode recognition for image-only barcodes
Use a barcode recognition tool when the barcode is an image and there is no reliable field or searchable text marker.
Separate Reviewed Barcode Pages with WPS PDF
Use WPS PDF to review a document and extract identified pages into separate PDFs. For automatic detection of image-only barcodes, first use a barcode recognition tool to produce the page lists.
- 1. Open the PDF: Open WPS Office, choose Open, and select the PDF to review.
- 2. Identify the page groups: Review the pages and record which contain barcodes. For automatic image-only barcode detection, scan the PDF with a barcode recognition tool and use its page results.
- 3. Extract barcode pages: In the PDF page tools, choose Extract Pages, select the identified barcode pages, and save the resulting PDF.
- 4. Extract the remaining pages: Return to the original PDF, choose Extract Pages again, select the non-barcode pages, and save them as a separate PDF.

Frequently Asked Questions
Can Acrobat JavaScript detect a barcode that is only an image?
Standard Acrobat JavaScript cannot reliably recognize or decode an image-only barcode by itself. Use a barcode recognition tool to identify the pages, then extract them in Acrobat.
Does searchable text guarantee that a page contains a barcode?
No. Use Edit > Find to test the text pattern against several pages. Only use it as a classifier if it consistently corresponds to the barcode pages in your document.
Can OCR replace a barcode reader?
OCR may recognize printed text near a barcode, but it may not read the barcode itself. Use a barcode decoder when you need to detect or decode the barcode image.
How do I keep both page groups when extracting in Acrobat?
In Tools > Organize Pages, extract and save the first group without deleting those pages from the original. Then select and extract the second group from the original PDF.


