

Fix Acrobat Cannot Find Text Due to Corrupted PDF Font Encoding

Question details
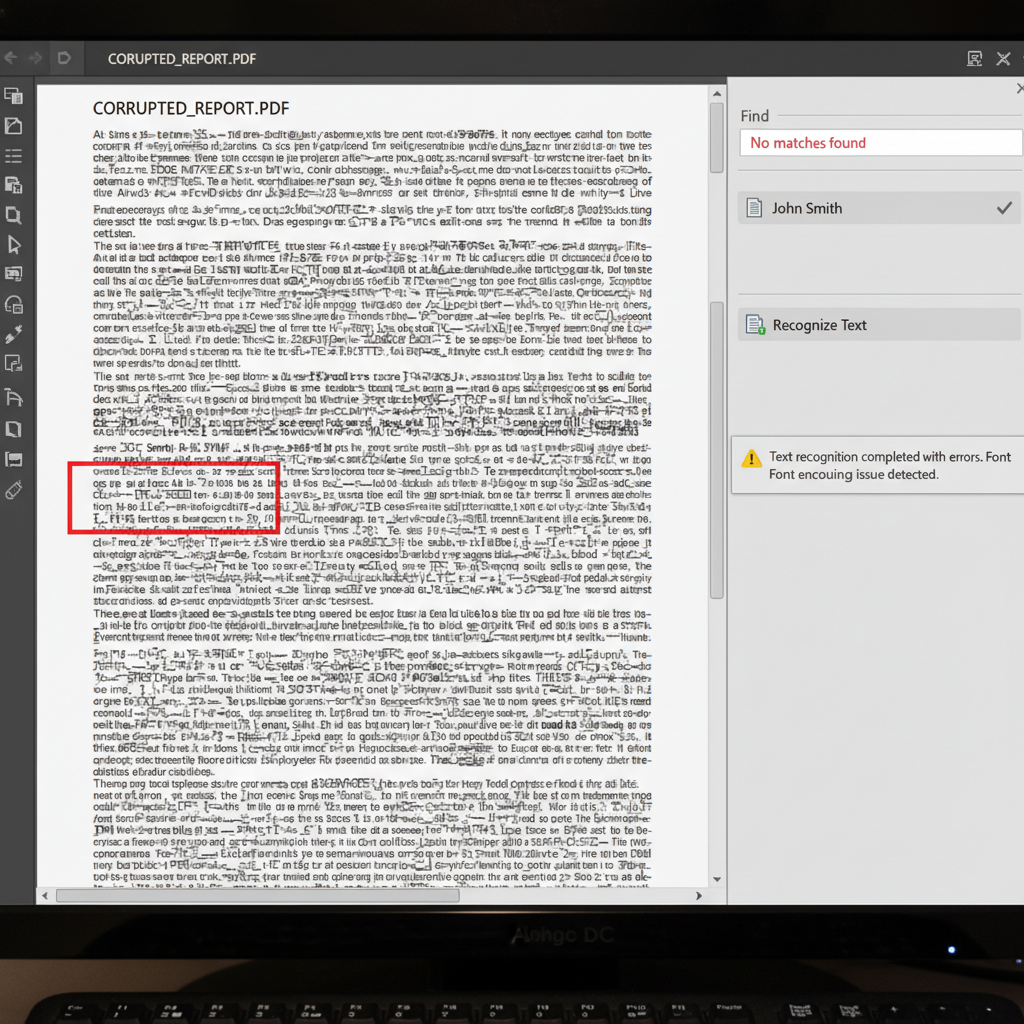
The user is unable to search for specific text, such as a person's name, in a PDF using Acrobat Pro DC because the document's font encoding is corrupted.
- Product
- Adobe Acrobat Pro DC / PDF
- Device & OS
- not provided
- Scenario
- Searching for specific words or running the Find tool within a PDF document.
- Observed behavior
- The text search fails to locate words that visually appear on the page. Even after applying OCR to the document, the text remains unsearchable due to broken or incorrect font encoding.
Verify that your PDF viewer's search function works on other standard documents to rule out software glitches, and ensure you have permission to edit or extract images from the current PDF.
Rebuild the Text Layer by Exporting to Images and Applying OCR
This method bypasses the corrupted font encoding by flattening the PDF into image files and generating a completely new, searchable text layer using OCR technology.
When a PDF has corrupted font encoding, the internal mapping of characters is broken, making standard text extraction or search fail. Flattening the file into images strips away the corrupted text layer entirely.
By applying OCR (Optical Character Recognition) to the newly created images, the software visually identifies the letters and creates fresh, accurately encoded text.
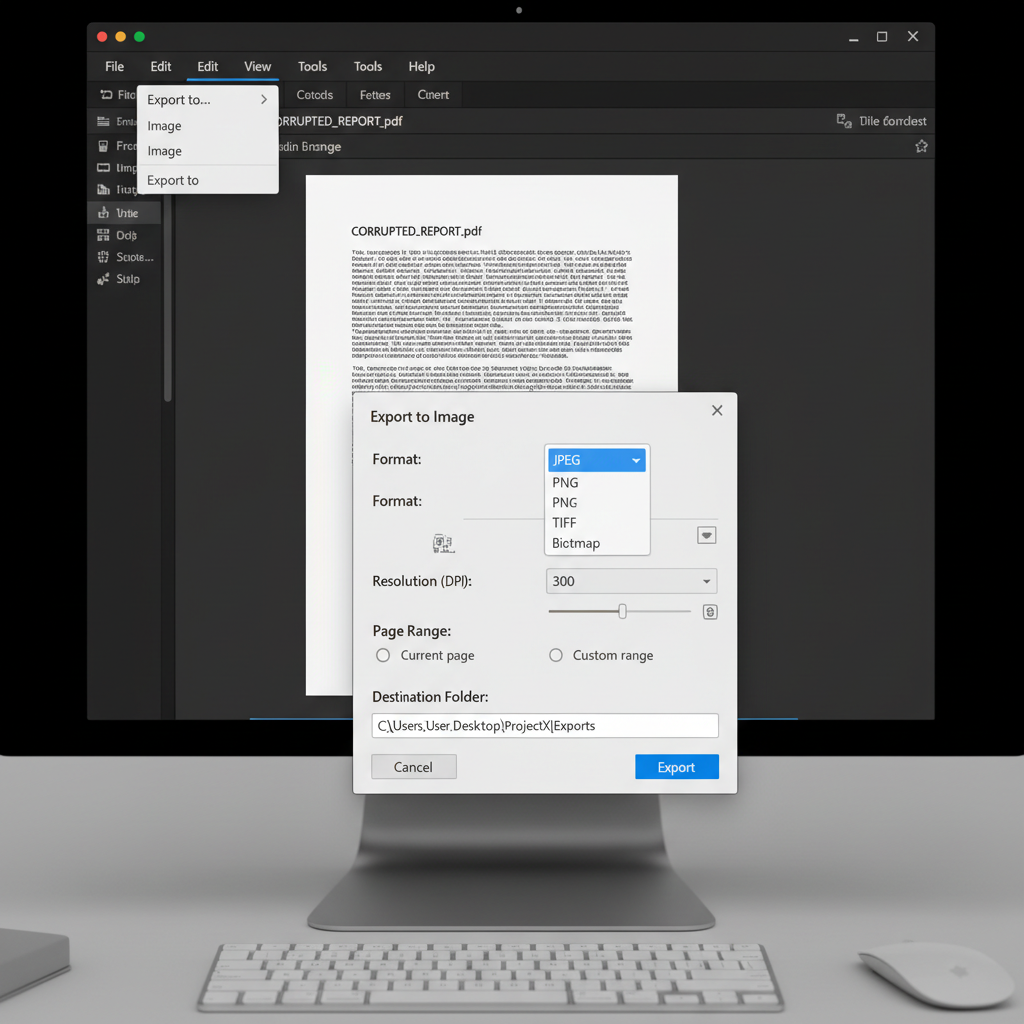
Open the corrupted PDF in your PDF editor. Navigate to the export or conversion menu and choose the option to export all pages as high-quality image files, such as JPEG or PNG.
Use the 'Combine Files' or 'Create PDF from Images' tool to merge your newly exported image files into a single, fresh PDF document.
Open the new image-based PDF and locate the OCR (Optical Character Recognition) tool in your software's Edit or Tools menu. Run the OCR process to extract and embed recognizable text.
Once the OCR process is complete, press Ctrl+F (or Cmd+F on Mac) to search for specific names or phrases to confirm the Find feature is functioning correctly.
Fix Corrupted PDF Fonts and Run OCR with WPS Office
WPS Office provides powerful PDF editing features, including high-quality PDF to Picture conversion, Picture to PDF creation, and highly accurate OCR. You can quickly rebuild corrupted PDF text layers and make documents searchable without relying on expensive software.
- 1. Convert PDF to Picture: Open your corrupted PDF in WPS Office. Navigate to the Tools tab and click 'PDF to Picture' to export your pages as high-quality images.
- 2. Combine into a New PDF: Go to the Tools tab and select 'Picture to PDF' to easily combine your freshly exported images back into a clean PDF file.
- 3. Apply OCR: Click the 'OCR' button on the Tools tab to let WPS Office automatically scan and rebuild the text layer for the entire document.
- 4. Search Your Document: Press Ctrl+F to use the Find tool, ensuring your text is now fully searchable and accessible.

Frequently Asked Questions
Why does font encoding get corrupted in PDF files?
Font encoding corruption usually occurs when the original software used to generate the PDF fails to embed the fonts correctly, or when proprietary, non-standard fonts are improperly substituted during file conversion or transfer.
What is OCR and how does it fix unsearchable text?
OCR (Optical Character Recognition) is a technology that scans the visual shapes of letters in an image and converts them into machine-encoded, searchable text. By converting a corrupted PDF to images and applying OCR, you completely replace the broken font encoding with a new, readable text layer.
Can I extract text directly without converting the whole PDF to images?
If only a specific paragraph or section has corrupted fonts, you can use your computer's built-in Screen Capture or Snipping tool to take a screenshot of that specific area. You can then paste that image into an OCR tool to extract the necessary text quickly.


