

Fix Acrobat Pro Crashing During OCR of Large PDF Files

Question details
The user experiences application crashes when attempting to perform OCR (Optical Character Recognition) on heavy or large PDF files.
- Product
- Adobe Acrobat Pro
- Device & OS
- Windows
- Scenario
- Running text recognition on high-volume or heavily scanned PDF documents.
- Observed behavior
- Acrobat Pro closes or crashes unexpectedly, typically near the end of the OCR processing task, despite having adequate system memory and disk space.
Ensure that you have saved a backup copy of your original PDF document before splitting or modifying it, and close other resource-heavy background applications to free up CPU for the OCR process.
Split the PDF Document into Smaller Sections
Dividing a large PDF into multiple smaller files reduces the processing load and helps prevent memory-related crashes during OCR.
Even when Windows reports sufficient memory, 32-bit processes or internal application limits can cause software to crash when processing massive amounts of high-resolution scanned data at once.
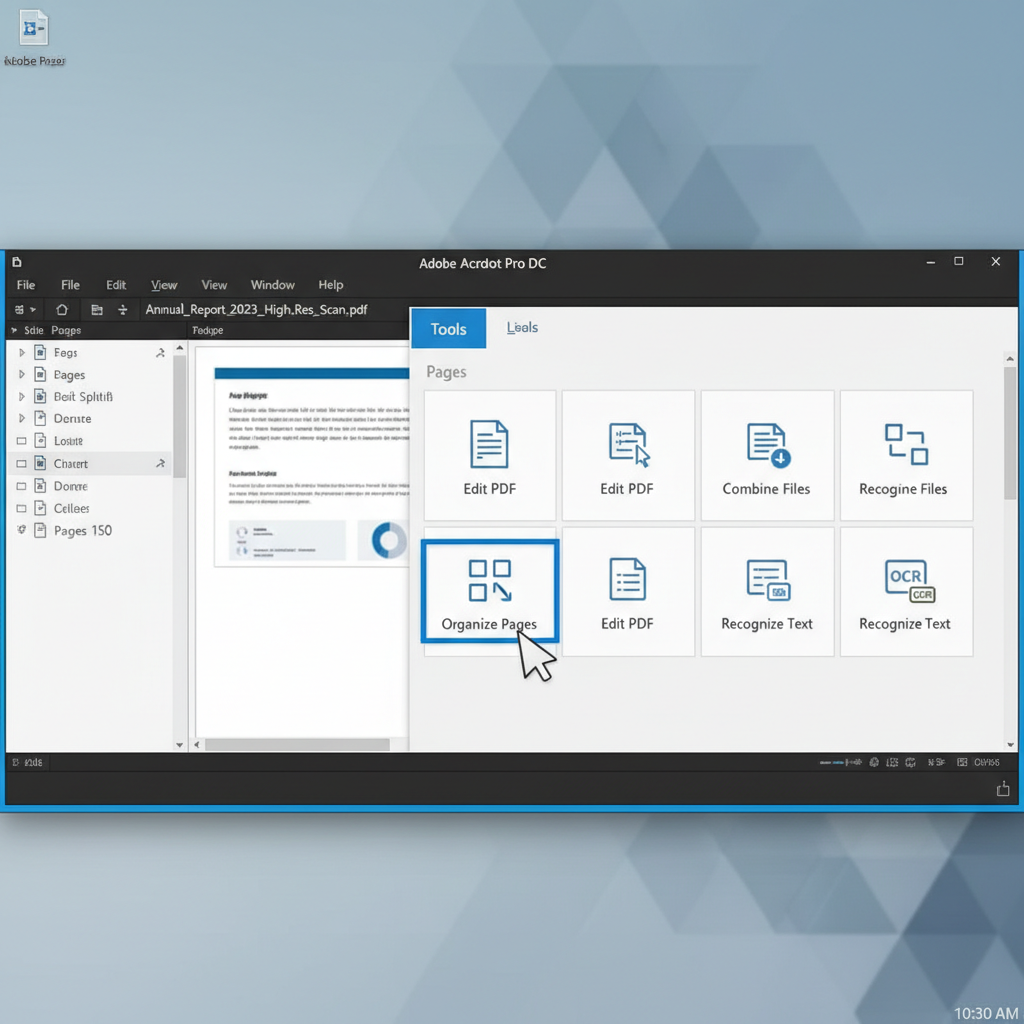
Open your large document in Acrobat Pro, navigate to the Tools menu, and select 'Organize Pages'.
Select 'Split' from the top toolbar. Choose to split the document by a specific number of pages (e.g., 20-50 pages per file) or by maximum file size.
Click 'Output Options' to select a dedicated target folder on your computer, then click 'Split' to save the smaller PDF sections.
Open each newly created smaller PDF file one by one and run the 'Recognize Text' (OCR) tool on them individually.
Once all parts are successfully processed, use the 'Combine Files' tool from the main menu to merge the OCR-completed PDFs back into a single document.
Update Acrobat Pro and Windows OS
Applying the latest software updates ensures maximum compatibility and patches known memory leak issues that cause crashing.
Use WPS PDF to Effortlessly OCR and Manage Large Documents
If Acrobat Pro continues to struggle with heavy PDF files, WPS PDF provides a highly stable, lightweight environment for performing accurate OCR, splitting, and merging large documents without crashing.
- 1. Open PDF in WPS: Launch WPS Office and open your large PDF document using the robust WPS PDF editor.
- 2. Split Document (If Needed): If the file is exceptionally large, use the 'Split PDF' feature under the 'Page' tab to divide the document into manageable chunks.
- 3. Run OCR Tool: Navigate to the 'Tools' tab and select 'OCR' to accurately extract or recognize text within your scanned pages.

Frequently Asked Questions
Why does OCR consume so much memory and cause crashes?
Optical Character Recognition (OCR) requires the software to analyze complex image data pixel by pixel to identify text shapes. For large files with high-resolution scans, this process requires immense RAM and CPU power, which can overwhelm the application's limits if a single continuous task runs too long.
How many pages should I include when splitting my PDF for OCR?
A general rule of thumb is to split large documents into chunks of 20 to 50 pages, depending on the image quality and DPI of the scan. This usually keeps the processing load well within the application's stability limits.
Can a damaged source file cause OCR to fail?
Yes. If a specific page within your scanned PDF contains corrupted metadata or malformed image elements, the OCR engine may encounter a fatal error when trying to process it, causing the entire application to crash.
Are there ways to reduce the PDF file size before running OCR?
Yes, you can compress the PDF using standard optimization tools to lower the image resolution (for example, downscaling to 300 DPI). This significantly reduces the workload on the OCR engine and lowers the chance of crashing.


