

Fix Adobe Acrobat Not Finding Cyrillic or Ukrainian Text in PDF

Question details
The user needs to find Cyrillic or Ukrainian text within a bilingual PDF document, but the search function is failing to locate these specific characters.
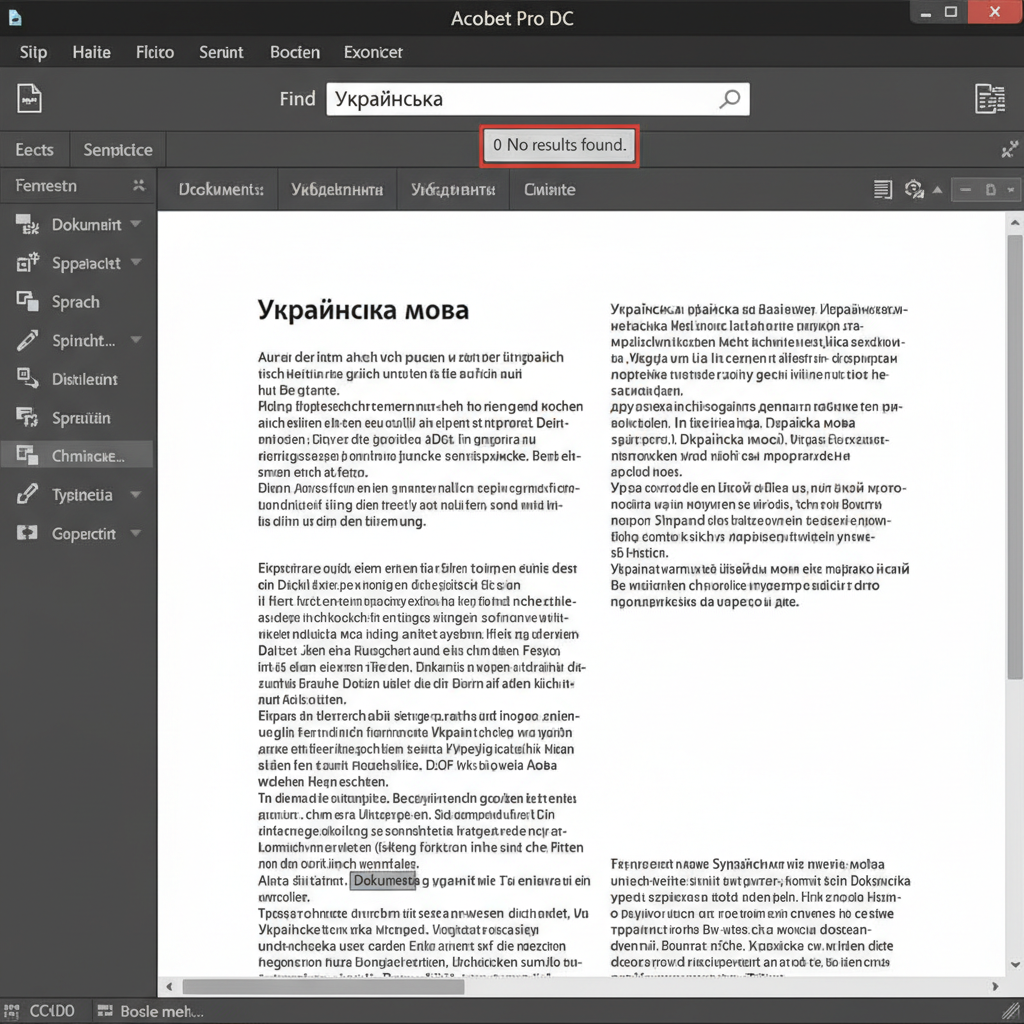
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Searching for specific foreign language text (Cyrillic/Ukrainian) within a bilingual or multilingual PDF document using the built-in search tool.
- Observed behavior
- The search function successfully locates Latin-based text (like German) but returns zero results for Ukrainian or other Cyrillic characters, even when searching letter by letter.
Before attempting complex fixes, test whether the Cyrillic text can be manually selected and copied to a simple text editor like Notepad. If it pastes as random symbols or cannot be highlighted at all, the issue is likely related to missing OCR data or corrupted font encoding.
Run OCR with Correct Language Settings
If the PDF is a scanned image or the text is not selectable, you need to use the Optical Character Recognition (OCR) tool with the appropriate Cyrillic language packs to make the text searchable.
Running OCR with the wrong language setting forces the software to guess Latin characters, which breaks the search for Cyrillic languages.
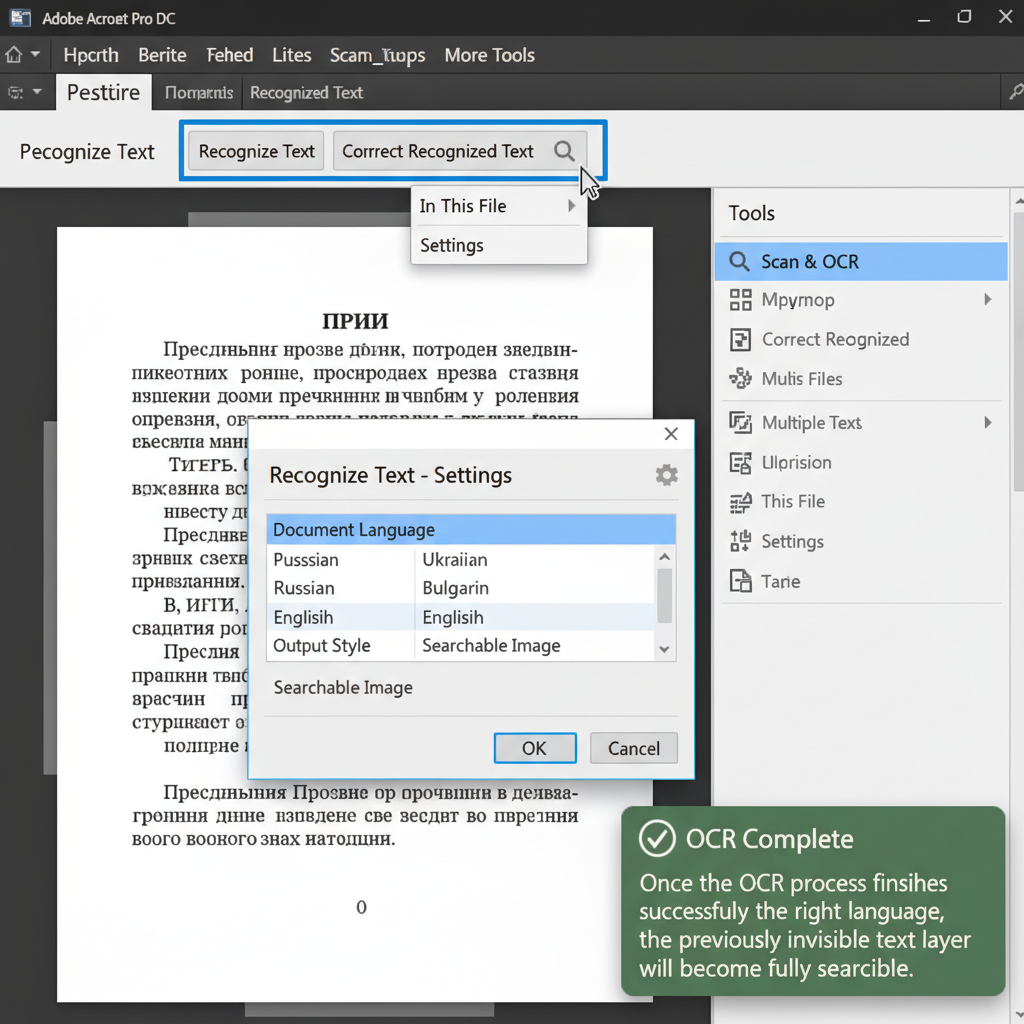
Open the PDF document in Adobe Acrobat, navigate to the 'Tools' menu, and select 'Scan & OCR'.
Click on 'Recognize Text' in the top toolbar and choose 'In This File' from the dropdown menu.
Click the 'Settings' gear icon, and ensure the 'Document Language' is explicitly set to Ukrainian or the specific Cyrillic language used in your file.
Click 'Recognize Text' to process the document. Once completed, press Ctrl + F to try searching for your Cyrillic text again.
Recreate the PDF with Embedded Cyrillic Fonts
If the text is selectable but pastes incorrectly, the PDF might have missing or unembedded Cyrillic fonts. Recreating the PDF ensures all font data is saved.
Optimize and Rebuild the PDF File
If the text is properly selectable and encoded but the search index is corrupted, saving an optimized copy can clear hidden data and fix search indexing issues.
Easily Search and OCR Multilingual PDFs with WPS Office
If your current PDF reader continues to struggle with Cyrillic text, you can use WPS Office to open, search, and edit your PDFs seamlessly. WPS PDF includes advanced OCR capabilities that accurately recognize multiple languages and resolve search issues instantly.
- 1. Download and Install: Download WPS Office for free from the official website and open the WPS PDF application.
- 2. Open the PDF: Click 'Open' to load your bilingual or multilingual PDF document directly into WPS PDF.
- 3. Run Multilingual OCR: Go to the 'Tools' tab, click 'OCR', and select the specific Cyrillic language to convert unrecognized images into perfectly searchable text.
- 4. Search the Document: Press 'Ctrl + F', type your Cyrillic or Ukrainian text into the search bar, and easily navigate through the accurate results.

Frequently Asked Questions
Why does my PDF search find some languages but not others?
This usually happens when a PDF uses different fonts or encodings for different languages. If the Cyrillic font wasn't properly embedded when the PDF was created, or if the document is a scanned image without multi-language OCR applied, the PDF reader won't recognize the underlying text characters.
How can I tell if my Cyrillic text is an image or actual text?
Try to click and drag your cursor over the Cyrillic words. If a solid blue highlight box covers the whole area like a picture, it's an image and requires OCR. If you can highlight individual letters, it's text, but it may have a font encoding issue if it still isn't searchable.
Does clearing the search cache fix text finding issues?
Yes, sometimes the PDF reader's search index becomes corrupted. You can clear the cache by going to Edit > Preferences > Search, and clicking 'Purge Cache Contents'. After purging, try searching the PDF again so the software is forced to build a new index.
Can incorrect OCR languages cause missing search results?
Absolutely. If you run OCR on a document containing Ukrainian text but the OCR engine is set to English or German only, the software will try to map the Cyrillic shapes to Latin letters. This results in hidden gibberish text that cannot be found when searching for proper Cyrillic words.


