

Fix OCR Text Overlays Original Image When Deskewing Scans in PDF
Question details
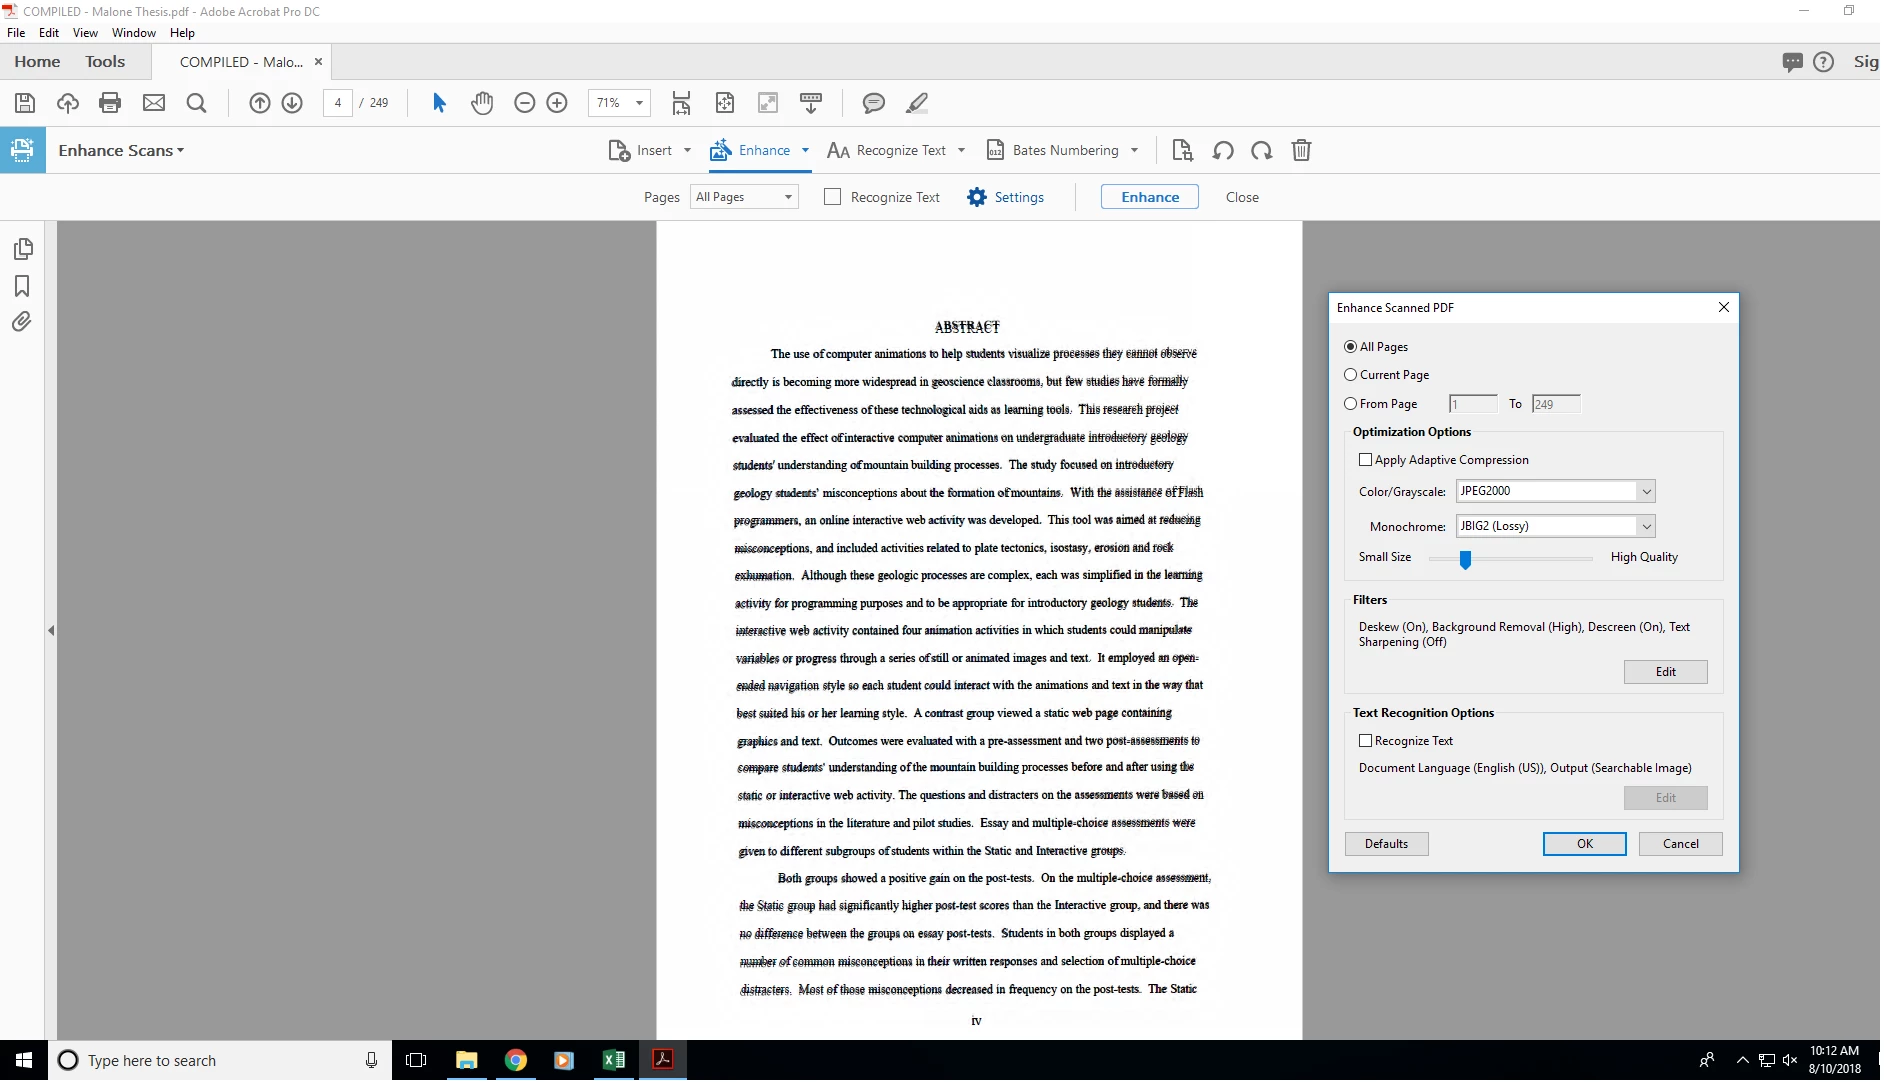
The user is experiencing an issue where recognized OCR text overlaps the original image instead of displaying cleanly after deskewing a scanned document.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Deskewing and applying OCR text recognition to a scanned document.
- Observed behavior
- Recognized OCR text appears visually superimposed over the original scanned image instead of rendering as a clean text document.
Ensure your scanner glass is clean and that the physical document is placed as straight as possible against the scanner's alignment edge to minimize the need for heavy software deskewing.
Adjust OCR Output Options and Quality Settings
Modifying the OCR output style and increasing scan quality can help the software properly separate text from the background image, preventing graphical overlays.
When the 'Low Size to High Quality' slider is set too low, high compression can confuse the OCR engine. Additionally, the choice of OCR output style determines whether text is kept hidden behind the image or replaces the image entirely.
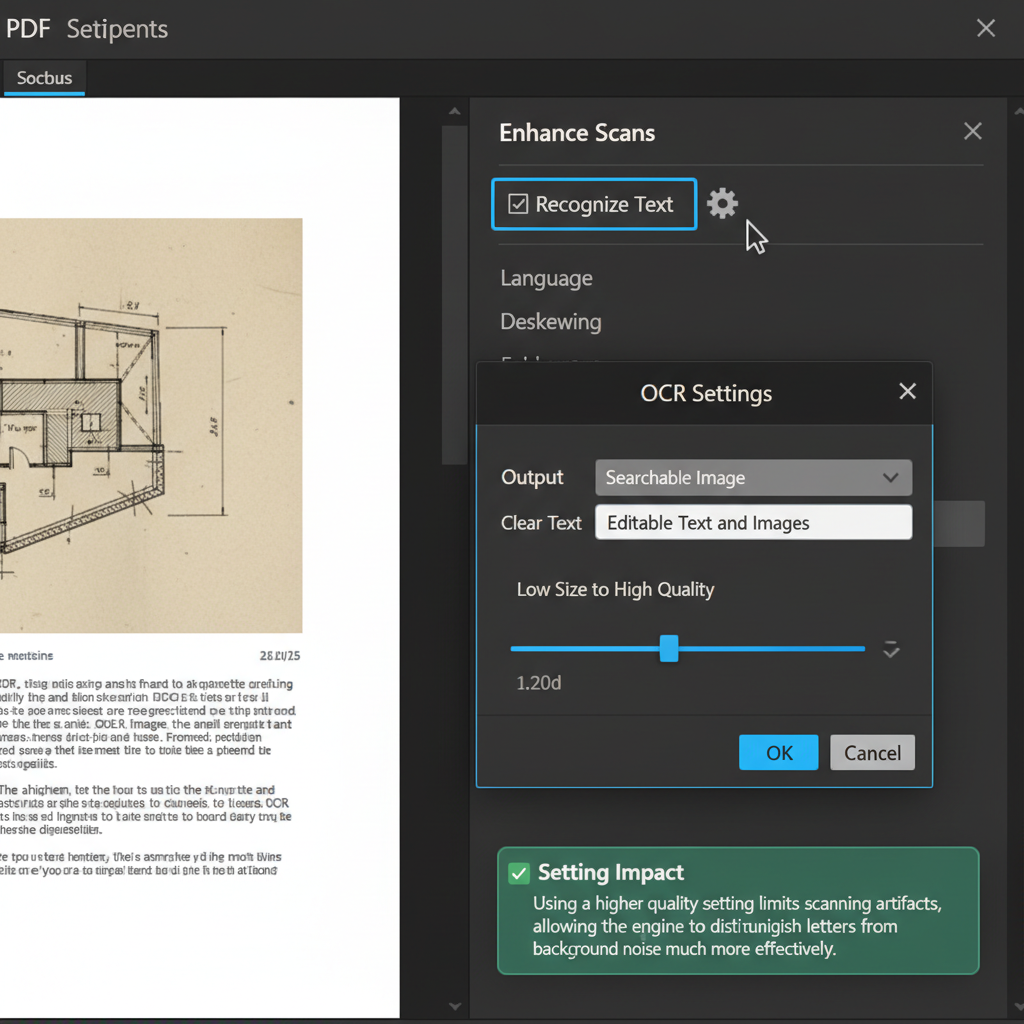
In your PDF editor, open the scanned document, navigate to the 'Enhance Scans' tool, and select 'Recognize Text'.
Click the gear menu icon next to the OCR controls to open the OCR Settings dialog box.
Locate the Output drop-down menu and test all three available options (e.g., switching from 'Searchable Image' to 'Clear Text' or 'Editable Text and Images') to see which resolves the overlay.
Move the 'Low Size to High Quality' slider further to the right to prioritize better image rendering over minor file size savings.
Click OK and run the OCR and deskewing process again to verify if the text now displays cleanly.
Improve Physical Scan Alignment
Reducing the physical skew of the original scan minimizes the processing load on the deskew software, significantly lowering the chance of rendering errors.
Extract Text Cleanly with WPS PDF OCR
Avoid messy text overlays and formatting issues by using WPS Office's built-in PDF tools. WPS PDF offers a highly accurate OCR feature that extracts text cleanly from scanned images and converts them into editable documents without overlapping artifacts.
- 1. Open Scanned PDF in WPS: Launch WPS Office and open your scanned PDF document using the WPS PDF editor.
- 2. Select OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Choose Extraction Method: Select 'Extract Text' to pull plain text, or 'Convert to Word' to retain the document layout without image overlays.
- 4. Start Conversion: Confirm your document language settings and click 'Start' to generate a clean, editable file.

Frequently Asked Questions
What causes OCR text to overlay the original image in a PDF?
This typically happens when the OCR engine is set to output a 'Searchable Image' rather than 'Clear Text', or when aggressive deskewing misaligns the application's hidden text layer from the visible scanned image layer.
Does scan resolution affect OCR text accuracy?
Yes. Scanning at a low resolution or using high compression degrades image clarity. This makes it difficult for the OCR engine to accurately separate text from the background, resulting in visual glitches and misread characters.
How can I completely remove the background image after applying OCR?
In your PDF editor's OCR settings, select an output option like 'Clear Text' or 'Editable Text and Images' instead of 'Searchable Image'. This instructs the software to replace the original scanned picture with actual rendered fonts.
What does deskewing a PDF mean?
Deskewing is an automated software function that detects if a scanned page is tilted or crooked. It rotates the image slightly to make the text lines perfectly horizontal for better readability.


