

Fix PDF Exported to Word Showing Images but No Text

Question details
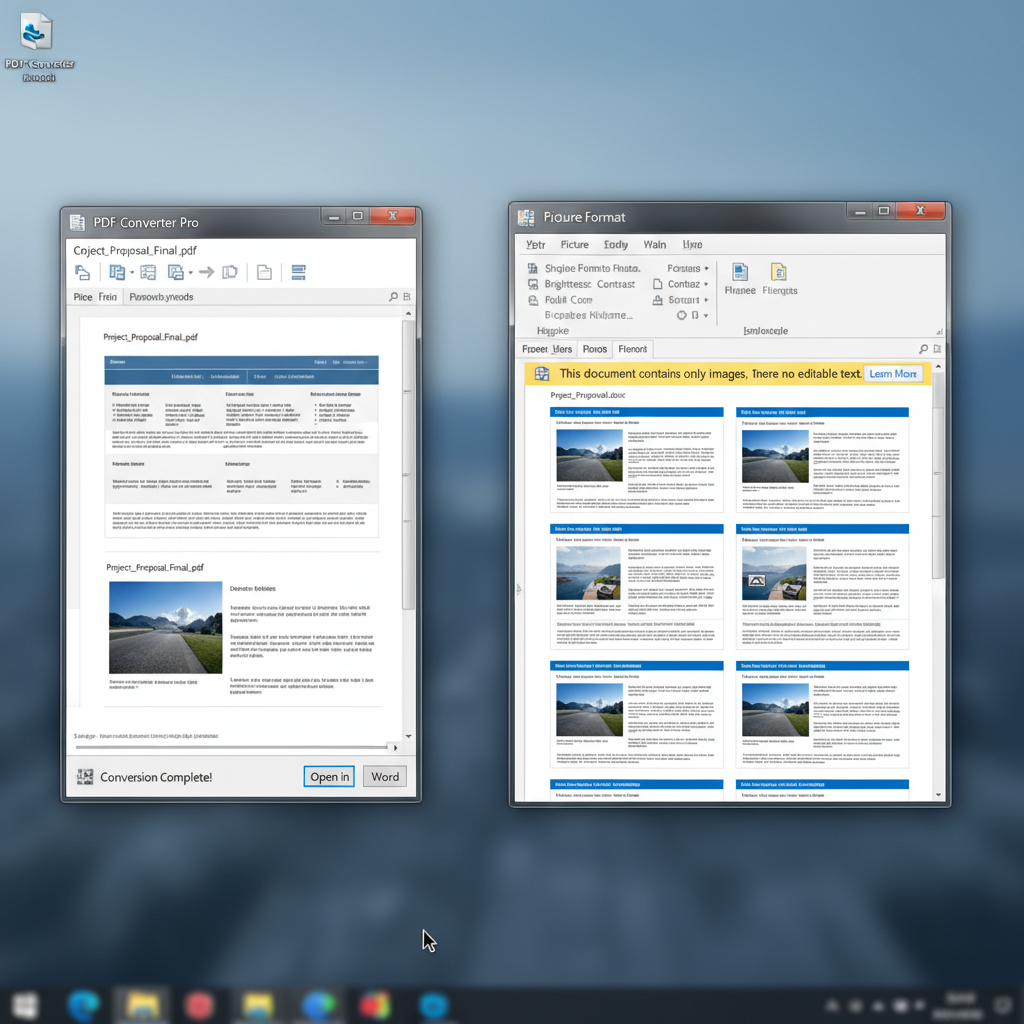
The user is attempting to convert a large PDF into a Microsoft Word document, but the resulting file only contains images without any usable, editable text.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Converting a multi-page PDF document into Microsoft Word format to edit the text content.
- Observed behavior
- The exported Word document successfully retains the layout as images but lacks editable text layers, indicating the source file is likely an image-based or scanned PDF.
Before troubleshooting, try to highlight a sentence in your original PDF using your mouse; if you cannot select individual words and the whole page is selected instead, your document is a scanned image requiring OCR.
Use Optical Character Recognition (OCR) to Extract Text
Standard conversion tools will only convert visual elements. If your PDF is scanned or image-based, you must use an OCR tool to recognize the characters within the images and transform them into editable text.
When dealing with physical documents that were scanned directly into a PDF format, the document does not actually contain text data, only pictures of text. Applying Optical Character Recognition (OCR) scans the image pixels and translates them into machine-encoded text before sending it to Word.
Launch your PDF software and open the problematic, image-based PDF document.
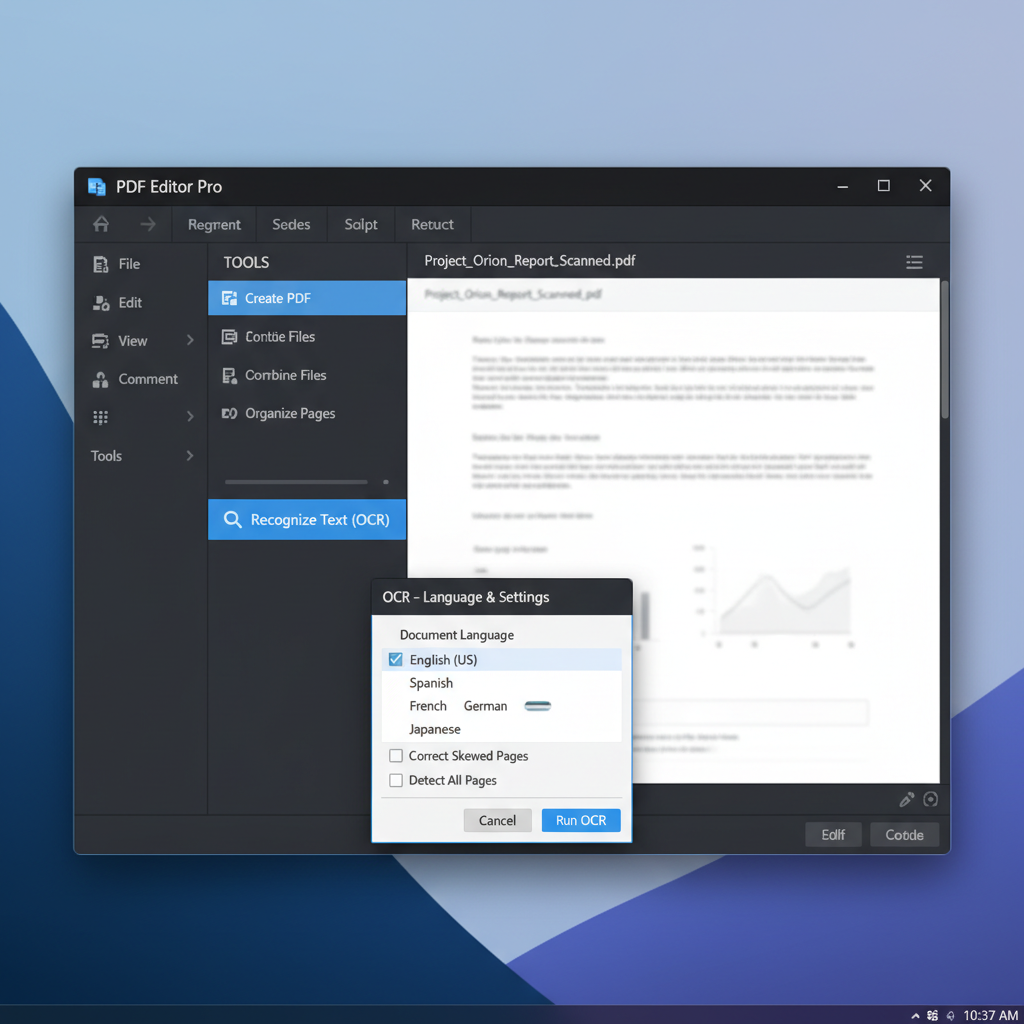
Navigate to the 'Tools' or 'Convert' menu and select the 'OCR' (Optical Character Recognition) feature.
Select the exact language of the document to ensure recognition accuracy, then execute the OCR process to extract text from the images.
Once the OCR scan is complete and the text layers are generated, click 'PDF to Word' or 'Export' to save the newly recognized document as a .docx file.
Test Document Integrity with a Different File
If your PDF isn't a scanned document, it might contain unusual font encoding, damaged text structures, or file-specific corruption that prevents text extraction.
Extract Text from Scanned PDFs Instantly with WPS Office
WPS PDF includes a powerful, built-in Optical Character Recognition (OCR) engine that easily detects text in scanned documents and converts them into fully editable Microsoft Word files, retaining original formats and layouts.
- 1. Open PDF in WPS: Launch WPS Office and open your scanned or image-based PDF file in the WPS PDF interface.
- 2. Select OCR / PDF to Word: Navigate to the 'Tools' tab and click on the 'PDF to Word' button. Check the box to enable OCR if the software detects an image-based file.
- 3. Choose OCR Settings: Select the correct document language to ensure maximum text recognition accuracy and specify the output format as .docx.
- 4. Convert and Edit: Click 'Convert' and wait for the recognition process to finish. The document will automatically open as a fully editable text file in WPS Writer.

Frequently Asked Questions
Why does my PDF behave like a picture when converted to Word?
This happens because the original PDF is likely a scanned physical document. When you scan a paper document, it saves as a flat image. Standard PDF-to-Word converters just copy that image into Word. You need an OCR (Optical Character Recognition) tool to 'read' the text in the image.
How can I check if my PDF requires OCR before converting?
Open the PDF in any viewer and try to highlight or drag your cursor over a specific word. If you cannot select text individually, or if your cursor drags a box over the entire page, the file is image-based and strictly requires OCR to extract the text.
Will converting a large 500-page PDF cause errors or crashes?
Exceptionally large PDFs can consume significant RAM during conversion, especially when OCR is involved, which may lead to timeouts. If you experience errors, consider using a PDF splitter tool to divide the document into smaller batches (e.g., 50-100 pages each) before converting.
Can complex layouts or bad fonts prevent text from exporting?
Yes. If a standard PDF (non-scanned) fails to export text, it may have non-standard font encoding, stripped Unicode mapping, or damaged text structure. 'Printing' the document to a new PDF to flatten it, or treating it as an image and running OCR on it, can often bypass these complex layout issues.


