

Fix Windows Explorer Cannot Search Scanned PDF Text

Question details
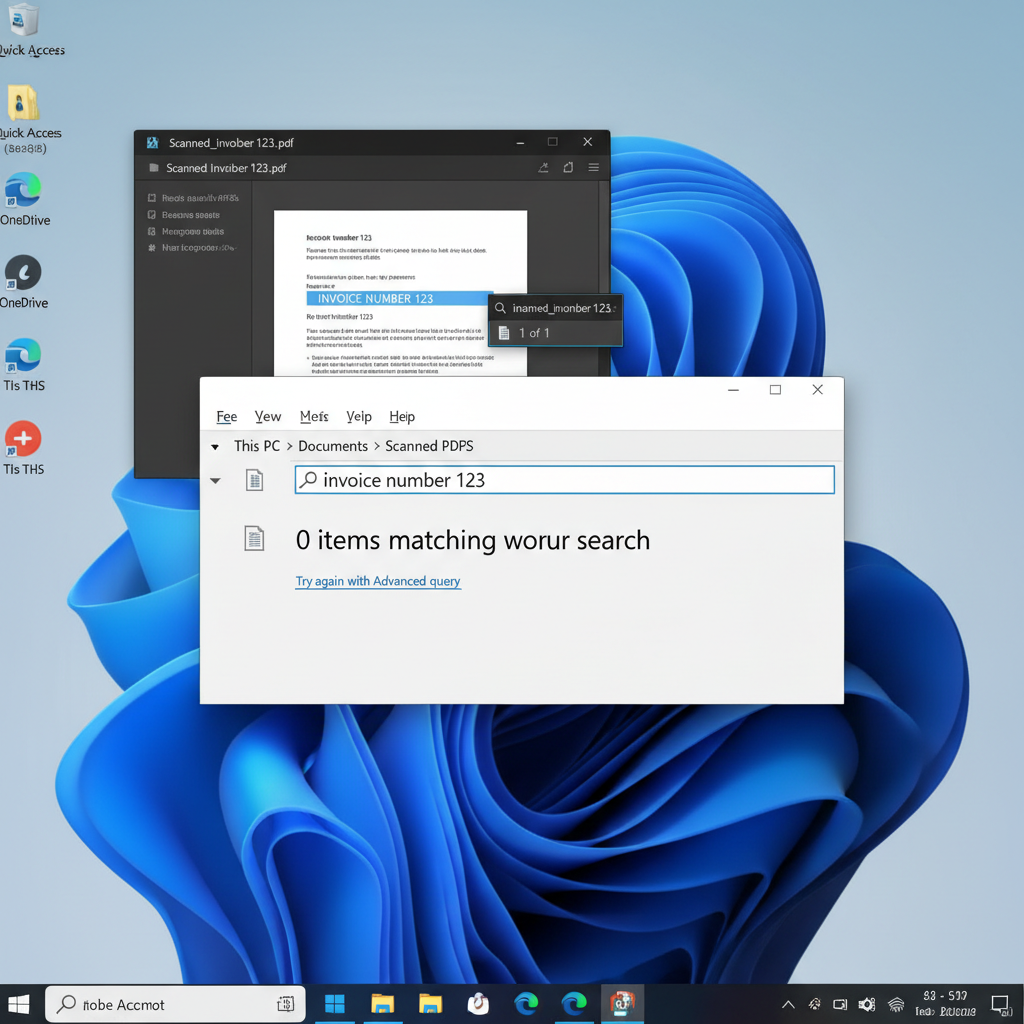
Users are unable to search for specific text inside scanned PDFs using Windows Explorer Search, despite the text being OCR processed and searchable within dedicated PDF readers like Adobe Acrobat.
- Product
- Windows Explorer Search
- Device & OS
- Windows
- Scenario
- Attempting to locate specific scanned PDF files by typing keywords contained within their document text into the Windows File Explorer search bar.
- Observed behavior
- Windows Explorer Search returns zero results for the text contained within the scanned PDFs, whereas searching for the exact same text inside the opened document via a PDF reader works perfectly.
Verify that your PDF document actually contains a searchable text layer by opening it in a PDF reader and attempting to highlight individual words with your cursor.
Configure PDF iFilter and Rebuild Windows Search Index
Windows requires a specific PDF iFilter to read the internal contents of PDF files. Enabling this and rebuilding the index ensures Windows Explorer can scan PDF text.
By default, Windows indexes file names and properties, but it relies on iFilters to read the text inside specific file formats. If the PDF iFilter is missing or incorrectly configured, Windows will ignore the OCR text inside your PDFs.
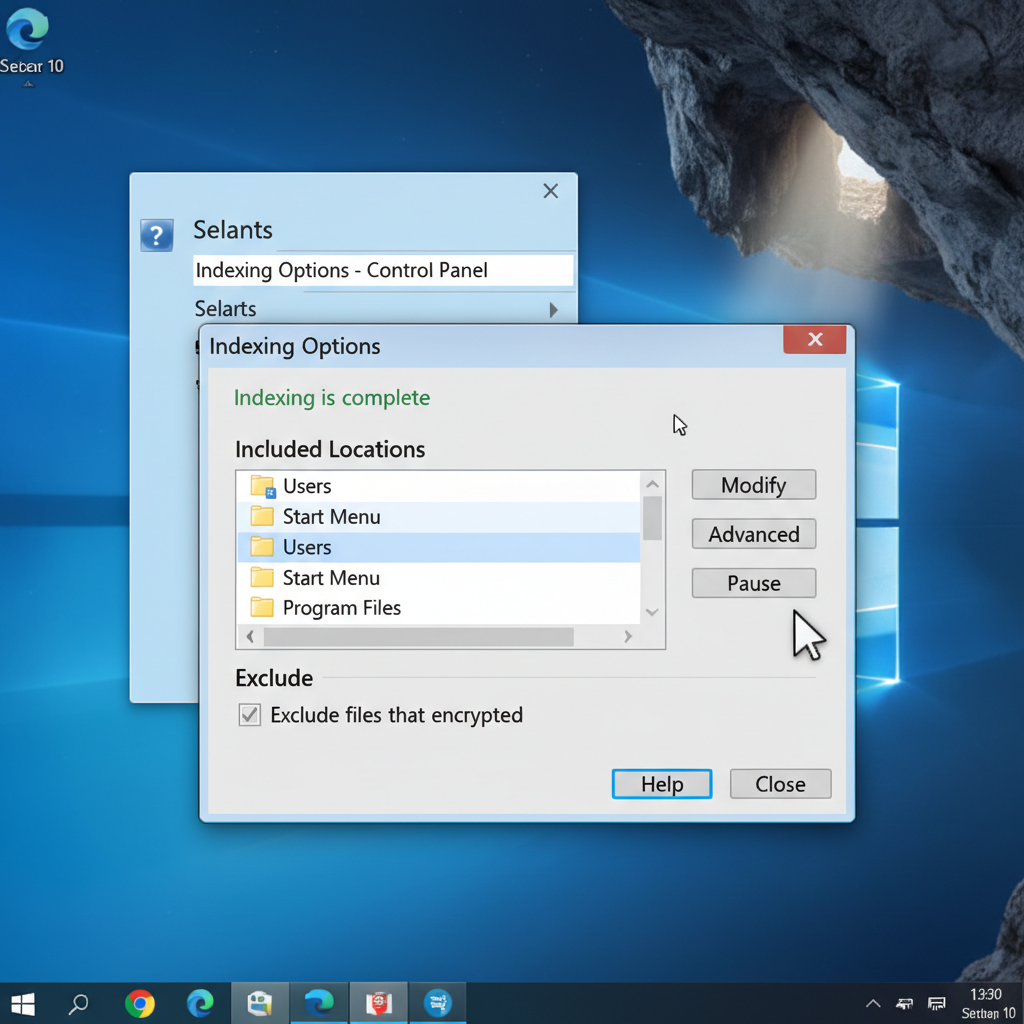
Click the Windows Start button, type 'Indexing Options' into the search bar, and press Enter to open the settings window.
Click the 'Advanced' button and navigate to the 'File Types' tab. Scroll down to find the '.pdf' extension in the list.
Select the '.pdf' extension, and under 'How should this file be indexed?', select the radio button for 'Index Properties and File Contents'. Click OK.
Return to the main 'Advanced Options' window under the 'Index Settings' tab. Click the 'Rebuild' button in the Troubleshooting section to force Windows to re-scan your files with the new rules.
Convert the Scanned Image to a Fully Searchable PDF
If the OCR text is not saved as a proper embedded text layer, Windows Explorer will not be able to detect it, even if your PDF reader handles it dynamically.
Make Scanned PDFs Searchable with WPS Office
WPS Office provides a powerful, built-in PDF editor equipped with highly accurate OCR technology. It allows you to easily convert scanned images and documents into fully searchable PDF files, ensuring Windows Explorer and other applications can index your text seamlessly.
- 1. Open your Scanned PDF: Launch WPS Office and open the scanned document you want to make searchable.
- 2. Access the OCR Feature: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Choose Searchable Output: In the extraction options, select 'Searchable PDF' to ensure the recognized text is embedded as a hidden text layer over the image.
- 4. Save the Document: Save the new file to your drive. The embedded text is now permanently integrated and ready to be found by Windows Search.

Frequently Asked Questions
How do I check if my PDF already has a searchable text layer?
Open the PDF in any standard PDF reader. Try to click and drag your mouse cursor over the text. If you can highlight individual words and copy them to your clipboard, the PDF contains a searchable text layer. If it only highlights the entire page as a single image box, it is not searchable.
Why does Acrobat search work when Windows Explorer search does not?
Acrobat uses its own proprietary internal search engine to scan the document's structure, including dynamically generated OCR data. Windows Explorer, however, relies on the Windows Search Index, which needs a properly installed PDF iFilter to extract and index text directly from the file system.
Does rebuilding the Windows Search index delete or alter my files?
No, rebuilding the index only deletes and recreates the internal background database that Windows uses to quickly locate files and file contents. Your actual documents, folders, and system files remain completely safe and untouched during this process.
What is a PDF iFilter and how do I get one?
A PDF iFilter is a Windows add-on component that allows the Microsoft indexing engine to open PDF files, read their internal text layers, and add that text to the system search index. Many PDF readers, including Adobe Acrobat and Foxit, bundle an iFilter with their software, or you can download standalone iFilters from official provider websites.


