

How to Check if a PDF Contains Searchable Text using JavaScript

Question details
The user wants to programmatically determine whether a PDF document contains searchable text using JavaScript, as standard API properties do not evaluate the actual document content.
- Product
- Device & OS
- not provided
- Scenario
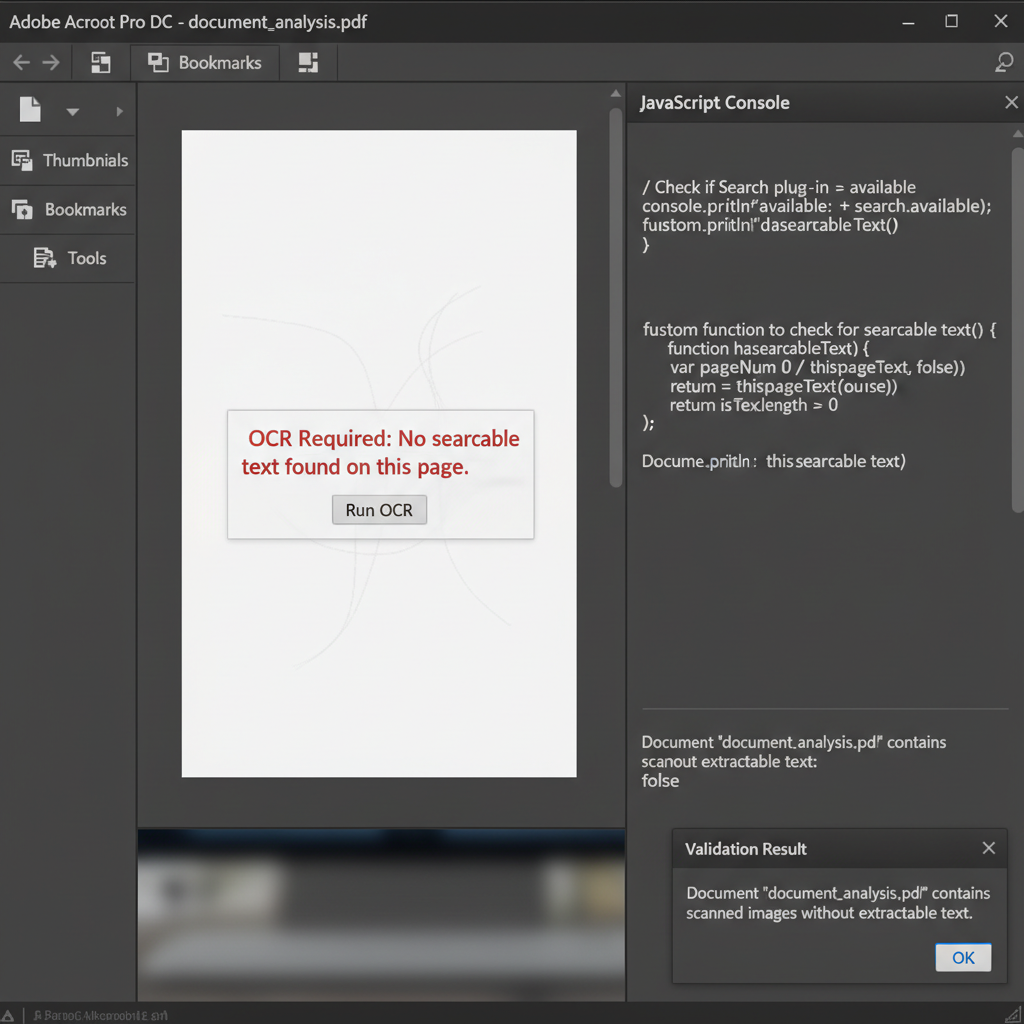
- Writing a JavaScript macro or script to validate whether PDF pages contain actual extracted text or just scanned images requiring OCR processing.
- Observed behavior
- The search.available property returns true if the Search plug-in is loaded, but it does not inspect the document to verify if text is actually present or searchable.
Before running the script, ensure you have access to a PDF editor with JavaScript console capabilities to execute and test document-level scripts.
Use the getPageNumWords Method to Count Text
Iterate through the PDF pages using a script to check for the presence of extracted text words, which indicates searchable content.
PDFs do not inherently tag files as 'searchable.' A practical workaround to test for searchable text is iterating through the pages and counting the recognized words.
The search.available property should not be used for this purpose, as it only checks if the Search plug-in is loaded and ready for API calls, completely ignoring the document's content.
Launch your advanced PDF editor (like Adobe Acrobat Pro) and open the JavaScript Debugger or interactive console.
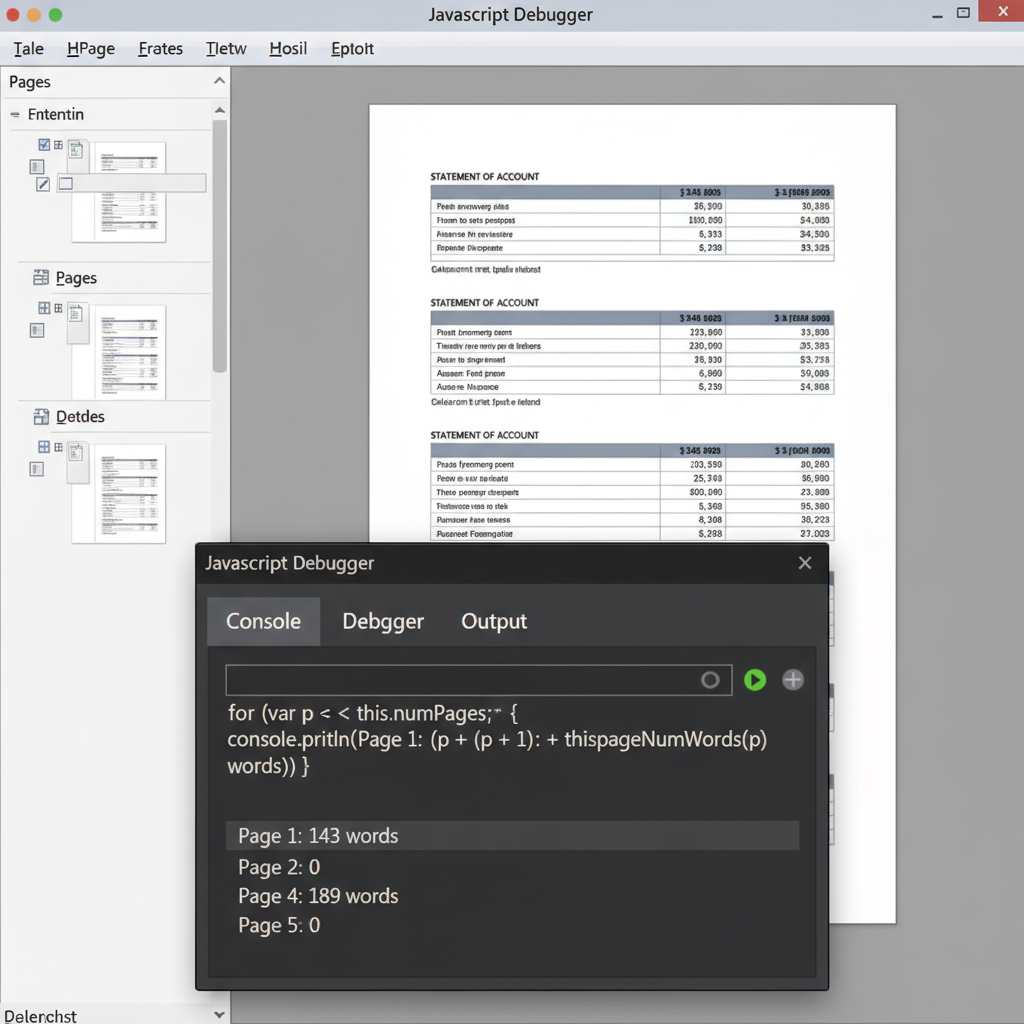
Input a loop to check each page. For example: for (var p = 0; p < this.numPages; p++) { console.println('Page ' + (p + 1) + ': ' + this.getPageNumWords(p) + ' words'); }
Run the script. A printed output will display the total number of extracted words per page. Pages returning zero words are likely image-based and require OCR.
Use WPS Office to Detect and OCR Non-Searchable PDFs
Instead of relying on complex JavaScript APIs to check for searchable text, you can use WPS Office PDF to visually identify scanned documents and instantly convert image-based pages into fully searchable and editable text with its built-in OCR feature.
- 1. Open your PDF file: Launch WPS Office and open the PDF document you want to check.
- 2. Test text selection: Attempt to highlight the text with your cursor. If the entire page highlights as a single block, it is an image and not searchable.
- 3. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and select the 'OCR' feature.
- 4. Convert the document: Choose the option to convert the document into a searchable PDF or extract the text, then save your newly searchable file.

Frequently Asked Questions
Why does search.available return true on a scanned PDF?
The search.available property only verifies if your PDF reader's Search plug-in is loaded and query capabilities are active. It does not analyze the content of the PDF itself, which is why it returns true even on documents that consist entirely of unsearchable images.
Does a positive word count guarantee all text is searchable?
No. A PDF page can contain a mix of searchable text elements and flattened images of text. The getPageNumWords method only counts the recognized text layer, completely ignoring any text trapped inside rasterized images.
What does it mean if getPageNumWords returns zero?
If the method returns zero words for a page, the page likely consists entirely of images, vectors, or scanned content. You will need to process the page with Optical Character Recognition (OCR) software to extract and embed a searchable text layer.


