

How to Determine Whether a PDF Contains OCR Text

Question details
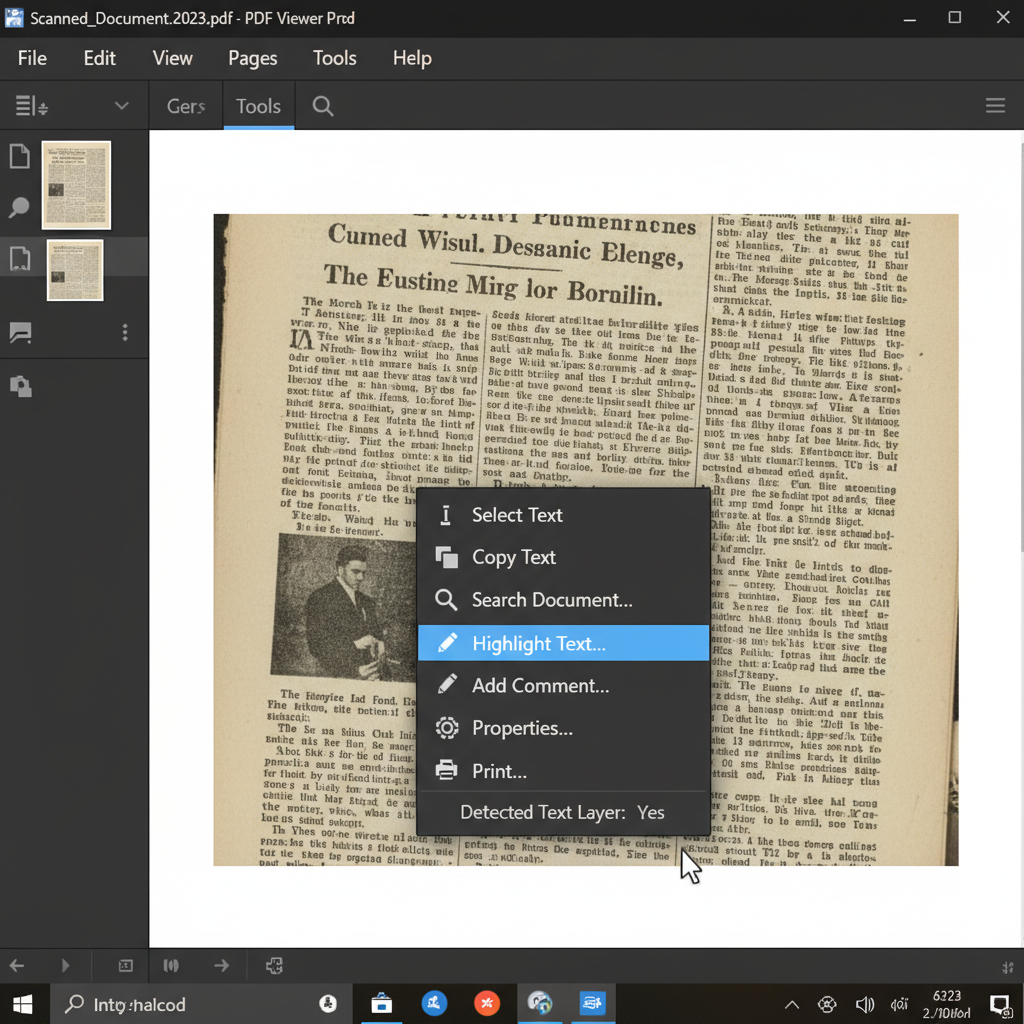
The user wants to find out if a specific PDF document has undergone Optical Character Recognition (OCR) and contains an interactive text layer.
- Product
- Device & OS
- not provided
- Scenario
- Verifying the properties or content of a scanned PDF file to see if the text inside can be searched, selected, or copied.
- Observed behavior
- Because standard PDF files do not include a reliable metadata property that explicitly states whether OCR was performed, users need a practical method to test the document for hidden text layers.
Ensure you have a standard PDF reader installed and open the document you wish to test on your computer.
Test for Selectable and Searchable Text Layers
Since there is no explicit file property for OCR, the most practical method is to manually interact with the document's content.
When a scanned document is processed with OCR, a hidden text layer is placed over or behind the original scanned image. By attempting to interact with this layer, you can easily verify if OCR has been applied.
Launch your PDF reader and open the file you want to check.
Click and drag your mouse cursor over the words on the page. If the text highlights and can be copied to your clipboard, an OCR text layer is present.
Press Ctrl + F (or Cmd + F on Mac) to open the search bar. Type a visible word from the document. If the PDF viewer finds and highlights the word, the document has been OCR processed.
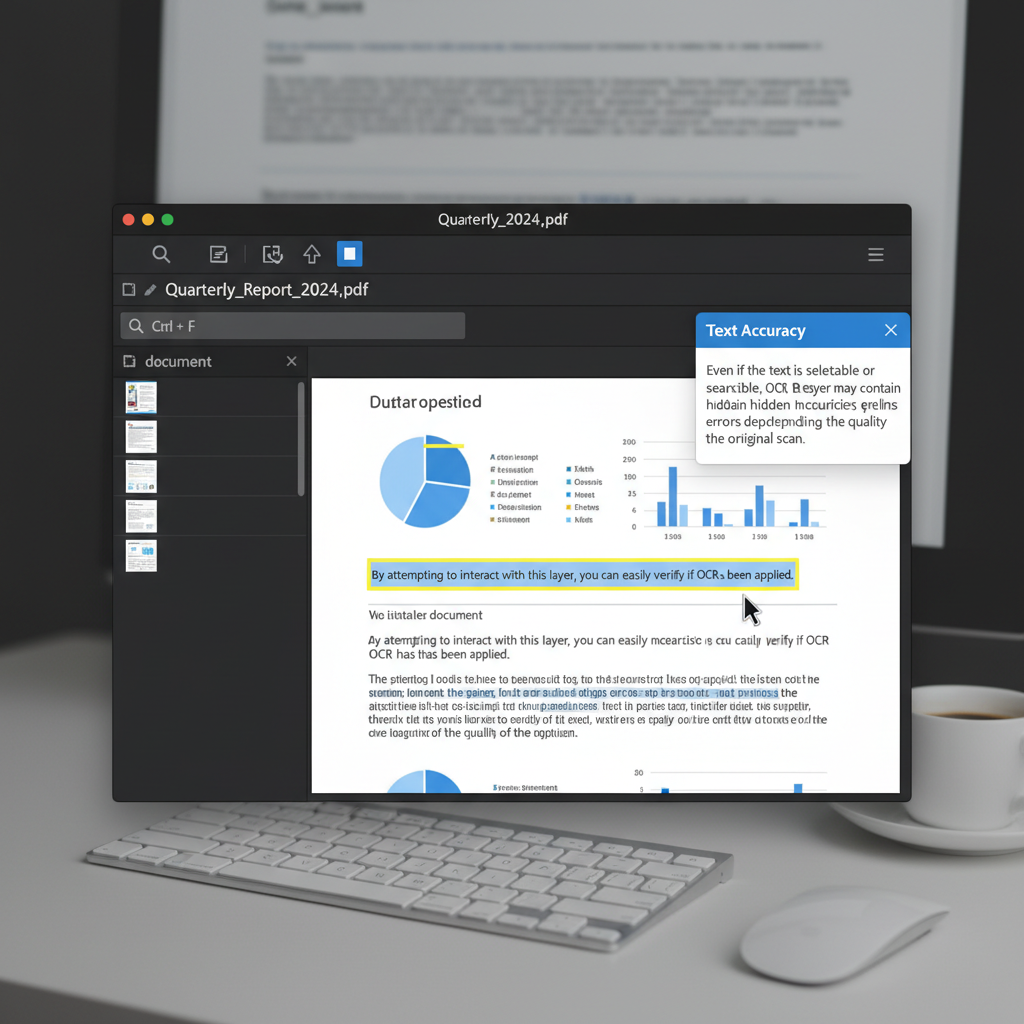
Easily Perform OCR on Scanned PDFs with WPS Office
If your PDF does not contain an OCR text layer, you can quickly extract or edit the text using the built-in OCR feature in WPS Office.
- 1. Open your PDF in WPS Office: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Access the OCR feature: Navigate to the 'Tools' tab at the top of the interface and click on the 'OCR' button.
- 3. Extract or Convert: Follow the prompts to extract the recognized text directly or convert the entire scanned PDF into a fully editable Word document.

Frequently Asked Questions
Is there a specific file property that shows OCR was applied?
No, standard PDF metadata does not include a reliable property to indicate whether OCR has been performed. Manually attempting to select or search text remains the most accurate test.
Why can't I select text in my PDF file?
If you cannot select, highlight, or search for text, the PDF is likely an image-only file. This usually happens when a document is created directly from a scanner or camera and has not yet been processed with an OCR tool.
Can I apply OCR to a PDF if it doesn't have selectable text?
Yes. You can use dedicated PDF editors like WPS Office, which feature built-in OCR tools, to scan the image-based document and convert the visual text into fully selectable and editable text.


