

How to Tell Whether a PDF Has Been OCR Processed

Question details
The user needs to figure out if a PDF file has already been processed with Optical Character Recognition (OCR).
- Product
- Device & OS
- not provided
- Scenario
- Reviewing or managing PDF documents that may be scanned images to see if they contain recognizable text.
- Observed behavior
- The user wants to verify if the text inside the PDF is selectable or searchable, rather than just being a flat image.
Ensure you have a PDF reader installed, such as WPS Office, that allows you to open the document and interact with the text directly.
Test Text Selectability and Searchability
The most reliable way to check for OCR is to interact with the document's text directly.
Because PDF properties do not reliably identify whether OCR was performed, the most straightforward approach is to see if the document behaves like a text document or an image file.
Launch your PDF reader and open the document you wish to test.
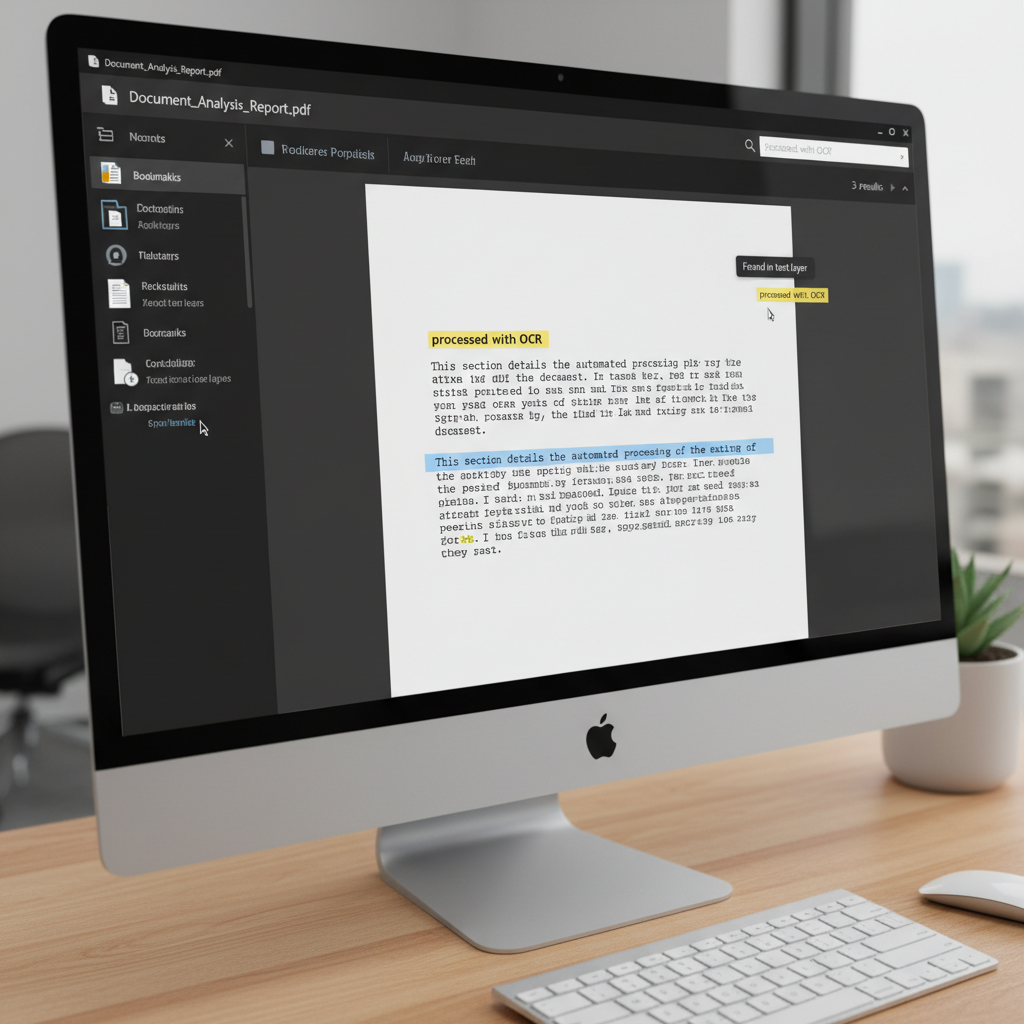
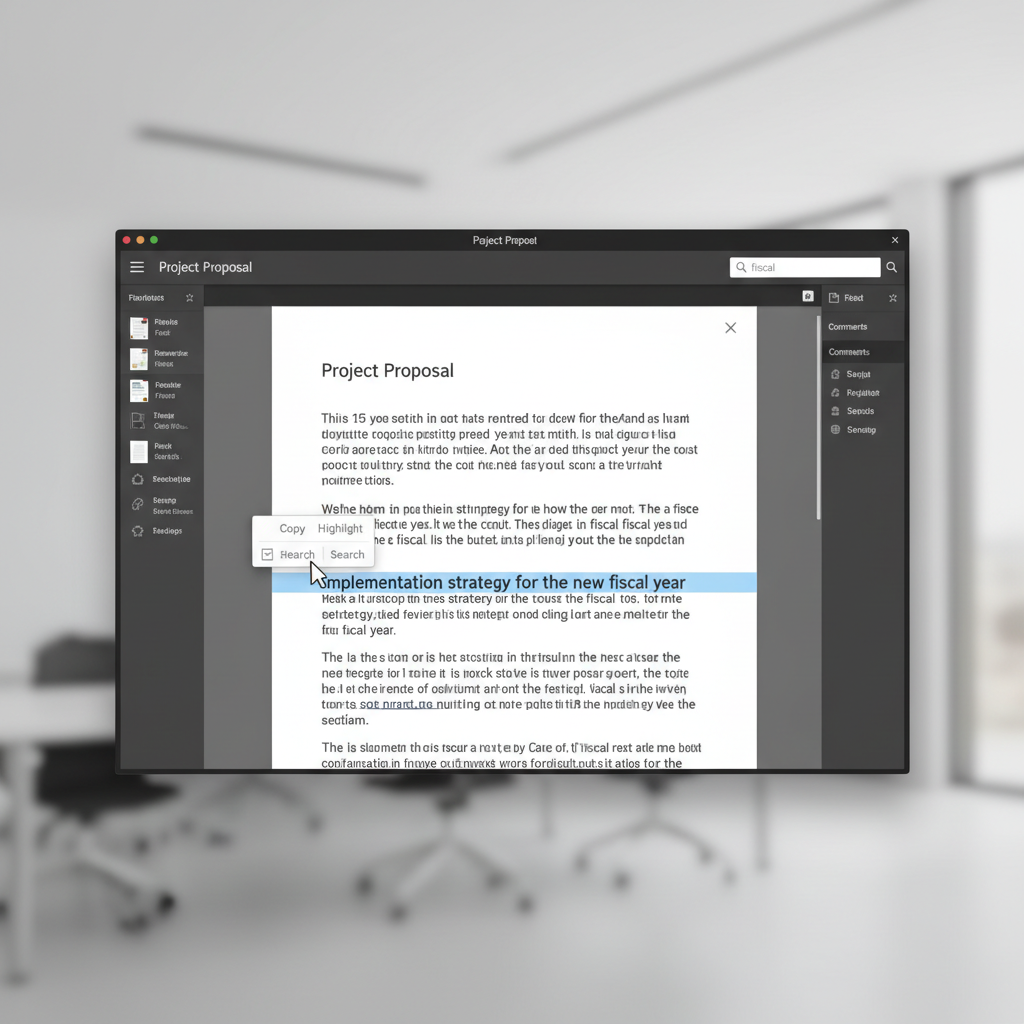
Click and drag your mouse cursor over a paragraph or block of text. If the cursor changes to an I-beam and highlights individual letters and words, the document has a text layer, meaning OCR was likely applied if it's a scanned file.
Press Ctrl+F (or Cmd+F on Mac) to open the search bar. Type a word you can clearly see on the page. If the search locates and highlights the word, the PDF is searchable and has been OCR processed.
Check PDF Document Properties and Metadata
Examine the document's properties for clues about the software used to create or process it.
Add Custom Metadata or Keywords for Tracking
If you process PDFs yourself, establish a habit of tagging them to easily identify OCR'd files in the future.
Easily Recognize Text in Scanned PDFs with WPS Office
If your PDF hasn't been OCR processed, WPS Office provides a powerful, built-in OCR tool to instantly convert scanned images into selectable, searchable, and editable text.
- 1. Open the scanned PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon.
- 3. Initiate OCR: Click the 'OCR' button to start the text recognition process.
- 4. Select output format: Choose whether to extract text to a plain document or convert the entire layout to an editable Word/Excel file, then click confirm.

Frequently Asked Questions
Why can't I select text in my PDF even though it looks like text?
If you cannot select text, the PDF is likely a flat image created by a scanner or exported from a graphic design program. OCR (Optical Character Recognition) has not yet been applied to identify those pixels as characters.
Does OCR change the appearance of my original PDF document?
Standard OCR usually adds an invisible layer of text perfectly aligned behind the scanned image. This allows you to search and copy text without altering the original visual layout of the document.
Can I batch check multiple PDFs to see if they are OCR processed?
Because standard PDF properties don't universally indicate OCR status natively, batch checking requires specialized third-party document management software that can scan multiple files to verify if they contain searchable text layers.


