

How to Convert a Bilingual English and Hindi PDF using OCR

Question details
The user needs to convert a scanned bilingual PDF containing both English and Hindi (Devanagari script) text into an editable format using OCR.
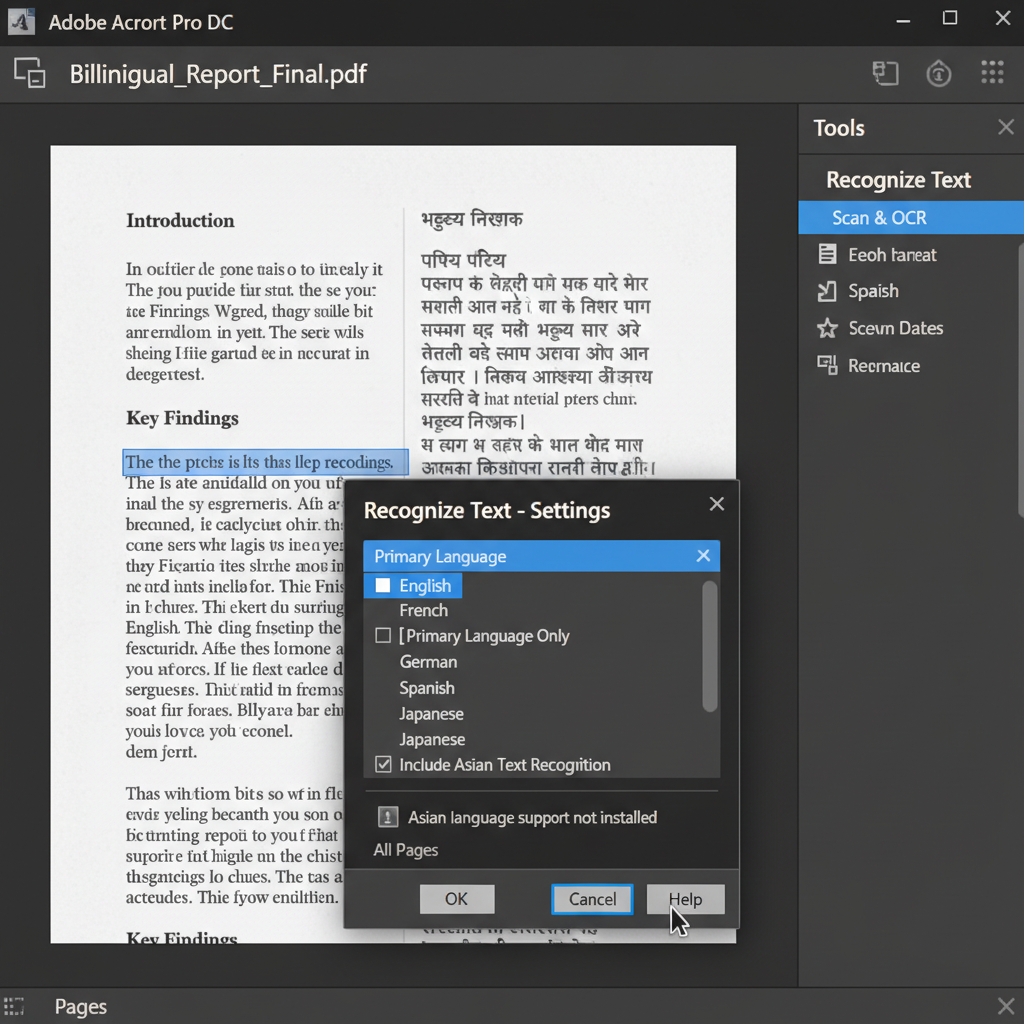
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to perform OCR text recognition on a scanned document that features two distinct languages and scripts simultaneously.
- Observed behavior
- The OCR software lacks native support for Hindi in its default language list or only processes one language at a time, causing the Devanagari script to be ignored or recognized incorrectly.
Before attempting to convert the file, check if your OCR software natively supports the Devanagari script. If Hindi is unsupported in your primary tool, you will need to process the English text first and rely on a specialized OCR service for the Hindi portions.
Process English Text First and Use Specialized OCR for Hindi
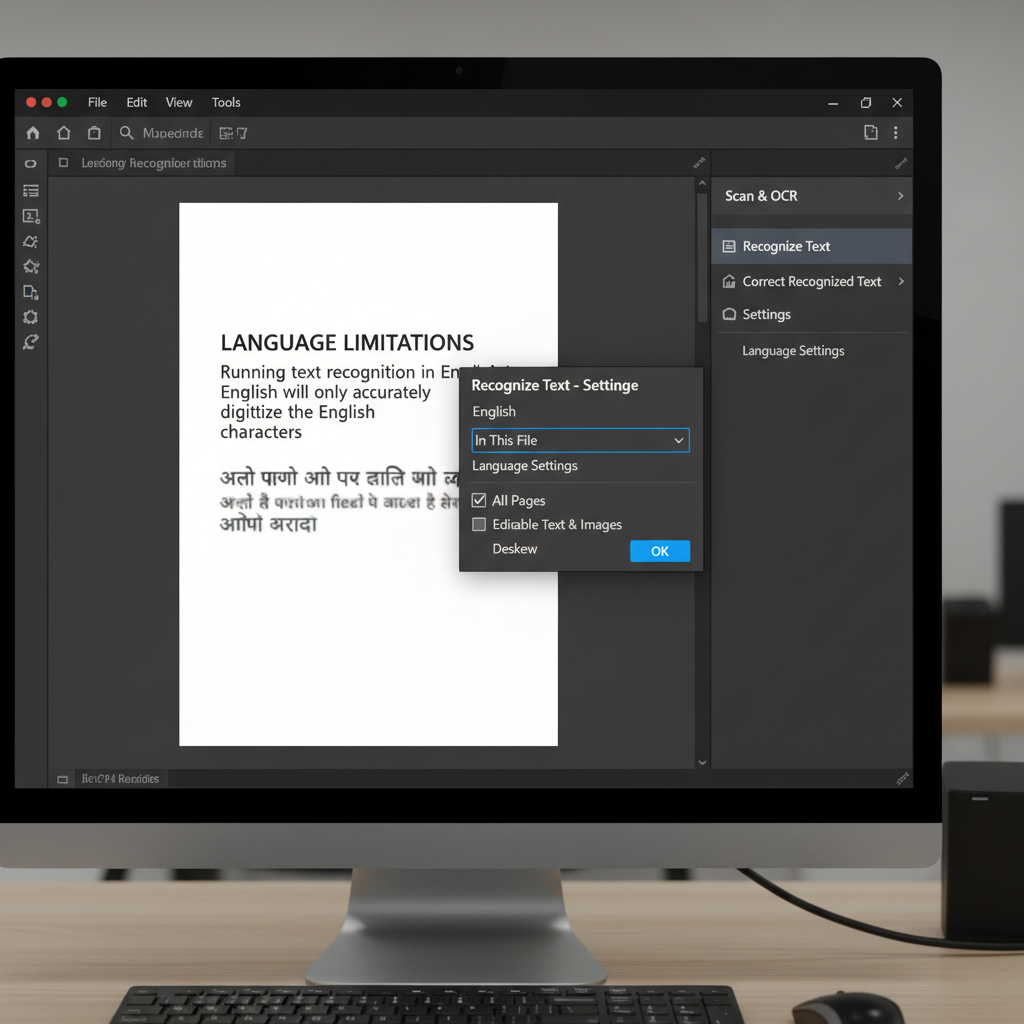
Since some OCR engines process one language at a time and may lack native Hindi support, you can recognize the English parts first and handle the Hindi text using a secondary tool.
Most standard OCR engines, including older versions of Adobe Acrobat, restrict text recognition to one primary language at a time and might not include Hindi in their default language packs.
Launch your PDF editor and open the scanned bilingual PDF document.
Navigate to the 'Scan & OCR' tool. Select 'Recognize Text' and ensure the recognition language is set to English. This allows the software to extract the English text while ignoring the unreadable Hindi text.
Save or export the processed document to Word or plain text to preserve the successfully recognized English portions.
For the remaining Devanagari text, upload the original scanned document to an alternative OCR software or an online tool that specifically supports Hindi text recognition.
Copy the newly extracted Hindi text and paste it into the Word document containing your English text to complete the bilingual conversion.
Easily Extract Text from Scanned PDFs with WPS Office
WPS Office provides powerful PDF editing and OCR (Optical Character Recognition) features that simplify extracting text from scanned documents, offering high compatibility with complex layouts and multiple formats.
- 1. Open PDF in WPS: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and click on the 'OCR' or 'PDF to Word' button.
- 3. Configure extraction settings: In the extraction prompt, choose 'Extract Text' or select the desired output format (like Word) to preserve the document layout.
- 4. Convert to Editable Format: Click the 'Convert' button to process the scan and generate an editable document containing your text.

Frequently Asked Questions
Why does my OCR software output gibberish for Hindi text?
This happens when the OCR engine is set to English or another language and attempts to read the Devanagari script using the wrong character set. You must select Hindi as the recognition language if your software supports it.
Can I recognize two languages simultaneously in a scanned PDF?
It depends on the OCR software. Some advanced tools allow you to select multiple languages (e.g., English and French) before running the scan, while others require you to process the document one language at a time.
How do I fix missing Hindi fonts after converting my PDF to Word?
If the Hindi text was recognized correctly but displays as boxes or weird symbols in Word, ensure you have a standard Devanagari font (like Mangal, Aparajita, or Kruti Dev) installed on your system and apply it to the affected text.


